fg-data-synthetic: a GAN and Gaussian Mixture toolkit for tabular and time-series synthesis
Synthetic data generators for tabular and time-series data
At a glance
- What is it?
- The package, formerly ydata-synthetic, ships six GAN variants plus a Gaussian Mixture fast path, a Streamlit UI, and a migration path from the old import name. It is a research-oriented toolkit, not a managed service, and the README is thin on evaluation and on what happens after generation.
- Who is it for?
- Adopt fg-data-synthetic if you are comfortable running PyTorch or TensorFlow 2.0 yourself and you want several GAN architectures plus a CPU-friendly Gaussian Mixture baseline under one import. Do not adopt it if you need built-in privacy guarantees, automated quality scoring, or a supported managed pipeline; the README describes generation, not verification, and points to a separate commercial product for the end-to-end flow.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 73 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
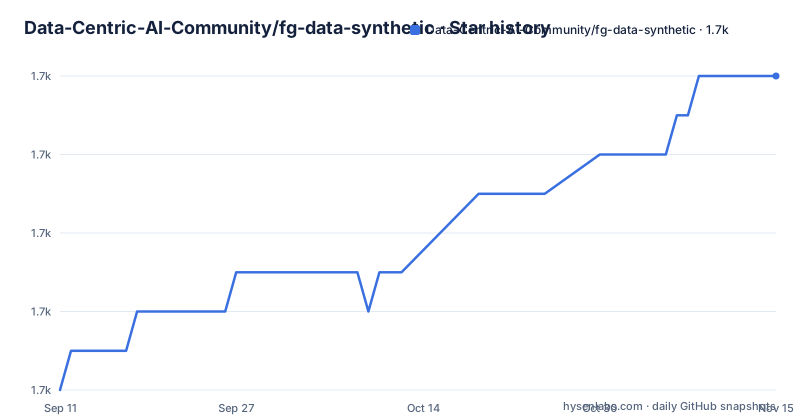
- Data-Centric-AI-Community/fg-data-synthetic1,664 ★ · +8
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Data-Centric-AI-Community/fg-data-synthetic | 1.7k | 1.7k |
8 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem fg-data-synthetic addresses, and who is expected to use it
Synthetic data is generated by a model rather than collected as direct observations. The README describes it as replicating statistical patterns without identifiable information; this is a project claim, not a privacy guarantee. A model can reproduce or expose information about its training records, so assess disclosure risk before sharing generated data. The package exists to produce that data for two shapes of input: tabular tables and time series. It is a library, not a platform. You install it, import a synthesizer, fit it on a dataframe, and sample from it. That places the audience somewhere specific: data scientists and ML engineers who already have a dataframe or a sequence dataset and want a second, artificial version of it. The README lists four intended applications: privacy compliance for data sharing and ML development, bias removal, dataset balancing, and augmentation. Those are four different jobs with four different success criteria, and the README does not distinguish between them. Balancing a rare class and releasing a privacy-safe copy of a customer table are not the same task, and a single GAN checkpoint will not serve both equally. The repository is a community project under the Data-Centric-AI-Community organisation, MIT licensed, with the default branch named dev. The last push recorded is 2026-09-03.
Six GAN variants, one Gaussian Mixture fast path, and the CTGAN conditional architecture
The README names the models the Streamlit app supports: CGAN, WGAN, WGANGP, DRAGAN, CRAMER, and CTGAN. All the deep learning models, per the README, are implemented on TensorFlow 2.0, though the repository topics also list PyTorch and the primary language is Jupyter Notebook, so expect the codebase to be mixed. CTGAN is described as a conditional architecture for tabular data, which is the mechanism that matters for mixed-type tables: conditional generation lets the model treat discrete columns separately rather than pretending an integer category is a continuous number. The Gaussian Mixture model is the one to look at first if you have no GPU. The README frames it as a way to quickstart without GPU hardware, which is a real constraint for most people evaluating a synthetic data tool. The trade-off is implicit but clear: a Gaussian Mixture fits a weighted sum of Gaussian components to your columns. It does not use an adversarial training loop. Runtime and output depend on the data, implementation, initialization and settings; evaluate its fidelity for the intended use. For time series the README points to TimeGAN and DoppelGANger through the example notebooks rather than through the Streamlit model list, which suggests the UI flow is tabular-only. Do not assume the UI covers sequential data.
Getting it running: pip, the Streamlit extra, and the rename from ydata-synthetic
The package was renamed. If you have the old package installed, the migration guide gives three steps. First, pip uninstall ydata-synthetic. Second, pip install fg-data-synthetic. Third, find and replace the import. The README shows the before and after explicitly: import ydata_synthetic and from ydata_synthetic.synthesizers.regular import RegularSynthesizer become import data_synthetic and from data_synthetic.synthesizers.regular import RegularSynthesizer. The guide also provides a grep one-liner to locate affected files: grep -r "ydata_synthetic" . --include="*.py". Run that before you upgrade, because a partial rename produces an ImportError at runtime, not at install time. For the UI flow, install the extra with pip install fg-data-synthetic[streamlit], then either call it from a Python file with from data_synthetic import streamlit_app followed by streamlit_app.run(), or run the example script with python -m streamlit_app. The README is explicit that the streamlit_app.run() snippet must live in a Python file and that Jupyter Notebooks are not supported for that entry point. That is an unusual and easily missed constraint. The package targets Python 3.9 and 3.10 according to the badge in the README.
What the documentation does not tell you: evaluation, privacy, and the missing quality loop
The README describes how to generate synthetic data and says nothing about how to check whether the result is any good. The word privacy appears once, in the definition of synthetic data, as a property the data has rather than something the library verifies. That is the largest gap. A GAN trained on a small table can memorise rows, and nothing in the described workflow would catch it. The README does point elsewhere for this: it advertises YData Fabric as an end-to-end solution covering data preparation, generation, and, in its own words, evaluation, with a community version linked. So the project's own position is that evaluation lives in the commercial product, not in this package. Treat that as the boundary of what you are adopting. The second gap is versioning. The release history shows 2.0.0 in September 2024, then 2.0.1 and 2.1.0 both dated 2026-04-23, which is a long quiet period followed by two releases on the same day. Read the release notes before pinning a version.
Where a Gaussian Mixture beats a GAN, and where both lose to plain resampling
The honest alternative for many tabular use cases is not another synthesis library. It is SMOTE-style interpolation or conditional resampling from the empirical distribution. Simple resampling can be a useful baseline for class balancing, but its suitability and cost depend on the data and method. Plain resampling draws from observed records; interpolation methods such as SMOTE can create new feature values and require their own validation. A Gaussian Mixture can, because it fits a joint density and samples from it. A GAN can produce even more novel combinations, at the cost of a training loop that can diverge and a model that needs tuning. So the decision is about how much novelty you need. If your downstream model only needs more examples of rare combinations that are already plausible, the Gaussian Mixture path in this package is the right entry point and the README positions it that way. If you need to model conditional structure across many discrete columns, CTGAN is the architecture the README highlights. If you need a managed pipeline with evaluation built in, this repository is not that, and the README says so by directing you to YData Fabric.
Maintenance surface: notebooks, a dev branch, and an MIT licence with no warranty
The primary language is Jupyter Notebook, and the README leans on notebooks heavily: Colab links for Fast_Adult_Census_Income_Data, CTGAN_Adult_Census_Income_Data, TimeGAN_Synthetic_stock_data, and DoppelGANger_FCC_MBA_Dataset. Notebooks are good for demonstration and poor for pinning. When you move a notebook into a pipeline you inherit whatever the notebook assumes about column order, dtype inference, and preprocessing, and none of that is specified in the README. Budget time for that translation. The default branch is dev, not main, which means the installable release and the branch you read on GitHub are not the same artefact; check the tag rather than the branch when you want to know what you installed. The licence is MIT. That is permissive: it allows commercial use and modification, and it comes with no warranty and no patent grant. It says nothing about the data you generate. Whether synthetic output derived from personal data is itself personal data under GDPR or similar regimes is a legal question this package does not answer, and the MIT licence does not address it either. Get that reviewed separately if you plan to share generated data outside your organisation.
A concrete way to decide in an afternoon
Install with pip install fg-data-synthetic[streamlit], run the grep migration check if you had the old package, and open the Fast_Adult_Census_Income_Data notebook. It uses the Gaussian Mixture path, so it runs without a GPU and tells you quickly whether the generated columns look like your own. Then take one real table of yours, fit the same synthesizer, and compare the marginal distributions of two or three columns by hand. The README does not document a scoring function; compare utility, relationships between columns, and privacy leakage with an appropriate independent evaluation. Matching a few marginal distributions alone is not enough to establish downstream utility or privacy; evaluate against a held-out baseline and the intended task. If you need the output to be provably non-identifying, stop here and look at the evaluation tooling the README points to instead, because this repository stops at generation.
Editorial conclusion
Adopt fg-data-synthetic if you are comfortable running PyTorch or TensorFlow 2.0 yourself and you want several GAN architectures plus a CPU-friendly Gaussian Mixture baseline under one import. Do not adopt it if you need built-in privacy guarantees, automated quality scoring, or a supported managed pipeline; the README describes generation, not verification, and points to a separate commercial product for the end-to-end flow. Before committing, run the migration grep on your codebase, confirm your Python is 3.9 or 3.10, and open the Fast_Adult_Census_Income_Data notebook to see what the Gaussian Mixture path actually produces on your own column types.
Frequently asked questions
How do I migrate from ydata-synthetic to fg-data-synthetic?
Uninstall the old distribution with pip uninstall ydata-synthetic, install the new one with pip install fg-data-synthetic, and change imports from ydata_synthetic to data_synthetic. The readme gives a grep command to find files that still use the old module name.
Which models does the fg-data-synthetic UI support?
Six: CGAN, WGAN, WGANGP, DRAGAN, CRAMER and CTGAN. The project's resources list nine tabular architectures and two sequential ones, so GAN, CWGAN-GP, Gaussian Mixture, TimeGAN and DoppelGANger are not offered through the interface.
Which licence applies to fg-data-synthetic?
The repository's licence field says MIT and the readme points at an MIT license file, while the classifier list in setup.py declares GNU General Public License v3 or later. The build script sets no licence field, so the classifier is the only licence statement in the built distribution, and the two contradict each other.
What does fg-data-synthetic need to install?
The requirement list pins tensorflow to 2.15 with numpy below 2, and holds pandas below 3 and scikit-learn below 2. It also requires pmlb, which fetches benchmark datasets over the network, and the readme offers Kaggle links for the Adult Census Income, credit card fraud and Cardiovascular Disease datasets.
Where do the fg-data-synthetic examples live?
In the examples directory, with regular tabular notebooks, a timeseries folder and a streamlit_app.py file. The readme links every one of them through the master branch while the repository's default branch is dev, and the examples are Colab notebooks.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/data-centric-ai-community-fg-data-synthetic)Star history chart for your README
[](https://hysenlabs.com/projects/data-centric-ai-community-fg-data-synthetic)Was this useful?