DeepEP V2.5: DeepSeek's expert-parallel kernels now JIT-compiled on NCCL Gin, with V1 and NVSHMEM gone
Project brief: DeepEP: an efficient expert-parallel communication library. Example use in model training or inference prefilling V2 unifies the dispatch and combine APIs into a single ElasticBuffer interface.
At a glance
- What is it?
- DeepEP is DeepSeek's MIT licensed CUDA library for MoE dispatch and combine across GPUs, plus experimental pipeline, context and data parallel primitives. The V2 line rebuilt it around DeepJIT and the NCCL Gin backend, and the hardware and toolchain floor is high: Linux, Hopper or newer GPUs, CUDA 13.1 and NCCL 2.32.3.
- Who is it for?
- DeepEP is for teams training or serving MoE models on Linux clusters of Hopper or newer NVIDIA GPUs with NVLink inside nodes and RDMA between them, who want DeepSeek's dispatch and combine kernels without hand tuning SM and QP counts. It is not for pre-Hopper GPUs, Windows, or stacks that cannot move to CUDA 13.1, PyTorch 2.10 and NCCL 2.32.3, and anyone still on the V1 API or NVSHMEM backend has to migrate because V1 is removed.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 24 days ago.
- What is it written in?
- Mainly Cuda, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
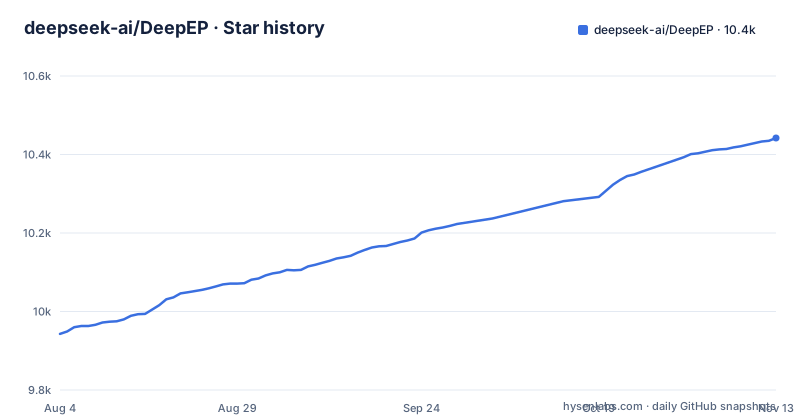
Star history
- deepseek-ai/DeepEP10,442 ★ · +499
| Repository | 2026-08-04 | 2026-11-13 |
|---|---|---|
| deepseek-ai/DeepEP | 9.9k | 10.4k |
499 Stars in the last 101 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
MoE dispatch and combine as all-to-all kernels behind EPBuffer
DeepEP, short for DeepEveryParallel, supplies the all-to-all GPU kernels that move tokens to experts and bring results back in mixture-of-experts models, in both a high-throughput mode for training and inference prefilling and a low-latency mode for decoding. FP8 dispatch is supported. Since EPv2 both modes sit behind one EPBuffer interface, with an expanded layout meant for grouped expert GEMMs, and hybrid and direct modes both remain available. You create and reuse one buffer per EP group, passing MoE settings such as num_max_tokens_per_rank, hidden, num_topk, num_experts and use_fp8_dispatch. All ranks must agree on num_max_tokens_per_rank, so you pick one capacity that covers your training, prefill and decoding batch sizes, and you must finish outstanding operations before replacing a buffer.
No auto-tuning: SM and QP counts are calculated, and dispatch always costs SMs
Earlier DeepEP required tuning how many streaming multiprocessors and RDMA queue pairs the communication kernels used. EPv2 replaces that with an analytical SM and QP count calculation made when the buffer is created, and you can still override the numbers per call. The trade-off is fixed by design: EP dispatch and combine require GPU SMs, and zero-SM RDMA EP is not supported. Every SM handed to communication is one not running expert computation, so a team hoping to offload MoE traffic entirely to the network card will not get that from DeepEP. Plan compute and communication overlap around the SM budget the library reports rather than assuming communication is free.
Kernels are compiled at runtime by DeepJIT, so the CUDA toolkit stays on every node
Installation builds only the host C++ extension against CUDA and NCCL. The GPU kernels are compiled by DeepJIT for the device present at runtime, which means installation does not need a visible GPU or TORCH_CUDA_ARCH_LIST, and a wheel can be built on a machine without a GPU. The cost moves to runtime: the CUDA Toolkit 13.1 or newer and a C++20 host compiler whose standard library supports std::format have to be available wherever the code runs, not just where it was built. Slim inference images that strip compilers will break. setup.py persists environment variables such as EP_JIT_CACHE_DIR, EP_JIT_PRINT_COMPILER_COMMAND and EP_JIT_CPP_STANDARD, which control where compiled kernels are cached and how the compiler is invoked. DeepJIT arrives as a git submodule:
# Initialize the DeepJIT submodule
git submodule update --init --recursive

# Build a wheel and install it into the current Python environment
bash install.sh
After that, the package imports as deep_ep.
PyTorch and DeepEP must load the same NCCL library
V2 introduced the lightweight NCCL Gin backend, which offers device-side communication APIs and can reuse NCCL communicators you already have. NCCL 2.32.3 or newer is required, installed from the pip package that matches your CUDA major version:
# CUDA 13.x
python -m pip install "nvidia-nccl-cu13>=2.32.3" --no-deps
# For CUDA 12.x, use nvidia-nccl-cu12 instead
A custom NCCL install is found through EP_NCCL_ROOT_DIR, which must point at a directory containing include/ and lib/. Two failure conditions follow from this design. PyTorch and DeepEP have to load the same NCCL shared library, so the NCCL that your PyTorch install loads decides which one DeepEP has to use. Builds compiled against NCCL headers older than 2.31 also need an exact match between compile-time and runtime NCCL versions. Engram adds its own constraint: it requires an NCCL build that provides ncclGinOptFlagsWarpGet.
V2.5 removed V1 and its NVSHMEM backend outright
V2.5 fully removes V1, including its APIs, the NVSHMEM backend and the legacy documentation, and NVSHMEM is no longer a dependency. Code written against V1 will not run on current main; it has to be ported to EPBuffer. The release history adds a wrinkle: the only tagged release is v1.2.1 from 2025-09-16, while main moved through V2 and V2.5 and was last pushed on 2026-10-21. Installing from that tag gives you the old architecture, so anyone wanting EPv2, NCCL Gin or the new buffers builds from main. V2.5 also split the ElasticBuffer interface that V2 introduced into EPBuffer, EngramBuffer, PPBuffer and BucketBuffer, all sharing a BufferBase lifecycle, and added a BufferAllocator that plans symmetric tensor allocations before buffers are built. Early V2 adopters who wrote against ElasticBuffer face a rename as well.
Redundant experts over NVLink: lb_prefetch_weights and lb_reduce_grads
For dynamic redundant experts, EPBuffer.lb_prefetch_weights fetches expert weights and quantization scales over NVLink before expert computation, and EPBuffer.lb_reduce_grads accumulates the redundant experts' FP32 gradients back into the original experts during the backward pass. These primitives support the expert replication approach explored by MoonEP and UltraEP, and the weight-prefetch and gradient-reduction tests run within a single NVLink domain. V2.5 also brings deferred EP epilogues, cached expanded layouts and zero padding between experts. Engram, the remote memory access primitive, can now store multiple layers on GPU or CPU with one wait hook per layer, but it remains experimental and RDMA based.
Bucket collectives need both NVLink and RDMA bandwidth detectable, even for one transport
BucketBuffer provides batched all-gather, reduce-scatter and all-reduce for context and data parallelism, with sessions for ordinary PyTorch tensors. Like Engram and PP, it is experimental. Automatic bandwidth detection relies on nvidia-smi and ibstat, and BucketBuffer currently requires both NVLink and RDMA bandwidth to be detectable even when a group uses only one transport. A single-node machine without InfiniBand tooling, or a container missing ibstat, cannot use bucket collectives as things stand. PP has the opposite constraint in testing: its tests require an RDMA-only group. The test scripts need NumPy and spawn local GPU workers; for multiple nodes you launch the same script on each node with shared MASTER_ADDR and MASTER_PORT, WORLD_SIZE set to the node count and RANK to the node index, following init_dist in deep_ep/utils/envs.py. The tests default NCCL_IB_SL and EP_OVERRIDE_RDMA_SL to 1 unless already set.
# Build and link the extension into the source tree
bash develop.sh

# Run test cases
python tests/ep/test_ep.py
python tests/bucket/test_all_gather.py
python tests/bucket/test_reduce_scatter.py
python tests/bucket/test_all_reduce.py
python tests/buffer/test_allocation.py
python tests/ep/test_prefetch_weights.py
python tests/ep/test_reduce_grads.py
python tests/engram/test_engram.py
python tests/pp/test_pp.py
Hopper or newer on Linux only, with a separate DeepEP-Ascend for Huawei NPUs
The requirements leave no room for older hardware: Linux, Python 3.10 or above, NVIDIA Hopper or newer GPUs, PyTorch 2.10 or above with CUDA, NVLink for intranode traffic and an RDMA network for internode traffic. GPUs older than Hopper are outside the supported set, and there is no Windows or macOS path. For Huawei hardware there is a separate project, DeepEP-Ascend, which offers the same API on Ascend 950 NPUs. Code written against deep_ep can therefore target that hardware without an API rewrite, but it is a different repository with its own installation.
Editorial conclusion
DeepEP is for teams training or serving MoE models on Linux clusters of Hopper or newer NVIDIA GPUs with NVLink inside nodes and RDMA between them, who want DeepSeek's dispatch and combine kernels without hand tuning SM and QP counts. It is not for pre-Hopper GPUs, Windows, or stacks that cannot move to CUDA 13.1, PyTorch 2.10 and NCCL 2.32.3, and anyone still on the V1 API or NVSHMEM backend has to migrate because V1 is removed. Before adopting it, confirm PyTorch and DeepEP will load the same NCCL library, that nvidia-smi and ibstat work on every node, and treat Bucket, Engram and PP as experimental.
Frequently asked questions
What is DeepEP?
DeepEP (DeepEveryParallel) is DeepSeek's MIT licensed communication library for machine learning training and inference. It provides expert-parallel all-to-all GPU kernels for MoE dispatch and combine, including FP8 dispatch, plus experimental PP, CP, DP and Engram primitives.
What hardware does DeepEP need?
DeepEP needs Linux, NVIDIA Hopper or newer GPUs, NVLink for intranode communication and an RDMA network for internode communication. It also requires CUDA Toolkit 13.1, PyTorch 2.10 and NCCL 2.32.3 or newer.
Does DeepEP still use NVSHMEM?
No. DeepEP V2.5 fully removed V1, including its APIs and NVSHMEM backend, and NVSHMEM is no longer a dependency. Communication now goes through the NCCL Gin backend.
Does DeepEP run on Huawei Ascend NPUs?
Through a separate repository. DeepEP-Ascend offers the same API on HUAWEI Ascend 950 NPUs.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-deepep)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-deepep)Was this useful?