databricks/learning-spark: the example code that ships with the Learning Spark book
Example code from Learning Spark book
At a glance
- What is it?
- A Java, Scala and Python example repository tied to Spark 1.3, useful for readers working through the book and awkward for anyone who wants current Spark APIs. The README is the only install guide, and it is short.
- Who is it for?
- Adopt it if you are working through Learning Spark and want the runnable code that matches the text, or if you want a small worked example of spark-submit and assembly jars. Do not adopt it as a starting point for new Spark work: the README pins Spark 1.3, JDK 1.7 and Scala 2.10.3, and the Python examples need urllib3 while ChapterSixExample needs R and the CRAN Imap package.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 138 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
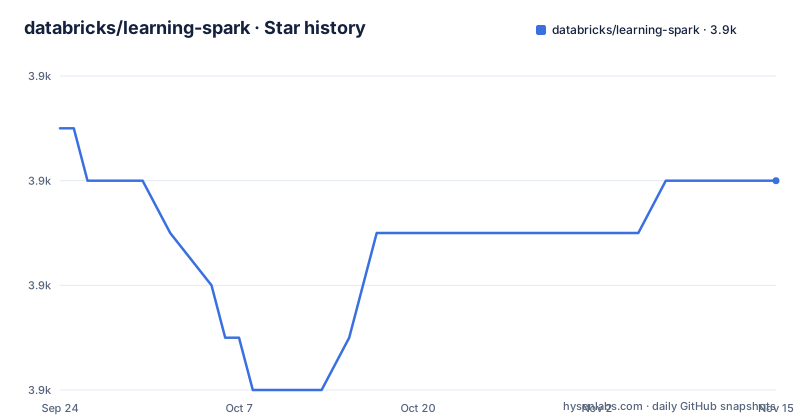
Star history
- databricks/learning-spark3,896 ★ · -1
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| databricks/learning-spark | 3.9k | 3.9k |
-1 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What databricks/learning-spark is, and who it is for
This repository is the companion code for the Learning Spark book. The README says so in one line, then immediately warns that the examples "require a number of libraries and as such have long build files." That sentence is the whole pitch and the whole problem. The target reader is someone with the book open, working through a chapter, who wants to run the example rather than retype it. The repository is Java-first according to its primary language, but the tree also carries Python under src/python and Scala under the same source root, and the README documents running all three.
It is not a library. Nothing here is meant to be added to a dependency list. It is a set of runnable programs, plus the build scaffolding (build.sbt, pom.xml, a project/ directory, and a bundled sbt/ launcher) needed to compile them into an assembly jar. If you are evaluating Spark itself, or looking for a starter template for a production job, this is the wrong artifact. If you are reading the book and your chapter's example will not compile, it is the right one.
How the examples are laid out and how they run
The data flow is deliberately plain. Source files live under src/, split by language, with the Java and Scala classes under the com.oreilly.learningsparkexamples package namespace, which is what the spark-submit example in the README references. Sample input data sits in files/, and the Python examples read it through pyspark.
There are two ways to run things. The lightweight path is pyspark, invoked from a Spark installation, pointing at a single script. The heavyweight path compiles everything into one assembly jar with all dependencies bundled, then hands that jar to spark-submit with a --class argument naming the example. The second path is why the build file is long: the assembly has to carry every library the examples touch, including the Protobuf compiler dependency and the R and CRAN Imap requirements for ChapterSixExample.
The mini-complete-example directory is the escape hatch. The README describes it as "a stand alone example with minimal dependencies and a small build file." If the root build fails on your machine, that directory is the smaller thing to debug, and it is the part of the repository least likely to break as toolchains move on.
Installing it and running a first example
The README lists requirements rather than install steps: JDK 1.7 or higher, Scala 2.10.3, Spark 1.3, and a Protobuf compiler. On Debian the README gives the Protobuf install command directly. ChapterSixExample additionally needs R and the CRAN package Imap, and the Python examples need urllib3.
sudo apt-get install protobuf-compilerWith those in place, the Python path is the shortest route to a running example. From a Spark installation, the README gives this invocation, where [example] is the script name:
./bin/pyspark ./src/python/[example]If you want the compiled Java or Scala path instead, build the assembly jar first. The README offers sbt or Maven as alternatives:
./sbt/sbt assemblymvn packageThen submit it from your Spark home directory, substituting the language and example name:
cd $SPARK_HOME; ./bin/spark-submit --class com.oreilly.learningsparkexamples.[lang].[example] ../learning-spark-examples/target/scala-2.10/learning-spark-examples-assembly-0.0.1.jarWhat you should see is the example's own output on stdout. The README does not describe expected output for any example, so the first run is also the first time you learn what the program prints. The repository also carries run-all-examples, setup-project and build-project scripts at the top level, but the README does not document what they do, so treat them as unexplored until you read them.
The version pin is the real limitation
The README states plainly that the examples "have been updated to run against Spark 1.3" and that they may differ from the printed book. That single sentence defines both the value and the ceiling. Spark 1.3 is far behind current Spark, and the RDD-centric API style the book teaches has been supplemented, not replaced, by DataFrame and Dataset work in later releases. Code that compiles against 1.3 may still compile against a modern Spark, but nothing in this repository promises that, and the README does not document a compatibility matrix.
The build environment is the second constraint. JDK 1.7 and Scala 2.10.3 are both old enough that a current JDK will likely refuse the build outright. The README says "JDK 1.7 or higher," which reads permissive but was written when 1.7 was the floor, not when 1.7 was two major versions behind. If your machine runs a modern JDK, expect to install an older one or to work inside a container.
The dependency surface is the third. Protobuf, R, Imap and urllib3 are all required by specific examples, not by the repository as a whole, so a partial setup will fail on some chapters and not others. The README does not say which example needs which dependency beyond naming ChapterSixExample for R and Imap. That mapping is something you reconstruct by reading the source.
Where this sits next to the book's later editions
The obvious alternative is not another repository but the second or third edition of Learning Spark itself, which the search data around this project shows people are actively looking for. Those editions target newer Spark versions and the DataFrame API, and their companion code tracks that. The difference in approach is not stylistic: the first edition's examples build RDDs by hand and reason about partitions and pair operations, while later editions start from structured data and let the optimizer do more of the work.
Choosing between them is choosing which mental model you want first. If your goal is to understand what Spark does underneath the DataFrame layer, the RDD examples here are still the clearest worked version of that, and the book's explanations line up with the code line by line. If your goal is to write Spark jobs that run on a current cluster, the older edition's code will teach you an API surface you then have to unlearn or supplement. There is no version of this repository that gives you both.
Maintenance, licensing and what the build costs you
The last push to the default branch was on 2026-06-30. The repository is not archived. That is recent enough that the project has not been abandoned, but the README still describes Spark 1.3 and Scala 2.10.3, so activity on the repository has not translated into a modernised build. The repository has no published GitHub releases, which fits a repository that is consumed by cloning rather than by depending on a published artifact.
The upgrade cost is therefore not a version bump you perform; it is a decision about whether to port the examples yourself. Because the assembly jar bundles all dependencies, bumping Spark means re-resolving every transitive library in build.sbt or pom.xml, and the long build file the README warns about is exactly the thing that makes that tedious. The mini-complete-example directory is the cheapest place to start if you do port something.
The licence is MIT, per the repository metadata, with a LICENSE.md file at the top level. MIT is permissive: it allows reuse and modification with the licence and copyright notice retained. That is a statement about the licence text, not advice about your situation; if you plan to redistribute the code, read LICENSE.md and the notices for the bundled dependencies yourself, since the assembly jar pulls in third-party libraries under their own terms.
Editorial conclusion
Adopt it if you are working through Learning Spark and want the runnable code that matches the text, or if you want a small worked example of spark-submit and assembly jars. Do not adopt it as a starting point for new Spark work: the README pins Spark 1.3, JDK 1.7 and Scala 2.10.3, and the Python examples need urllib3 while ChapterSixExample needs R and the CRAN Imap package. Before you commit to it, check that your local Spark version matches the 1.3 target and confirm which example you actually need, since the mini-complete-example directory exists precisely because the root build file is long.
Frequently asked questions
What Spark version do the databricks/learning-spark examples target?
The README states the examples have been updated to run against Spark 1.3, and that they may differ slightly from the versions printed in the book. The listed requirements also include JDK 1.7 or higher and Scala 2.10.3.
How do I run a databricks/learning-spark example with spark-submit?
Build the assembly jar first with ./sbt/sbt assembly or mvn package, then from $SPARK_HOME run spark-submit with --class com.oreilly.learningsparkexamples.[lang].[example] pointing at the assembly jar under target/scala-2.10/.
Does databricks/learning-spark need R installed?
Only ChapterSixExample does. The README lists R and the CRAN package Imap as requirements for that example specifically, alongside the Protobuf compiler needed by the build.
Is there a smaller version of the databricks/learning-spark build?
Yes. The README points to the mini-complete-example directory, described as a stand alone example with minimal dependencies and a small build file, added because the main examples have long build files.
Can I run the databricks/learning-spark Python examples without building the jar?
The README gives a path that skips the build: from a Spark installation, run ./bin/pyspark ./src/python/[example]. The Python examples require urllib3.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/databricks-learning-spark)Star history chart for your README
[](https://hysenlabs.com/projects/databricks-learning-spark)Was this useful?