DeepSeek-OCR: A Vision Encoder That Compresses Images into Text Tokens
Project brief: Contexts Optical Compression. Model Download | Paper Link | Arxiv Paper Link | DeepSeek-OCR: Contexts Optical Compression Explore the boundaries of visual-text compression.
At a glance
- What is it?
- DeepSeek-OCR treats OCR as context compression, mapping images to a small number of vision tokens. It offers native and dynamic resolution modes, but its vLLM setup is version-sensitive and its true utility depends on the prompt you choose.
- Who is it for?
- Adopt DeepSeek-OCR if you need OCR or document-to-markdown conversion with tunable resolution and are comfortable with a CUDA 11.8, torch 2.6.0 environment. Skip it if you require a stable, long-term API or if you cannot run a CUDA environment.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 9 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
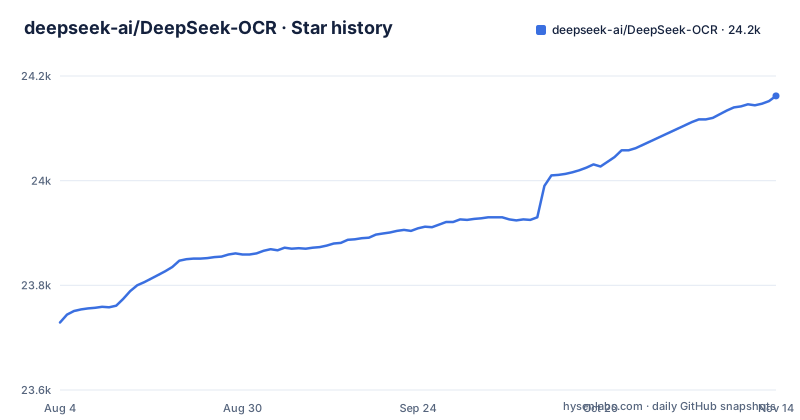
Star history
- deepseek-ai/DeepSeek-OCR24,162 ★ · +433
| Repository | 2026-08-04 | 2026-11-14 |
|---|---|---|
| deepseek-ai/DeepSeek-OCR | 23.7k | 24.2k |
433 Stars in the last 102 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What It Solves and Who It Targets
DeepSeek-OCR addresses a specific problem: converting visual information, such as documents, figures, and general images, into a compressed textual representation. The project's tagline, 'Contexts Optical Compression,' suggests that the model learns to encode an image into a small set of vision tokens that the language model can then decode into text. The README positions it as an investigation into the role of vision encoders from an LLM-centric viewpoint, which is a research-oriented framing. The target user is an engineer or researcher who needs OCR with layout awareness, markdown conversion, or figure parsing, and who is willing to run a local model with heavy GPU requirements. The supported prompts, such as 'Convert the document to markdown' and 'Locate <|ref|>xxxx<|/ref|> in the image,' indicate use cases in document processing, data extraction, and visual grounding. It is not a lightweight library; it demands a CUDA environment and a recent GPU.
How It Compresses Images into Tokens
The mechanism is visible in the resolution modes. The model accepts native resolutions that map to a fixed number of vision tokens: 512x512 yields 64 tokens, 640x640 yields 100, 1024x1024 yields 256, and 1280x1280 yields 400. There is also a dynamic mode called 'Gundam' that combines n times 640x640 plus one 1024x1024 tile. This token budget is the compression. The vision encoder presumably downsamples the image into these tokens, and the language model then generates text from them. The README does not explain the internal architecture, but the token counts suggest a direct relationship between input resolution and the amount of visual information preserved. Higher resolution means more tokens, which means more detail but also more compute. The 'Free OCR' prompt skips layout grounding, while the '<|grounding|>' prompt enables structure-aware output like markdown. This design lets the user trade off speed and fidelity per task.
Installation and Environment Constraints
Getting DeepSeek-OCR running is not a simple pip install. The README specifies a conda environment with Python 3.12.9, CUDA 11.8, and torch 2.6.0. You must download a specific vLLM wheel, vllm-0.8.5+cu118, and install flash-attn 2.7.3 with --no-build-isolation. The note about a potential installation error regarding transformers>=4.51.1 suggests that vLLM and transformers have conflicting dependency requirements, which the author says you can ignore if you keep both in the same environment. For vLLM inference, you edit config.py in the DeepSeek-OCR-vllm folder, then run one of three scripts: run_dpsk_ocr_image.py for streaming image output, run_dpsk_ocr_pdf.py for PDFs, and run_dpsk_ocr_eval_batch.py for benchmark evaluation. The PDF script is claimed to achieve concurrency of about 2500 tokens per second on an A100-40G, though that figure comes from the README and has not been independently verified. For Transformers inference, you load the model with trust_remote_code=True and set _attn_implementation='flash_attention_2'. The environment is rigid; deviating from the specified versions may cause build failures.
The vLLM Integration and Its Version Sensitivity
The README highlights that DeepSeek-OCR is officially supported in upstream vLLM, with a link to a recipe. The example code shows you must instantiate a custom logits processor, NGramPerReqLogitsProcessor, and pass it to the LLM constructor. You also need to set enable_prefix_caching=False and mm_processor_cache_gb=0. This is not a standard vLLM setup; it requires importing from vllm.model_executor.models.deepseek_ocr. The version note is telling: until v0.11.1 releases, you need to install vLLM from a nightly build. That means the integration is fragile. If you use the older vLLM 0.8.5 wheel from the install section, you get the project's own scripts. If you use upstream vLLM, you must track nightly builds. This is a real maintenance burden. The project's own release note from 2025/10/23 says it is now supported in upstream vLLM, but the requirement for a nightly build suggests the support is not yet stable. For production use, this version churn could be a dealbreaker.
Prompt Engineering Is the Real Interface
The model's behavior is driven by the prompt you prepend to the image. The README lists six distinct prompts, each targeting a different task. For documents, you use '<image> <|grounding|>Convert the document to markdown.' For general images, 'OCR this image.' For figures in a document, 'Parse the figure.' For a detailed description, 'Describe this image in detail.' There is also a referencing prompt for locating a specific object: 'Locate <|ref|>xxxx<|/ref|> in the image.' This is not a simple OCR API; it is a multimodal language model that responds to instructions. The difference between 'Free OCR' and the grounding prompt matters. 'Free OCR' likely returns plain text without layout structure, while the grounding prompt adds markdown formatting. You must experiment with each prompt on your own data. This prompt dependency is both a strength and a weakness. It gives flexibility, but it also means the model's output is only as good as your prompt phrasing.
Limitations and When It Is the Wrong Tool
The most obvious limitation is the hardware requirement. The README mentions an A100-40G for PDF concurrency, which is a high-end data center GPU. The installation process is brittle. The specific versions of torch, vLLM, and flash-attn are pinned, and the note about transformers conflicts suggests that any upgrade could break the setup. The model is also not a general-purpose OCR tool. It is designed for specific tasks like markdown conversion and figure parsing. If you only need plain text extraction from a scanned image, a simpler OCR engine like Tesseract may be enough. The README does not mention any quantization or CPU inference, so you must have CUDA. Another limitation is the lack of documentation on output formats. The README documents prompts but not output formats, so you cannot predict whether the markdown will be well-formed or whether the grounding works on complex layouts. There is also no mention of error handling for low-resolution images. The smallest native resolution is 512x512, which may not be enough for dense text.
A Real Alternative: GOT-OCR2.0
The README acknowledges several projects that influenced DeepSeek-OCR, including GOT-OCR2.0. DeepSeek-OCR frames its contribution as an LLM-centric investigation into vision encoders. The README does not provide a direct comparison. The choice between the two should depend on whether you need DeepSeek's specific resolution modes and prompt flexibility, or whether a simpler model suffices. The README also mentions MinerU and PaddleOCR in its acknowledgements.
Maintenance, License, and Upgrade Path
The project is licensed under MIT, which means you can use, modify, and redistribute it with minimal restrictions, though this is not legal advice. The maintenance situation is mixed. There is a release note from January 2026 pointing to DeepSeek-OCR2, which suggests the original project may be superseded. That is an upgrade path: if you need the latest features, you should look at DeepSeek-OCR2. The repository is not archived, its last push was on 2026-01-27, and it publishes no GitHub releases. The README does not document a changelog or migration guide. The dependency on specific vLLM and flash-attn versions means that any upgrade to your environment could break the model. You will need to pin your environment carefully. The custom logits processor in vLLM is a sign that this model does not fit standard inference stacks, so you must maintain that custom code. If you adopt this, budget time for environment maintenance. The license is permissive, but the model weights are separate; the README links to a Hugging Face download, and the license for the weights is not stated in the README, so verify that separately.
Editorial conclusion
Adopt DeepSeek-OCR if you need OCR or document-to-markdown conversion with tunable resolution and are comfortable with a CUDA 11.8, torch 2.6.0 environment. Skip it if you require a stable, long-term API or if you cannot run a CUDA environment. Before integrating, verify that your vLLM version matches 0.8.5 or the nightly build, and confirm that flash-attn 2.7.3 builds on your system. Test the grounding prompt on your own documents first, because the model's output quality depends heavily on prompt phrasing.
Frequently asked questions
Does DeepSeek have OCR?
Yes. DeepSeek-OCR was released on 20 October 2025 as a model to investigate the role of vision encoders from an LLM-centric viewpoint, and a second version, DeepSeek-OCR2, was presented on 27 January 2026 in a separate repository.
What resolution modes does DeepSeek-OCR support?
Native resolution at 512x512 with 64 vision tokens, 640x640 with 100, 1024x1024 with 256 and 1280x1280 with 400, plus a dynamic mode called Gundam written as n times 640x640 plus one 1024x1024 tile.
How do you install DeepSeek-OCR?
Clone the repository, create a conda environment with python=3.12.9, then install torch==2.6.0 from the cu118 index, the vllm-0.8.5+cu118 wheel, requirements.txt and flash-attn==2.7.3 with --no-build-isolation.
What API does DeepSeek-OCR use?
No hosted API is documented. The repository describes local inference only, through a vLLM path with run_dpsk_ocr_image.py, run_dpsk_ocr_pdf.py and run_dpsk_ocr_eval_batch.py, or a Transformers path in DeepSeek-OCR-hf.
Can DeepSeek-OCR run locally on a machine without an NVIDIA GPU?
The documented path does not show one. The environment is stated as cuda11.8 with torch2.6.0, the vLLM wheel targets manylinux1_x86_64, and the Transformers example calls .cuda() and converts the model to bfloat16.
How do you choose between document parsing and plain text in DeepSeek-OCR?
The prompt decides it. Layout aware document output uses <image>\n<|grounding|>Convert the document to markdown., plain transcription without layouts uses <image>\nFree OCR., and figures use <image>\nParse the figure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/deepseek-ai-deepseek-ocr)Star history chart for your README
[](https://hysenlabs.com/projects/deepseek-ai-deepseek-ocr)Was this useful?