trpc-agent-go lets a reviewing model write new skills back into the agent that used them
A Go framework for building production agent systems with graph workflows, tools, memory, A2A, AG-UI, MCP, evaluation, and observability.
At a glance
- What is it?
- trpc-agent-go is an Apache-2.0 Go framework for agent systems, pitched as a LangGraph-shaped runtime with tools, memory, evaluation and OpenTelemetry. Two features deserve a careful read before adoption: skills can be fetched from a URL and executed locally, and completed sessions can be reviewed by a model and published back as new skills.
- Who is it for?
- Use trpc-agent-go when agent work has to live inside an existing Go service, with tracing, cancellation and a type-safe graph rather than a script. Three things to decide before you adopt it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
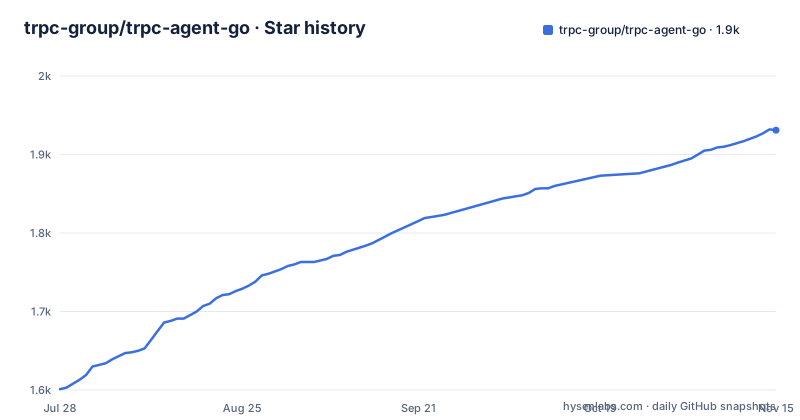
- trpc-group/trpc-agent-go1,931 ★ · +330
| Repository | 2026-07-28 | 2026-11-15 |
|---|---|---|
| trpc-group/trpc-agent-go | 1.6k | 1.9k |
330 Stars in the last 110 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
GraphAgent is sold as the LangGraph equivalent for Go, and that is the pitch
The positioning is comparative from the first bullet. The graph component is described as type-safe graph workflows with multi-conditional routing, functionally equivalent to LangGraph for Go, and the runtime underneath it as Go-native: streaming runners, context cancellation and service-friendly APIs. The module path is `trpc.group/trpc-go/trpc-agent-go` and the module declares Go 1.21.
What comes with it is the surrounding machinery a production service needs rather than a demo. Multi-agent collaboration covers chain, parallel and cycle-based workflows, built from a chain agent constructor taking a list of sub-agents and a parallel agent constructor doing the same. Tool calling turns an ordinary Go function into a tool with a name and a description, and MCP tools arrive through a separate constructor that takes a server connection. Session and memory state, knowledge retrieval, artifacts, evaluation and OpenTelemetry observability sit in the same module.
The named use cases are customer support, data analysis assistants, DevOps automation, business process automation with human in the loop, and retrieval-augmented research assistants. The claim is deliberately narrow, which is to say this is a framework for services rather than a library for a notebook.
A skill repository accepts a URL, downloads the archive and caches it on disk
Skills are folders built around a `SKILL.md` specification, and the repository constructor is where the interesting behaviour sits:
repo, _ := skill.NewFSRepository("./skills")

// Let the agent load and run skills on demand.
tools := []tool.Tool{
    skilltool.NewLoadTool(repo),
    skilltool.NewRunTool(repo, localexec.New()),
}
The same constructor also accepts an HTTP or HTTPS URL, and the documented examples of what can sit at that URL are a `.zip` archive and a `.tar.gz` archive. The payload is downloaded and cached locally, and an environment variable named `SKILLS_CACHE_DIR` overrides where the cache lives. The repository also accepts multiple roots, which the documentation positions as the way to combine shared skills with private ones.
There is a lifecycle condition attached to the filesystem repository, and it is the kind of detail that only appears when someone has been bitten by it. In a long-lived process you are expected to call `repo.Refresh()` after installing, deleting or renaming a skill, so that the next turn sees the updated set. Without that call the running process keeps serving the skill list it read at startup, which for a server is the difference between a skill appearing and not appearing until the next deploy.
Fenced code in assistant text can run, unless you switch the response processor off
One paragraph of the documentation is a warning about interaction between two features, and it is the most security-relevant text in the project. If you wire skills through the LLM agent constructor with a code executor option, you are advised to also set the option that disables the code execution response processor. The stated reason is that Markdown fenced code blocks embedded in assistant text would otherwise auto-execute while the skill runner is enabled.
Read that carefully as a threat model. The skill runner executes locally, through the local execution helper passed to the run tool constructor, and separately the agent can be configured to execute code that appears in a model's own output. With both enabled, content produced by a model, or returned from a remote skill archive, becomes a program on your host. The two flags are the only controls named for it, and the documentation frames the interaction as a configuration caveat rather than as a security boundary.
The same reasoning applies to remote skills. A skill repository pointing at a URL means the instruction text a future turn will follow arrives over the network, is cached on local disk, and is handed to a local executor. Pinning your own archives, or keeping the repository on the filesystem, is the difference between a skill set you wrote and one you fetched.
Self-evolution reviews finished sessions and writes the result back as a skill
The self-evolution service is constructed with a reviewer model, a directory for managed skills and a skill repository:
repo, _ := skill.NewFSRepository("./managed_skills")
evo := evolution.NewService(reviewerModel,
    evolution.WithManagedSkillsDir("./managed_skills"),
    evolution.WithSkillRepository(repo))
defer evo.Close()

runner := runner.NewRunner("app", agent,
    runner.WithEvolutionService(evo))
The behaviour it adds is stated in one sentence: completed sessions can be reviewed asynchronously, promoted through quality gates, and published back as managed Agent Skills for future turns. The feature list calls it Hermes-style session reviews that extract, gate and publish reusable `SKILL.md` workflows.
So the loop is closed on itself. A model reviews what an agent did, decides the session contained a reusable procedure, writes that procedure into a file, and later turns load it as a skill. The mechanism is attractive for long-lived agents and it means the prompt surface grows without a human writing it. What the documentation does not describe is what the quality gates check, how a promoted skill is reviewed after publication, or how a bad skill is withdrawn, so the mechanism is legible while the safety rail is not.
Memory is a service attached to the runner, and the same object becomes a tool
Memory appears twice in the same example, which is the design decision worth noticing. An in-memory memory service is constructed, its tools are attached to the agent, and the service itself is handed to the runner:
// Persistent memory with search
memory := memorysvc.NewInMemoryService()
agent := llmagent.New("assistant",
    llmagent.WithTools(memory.Tools()),
    llmagent.WithModel(model))

// Memory service managed at runner level
runner := runner.NewRunner("app", agent,
    runner.WithMemoryService(memory))
Attaching the tools makes recall and write operations callable by the model as ordinary tool calls. Handing the service to the runner puts its lifecycle, and whatever persistence it uses, under the runner rather than under the agent, which is what lets several agents in one process share state. The in-memory constructor is the one shown, and the top level of the repository keeps separate directories for `memory`, `session`, `knowledge` and `artifact`, so the persistent implementations sit beside it.
The feature list also claims automatic prompt caching with 90% savings on cached content. That number arrives as a marketing figure with no benchmark attached in the visible documentation, so treat it as a direction rather than a measurement until you have measured your own traffic.
Langfuse is attached through OpenTelemetry span attributes rather than a native client
Observability is built on OpenTelemetry, and the Langfuse integration is a worked example on top of it rather than a second telemetry stack. The integration returns a cleanup function that the caller defers, and the user and session identifiers are attached as span attributes on the run:
// Start Langfuse integration
clean, _ := langfuse.Start(ctx)
defer clean(ctx)

runner := runner.NewRunner("app", agent)
// Run with Langfuse attributes
events, _ := runner.Run(ctx, "user-1", "session-1",
    model.NewUserMessage("Hello"),
    agent.WithSpanAttributes(
        attribute.String("langfuse.user.id", "user-1"),
        attribute.String("langfuse.session.id", "session-1"),
    ))
The dependency list backs the claim. OpenTelemetry is pinned at version 1.29.0 across the trace, metric and SDK modules, with OTLP exporters for both traces and metrics over gRPC and over HTTP, so a collector can be reached either way. Structured logging comes from zap, and the `telemetry/` directory at the repository root is where the instrumentation lives.
The practical consequence is that the vendor-neutral path is the default one. Anything that speaks OTLP receives the spans, and Langfuse appears in the repository as an example directory rather than as a mandatory dependency, which is also why the coverage badge and a release workflow sit in the badge row at the top of the page.
The dependency list includes a pseudo-terminal, a SQLite driver and a cloud storage SDK
`go.mod` is the clearest statement of what the framework actually does at runtime, and three entries stand out. `github.com/creack/pty` is a pseudo-terminal implementation, which is what a code executor needs to give a program something resembling a console. `github.com/mattn/go-sqlite3` is the SQLite driver, and it is a cgo package rather than a pure Go one, so a build of this module needs a C toolchain. `github.com/tencentyun/cos-go-sdk-v5` is an object storage client, which is the storage path for artifacts and uploads.
The rest is recognisable agent plumbing: an OpenAI client, gRPC and protobuf alongside a Connect implementation, a glob library for path expansion, a JSON Schema validator, a goroutine pool, an error aggregator, YAML, golden-file comparison and a Markdown parser, plus a Chinese text segmentation library. Test-only dependencies such as testify and go-cmp sit in the same file.
The two sibling modules are worth a look. The A2A module is pinned to a pseudo-version, which in Go means a specific commit rather than a release, while the MCP module sits at a 0.0.10 tag. So one protocol dependency is tracked by commit and the other by version, and both are pre-1.0 in their own right.
Forty-seven top level entries, and three licence files at the root
The repository is wide rather than deep. The top level holds around thirty packages with names that map to the feature list: `agent`, `graph`, `runner`, `tool`, `memory`, `session`, `knowledge`, `artifact`, `skill`, `evolution`, `evaluation`, `codeexecutor`, `planner`, `plugin`, `prompt`, `model`, `event`, `telemetry`, `server`, `storage`, `team` and `log`, plus `internal`, `docs` and `test`. One entry is a bare `benchmark` with no file extension, and one is `openclaw`, whose purpose is not described on the visible page.
The `examples/` directory is the fastest way to see the intended surface, because the directory names name the integrations: A2A variants for an agent, for code execution, for multipath and for sub-agents, an A2A UI, AG-UI, artifacts, an arXiv search, a builtin explorer, callbacks, cancellation of a run, claudecode, codeact, code execution, codex, context compaction and its recovery variant, a custom agent, a debug agent, dify, duckduckgo, a dynamic agent tool and a dynamic workflow. Support files at the root are equally telling: a linter configuration, a typo checker configuration, a CodeRabbit configuration, a gitmodules file, and `AGENTS.md` alongside `CONTRIBUTING.md` and `CODE-OF-CONDUCT.md`.
Licensing has three files rather than one. `LICENSE` and `NOTICE` sit beside a second file named `LICENSE.original`, which is the usual shape for a project whose licensing has changed at some point. Apache-2.0 is what the metadata records, and for an Apache-2.0 consumer the notice file is the one to read alongside it.
Editorial conclusion
Use trpc-agent-go when agent work has to live inside an existing Go service, with tracing, cancellation and a type-safe graph rather than a script. Three things to decide before you adopt it. Whether you want self-evolution on at all, because the design has a model reviewing finished sessions and writing the result back as a skill that later turns will load, and the quality gates between review and publication are described without their criteria. Whether your skills come from your own filesystem, since the repository also accepts an HTTP or HTTPS URL for a zip or tar.gz archive, downloads it, and caches it locally under a directory you can redirect with an environment variable. And whether code execution stays under your control, since the documentation's own advice is to disable the response processor that would otherwise run fenced code blocks embedded in assistant text while the skill runner is enabled. For reference, the newest tag is v1.11.2 from 2026-08-20 while the last push is 2026-09-25, so commits are moving faster than releases.
Frequently asked questions
What is trpc-agent-go?
It is an Apache-2.0 Go framework for building production agent systems, published as the module `trpc.group/trpc-go/trpc-agent-go` and requiring Go 1.21. It provides LLM agents, graph workflows with multi-conditional routing, tool calling, session and memory state, knowledge retrieval, evaluation and OpenTelemetry observability in one stack.
How does trpc-agent-go compare to LangGraph?
Its graph component, GraphAgent, is described as type-safe graph workflows with multi-conditional routing, functionally equivalent to LangGraph for Go. Multi-agent work is done with chain, parallel and cycle-based workflows, and the surrounding runtime is Go-native with streaming runners and context cancellation.
How do agent skills work in trpc-agent-go?
A skill is a folder built around a `SKILL.md` file. `skill.NewFSRepository` takes a local path, or an HTTP or HTTPS URL pointing at a `.zip` or `.tar.gz` archive which it downloads and caches locally, with `SKILLS_CACHE_DIR` overriding the cache location. It also accepts multiple roots, and a long-lived process should call `repo.Refresh()` after a skill is installed, deleted or renamed.
Does trpc-agent-go execute code the model writes?
It can, and the documentation says how to prevent the surprising case. Skills are run through a local execution helper passed to the run tool constructor, and the note advises setting `llmagent.WithEnableCodeExecutionResponseProcessor(false)` when skills are wired through the LLM agent with a code executor, so Markdown fenced code blocks embedded in assistant text do not auto-execute while the skill runner is enabled.
How does trpc-agent-go handle observability?
Through OpenTelemetry, pinned at version 1.29.0 with OTLP exporters for traces and metrics over both gRPC and HTTP, plus zap for logging. The Langfuse integration is an example on top of that: it attaches `langfuse.user.id` and `langfuse.session.id` as span attributes through `agent.WithSpanAttributes` on a run.
How do you evaluate an agent built with trpc-agent-go?
Evaluation is created against a runner and a number of runs, for example `evaluation.New("app", runner, evaluation.WithNumRuns(3))`, closed when you are done, and then pointed at a named eval set such as `math-basic`. The result carries an overall status, and the feature list describes eval sets combined with metrics for tracking quality over time.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/trpc-group-trpc-agent-go)Star history chart for your README
[](https://hysenlabs.com/projects/trpc-group-trpc-agent-go)Was this useful?