fff: a file search library for agents, editors and Neovim
The fastest and the most accurate file search SDK for AI agents, Neovim, Rust, C, Python, Bun and NodeJS
At a glance
- What is it?
- fff is an MIT-licensed Rust file search toolkit with bindings for Python, Node, Bun and C, plus an MCP server and a Neovim plugin. It is built for long-running processes that search repeatedly, and the documentation is honest that this is where its speed comes from.
- Who is it for?
- Adopt fff if you are building an agent harness, an editor integration or any long-running process that issues file search queries more than once, and you are willing to run a background watcher over the repository. Do not adopt it for one-shot command-line searches, where ripgrep or fzf already do the job without keeping an index in memory.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
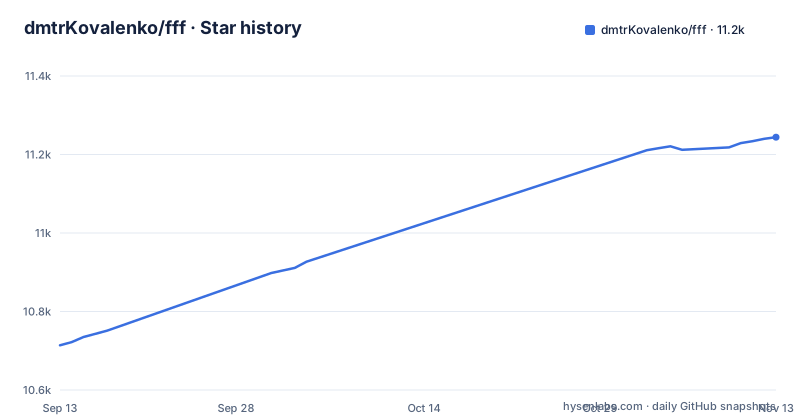
- dmtrKovalenko/fff11,244 ★ · +530
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| dmtrKovalenko/fff | 10.7k | 11.2k |
530 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem fff targets: repeated search inside a live process
The README makes a specific claim about scope: fff is faster than CLIs like ripgrep and fzf in any long-running process that searches more than once. That qualifier is the whole argument. A command-line tool pays process startup and directory traversal on every invocation, which is fine when a human runs it a few times. An agent harness or an editor pays that cost on every tool call, and the cost compounds. fff moves the traversal into a persistent process and keeps a lightweight in-memory content index plus a background watcher, so later queries hit structures that are already built. The README states the project began as a Neovim plugin and then found that AI harnesses and code editors wanted the same thing as a library. The audience follows from that: people embedding search into a host process, not people typing grep into a terminal. The repository description lists Rust, C, Python, Bun and NodeJS as targets, so the intended consumer is a program, and the Neovim plugin and MCP server are two shipped front ends over the same core.
What the index actually holds: frecency, definitions and git state
The README describes the index as typo-resistant path and content search, frequency-ranked file access, a background watcher and a lightweight in-memory content index. Beyond plain matching, the MCP tools support definition search: definitions_only: true restricts a search to declarations, and a definition query drops a filename constraint that matches no indexed file and reports that change. Searches can be scoped with path, paths and globs, and mode can be regex or literal, with case accepting insensitive and smart. Without a mode, smart-case and inline constraints remain available.
Installing the MCP server and pointing a client at it
The README gives two install routes. The one-line installer for Linux and macOS is curl -L https://dmtrkovalenko.dev/install-fff-mcp.sh | bash, and the Windows equivalent is irm https://raw.githubusercontent.com/dmtrKovalenko/fff/main/install-mcp.ps1 | iex. The scripts are in the repository as install-mcp.sh and install-mcp.ps1, and the README says they print the exact wiring instructions for your client. Homebrew is the second route: brew install dmtrKovalenko/fff/fff-mcp, with brew upgrade fff-mcp after new stable releases. The formula lives at Formula/fff-mcp.rb and the README states it is auto-bumped on every stable release by the bump-homebrew-formula job in .github/workflows/release.yaml, installing a prebuilt binary from GitHub releases. For Codex, registration uses an absolute path because desktop sessions may not inherit the interactive shell PATH. With Homebrew that is codex mcp add fff -- "$(brew --prefix)/bin/fff-mcp", and with the installer it is codex mcp add fff -- "$HOME/.local/bin/fff-mcp". The resulting entry in ~/.codex/config.toml looks like [mcp_servers.fff] with a command key set to the installed path. The README notes you should restart Codex or start a new task so it loads the server, and that once connected you can ask the agent to "use fff", the MCP tools being grep, find_files and multi_grep. It also suggests a line for CLAUDE.md: "For any file search or grep in the current git-indexed directory, use fff tools."
The Pi extension and the Neovim plugin share one frecency database
Pi support is present in the repository: package.json registers a Pi extension at ./packages/pi-fff/src/index.ts. The README says MCP and Pi both accept definitions_only: true to search declarations, and that Pi's ffgrep uses pattern where the MCP tool uses query.
Where fff is the wrong tool, and how it differs from ripgrep and fzf
The README's own framing is the clearest limitation. fff is faster in any long-running process that searches more than once. Run it once from a shell and the advantage is gone, because you paid for index construction and a watcher you will not use again. For a single grep in a CI step, ripgrep remains the simpler answer: it starts, searches and exits, with no background process, no database file and no state to invalidate. fzf is a different kind of alternative. It is a generic fuzzy filter that reads lines from stdin, so it composes with anything that produces text and does not need to know about your repository. fff is repository-aware by design, which buys the frecency ranking, the git annotations and the definition classification, and costs you the ability to point it at arbitrary input. The second limitation is the watcher itself. Third, the release history is dominated by nightly builds. The recent releases listed are 0.11.1-nightly.d1c7dd4 and 0.11.1-nightly.1b9c211 (both 2026-10-26) and nightly (0.9.2-nightly.4e8f447, 2026-06-06), with the stable Homebrew upgrade path explicitly described as following new stable releases. Anyone pinning a version should check which tags are stable rather than assuming the newest tag is.
Maintenance cost, release cadence and the MIT licence
The maintenance story is mixed in a way worth stating plainly. On one side, the Homebrew formula is auto-bumped on every stable release through the bump-homebrew-formula job, so the packaged binary tracks releases without manual work. On the other side, the visible release list is nightly-heavy, and the README instructs Homebrew users to run brew upgrade fff-mcp after new stable releases, which implies stable releases are less frequent than nightly ones. If you depend on fff as a library rather than as a binary, you are tracking a project whose public cadence is nightly. The frecency and history databases are persistent state. The licence is MIT, which permits commercial and closed-source use and requires preserving the copyright notice and licence text. That is a statement about the licence identifier in the repository, not legal advice; if you are redistributing a modified binary or embedding the library, have your own counsel read the LICENSE file.
Editorial conclusion
Adopt fff if you are building an agent harness, an editor integration or any long-running process that issues file search queries more than once, and you are willing to run a background watcher over the repository. Do not adopt it for one-shot command-line searches, where ripgrep or fzf already do the job without keeping an index in memory. Before wiring it into anything, confirm that the MCP client can reach the absolute binary path, and read install-mcp.sh and install-mcp.ps1 rather than piping them into a shell.
Frequently asked questions
What is fff search?
fff is a file search SDK written in Rust that began as a Neovim plugin and now ships as an MCP server, a Pi agent extension, and bindings for C, Python, Bun and Node. The MCP server exposes three tools to an agent: grep, find_files and multi_grep.
How do I install the fff MCP server on Linux or macOS?
One command downloads and runs the installer with curl -L https://dmtrkovalenko.dev/install-fff-mcp.sh piped into bash, and a Homebrew formula is available as fff-mcp. The Windows PowerShell equivalent uses irm against install-mcp.ps1, and both installer scripts are committed to the repository if you prefer to read them before running.
Is fff faster than ripgrep?
The project claims it, with a qualifier attached: the README says fff is way faster than CLIs like ripgrep and fzf in any long-running process that searches more than once. That describes editors, shells and MCP-connected agents rather than a single grep inside a build script.
Why does the fff MCP server need an absolute path for Codex?
Because Codex desktop sessions may not inherit your interactive shell's PATH, the binary has to be registered by full path. The command codex mcp add fff with the Homebrew prefix path writes a mcp_servers.fff entry into ~/.codex/config.toml, after which you restart Codex or start a new task.
Can I pin a stable fff version?
Not from the tags that are visible. The two most recent releases are nightly builds named 0.11.1-nightly with a commit hash, published on 2026-10-26, and the third is a nightly tagged 0.9.2-nightly.4e8f447 from 2026-06-06, while the Homebrew formula is described as auto-bumped on every stable release. The fff-grep and fff-query-parser workspace dependencies in Cargo.toml are at version 0.11.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dmtrkovalenko-fff)Star history chart for your README
[](https://hysenlabs.com/projects/dmtrkovalenko-fff)Was this useful?