iii: a shared runtime where every backend service is a Worker, Function or Trigger
Effortlessly compose, extend, and observe every service in real-time for the first time ever.
At a glance
- What is it?
- iii replaces per-service integration work with one engine that registers workers at runtime. The README describes a three-primitive model and a Compose daemon that can add workers while the system runs. The trade-off is that the engine becomes a single dependency for everything.
- Who is it for?
- Adopt iii if your team already runs several small services in Node, Python or Rust and wants one catalog where new capabilities can be added at runtime rather than wired in per project. Avoid it if you need a stable API surface today: the newest releases are 0.26.0 release candidates, and the repository metadata shows no licence identifier.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
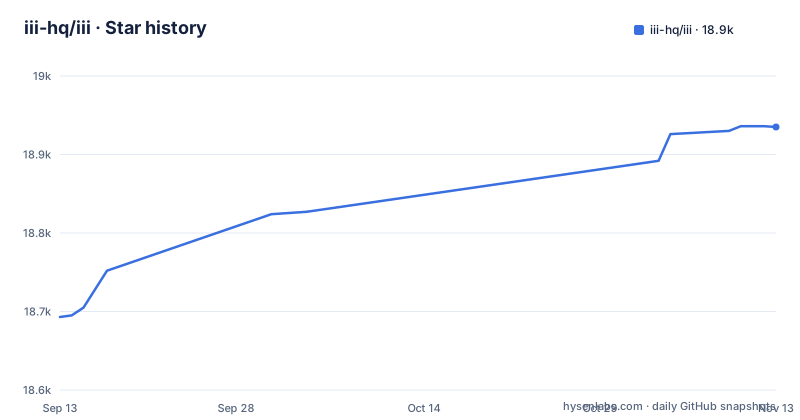
- iii-hq/iii18,935 ★ · +242
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| iii-hq/iii | 18.7k | 18.9k |
242 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The integration work iii is trying to remove
The README frames the problem with a before and after list. Before iii, a new observability tool means an uncountable number of integrations, a new agent harness means separate retry config, separate traces and separate timeouts, and a new queue means vendor evaluation, procurement and weeks of integration. The claim is not that iii makes any one of those tools better. It is that each one currently arrives with its own integration story, and iii collapses that into what it calls one live system surface. That is a real category of pain for platform teams, because the cost is not the tool itself but the glue around it. The target user is a platform or backend team running several small services across languages, who wants a single place to declare what exists and what can call what. A solo developer with one HTTP service and a database gets little from this: they already know every endpoint in their codebase.
Workers, Functions and Triggers as the whole model
The README states the mental model is three primitives. Workers are processes that register with the iii engine and then register triggers and functions. A TypeScript API service is a worker, a Python data pipeline is a worker, a Rust microservice is a worker. Functions are units of work with a stable identifier, with content::classify and orders::validate given as examples, and they live inside workers. Triggers are anything that causes a function to run: a direct call, an HTTP endpoint, a cron schedule, a queue subscription, a state change, a stream event. The README calls triggers declarative, meaning the worker states that this function runs when this thing happens, and iii handles routing, serialization and delivery. The interesting part is the direction of the dependency. Instead of service A importing a client library for service B, both register with the engine and calls go through function identifiers. That is what makes the runtime catalog possible, and it is also what makes the engine a component you cannot quietly drop later.
How a worker actually joins the system
Two paths exist in the documentation. The declarative path is worker-compose.yaml, where project workers are declared, then started with iii compose --up. The runtime path uses the Compose daemon: iii trigger -n dev compose::add worker=queue, or worker=agent, or worker=<anything>. The README states that each worker joins the live catalog and every other worker is notified and can call it immediately. The namespace flag -n dev appears in every trigger example, so the engine is addressed per namespace rather than as one global instance. The agent story is built on the same mechanism: when a task needs a capability the system does not have, an agent can add a worker, discover its functions, call them, and trace what happened. That is a notable design decision, because it means the runtime that agents extend is the same runtime developers use, not a separate tool-facing layer with its own permissions model described somewhere else. How authorization on compose::add is enforced is the first thing to look for in the Compose documentation.
Getting a project running: the commands in the README
Installation is a shell script: curl -fsSL https://install.iii.dev/iii/main/install.sh | sh. Then you declare project workers in worker-compose.yaml and run iii compose --up. The README's own summary of the change is three lines: declare workers in worker-compose.yaml, run them with iii compose --up, and it is in the system, traceable and callable. The opening example uses a namespace explicitly: iii compose --namespace dev --up, followed by iii trigger -n dev compose::add worker=queue. Four SDKs are listed with their install commands: iii-sdk on npm via pnpm add iii-sdk or npm install iii-sdk, iii-sdk on PyPI via pip install iii-sdk, iii-sdk on crates.io added to Cargo.toml, and a Go package fetched with go get github.com/iii-hq/iii/sdk/packages/go/iii. A Docker image is published as iiidev/iii. The README also documents agent skills for third-party harnesses, installed with npx skills add iii-hq/iii/skills.
The engine as a single point of coupling
The README makes the trade-off explicit without calling it one: extending iii is adding a Compose worker, composing iii is calling functions, observing iii is opening the trace. That sentence describes a system where the engine sits in the call path for everything. If the engine is unavailable, function-to-function calls that previously would have been direct HTTP or RPC between two services now have a component in between that must be up. Before adopting, look for what the documentation says about engine high availability, failover, in-flight calls during an upgrade, and compatibility of the function identifier scheme, which matters because content::classify and orders::validate are names other workers call by string. Renaming a function is an interface change. None of this makes the design wrong; a service mesh has the same property. It does mean that adopting iii is a decision about where your coupling lives, not a decision that removes coupling.
Versioning, licence and upgrade cost
The three most recent releases listed are iii/v0.26.0-rc.4, rc.3 and rc.2, all dated 2026-11-02. Those are release candidates, not stable tags, which suggests an active pre-1.0 line where the surface is still moving. The repository page shows no licence identifier, so I cannot state what the licence is or what it implies for redistribution or for linking the SDKs into proprietary services. Anyone evaluating iii for a commercial product should resolve that before writing code against it, and should treat the release candidate cadence as a signal that pinning a version matters more than usual. The SDKs are published to four package registries, so version skew between the engine and each language SDK is a real upgrade consideration: a worker written against one SDK version may not match the engine's current function and trigger registration protocol.
Where a conventional message broker is the better fit
The clearest alternative is a message broker plus a scheduler, for example NATS with its request-reply and queue semantics, or RabbitMQ with a cron sidecar. The difference in approach is who owns the contract. With a broker, a publisher writes to a subject and does not know or care which consumers exist; the subject is the interface, and adding a consumer requires no change to the producer. With iii, the function identifier is the interface and the engine routes by it, but workers register themselves with the engine and the README states that other workers are notified when one joins. That notification model is what enables runtime composition and agent-driven extension, and it is exactly what a broker does not give you. If your requirement is durable delivery, replay, backpressure and consumer groups across a partition, a broker is the tool with decades of operational literature behind it. Check iii's documentation for delivery guarantees, persistence and replay semantics for triggers before relying on them.
What to check before you start
Read the Compose documentation on worker-compose.yaml before anything else. That file defines what a project worker declaration actually looks like, and it is the artifact the rest of the workflow depends on. Then open workers.iii.dev and confirm that workers exist for the queue, cron, state and observability pieces you already run, because the value proposition depends on the catalog covering your stack rather than only the pieces iii ships itself. Check the Compose documentation for how compose::add is authorized in a namespace, since the README presents runtime worker addition as a feature for both developers and agents. Finally, confirm the licence from the repository itself rather than from this summary. If those four checks pass, the three-primitive model is small enough to learn in an afternoon, and the runtime composition is a genuine difference from wiring each service by hand.
Editorial conclusion
Adopt iii if your team already runs several small services in Node, Python or Rust and wants one catalog where new capabilities can be added at runtime rather than wired in per project. Avoid it if you need a stable API surface today: the newest releases are 0.26.0 release candidates, and the repository metadata shows no licence identifier. Before committing, read the Compose documentation on worker-compose.yaml, and check the workers.iii.dev catalog for whether a worker already exists for the queue, cron or state backend you depend on.
Frequently asked questions
What is iii?
iii is a system for composing, observing, discovering, extending and reacting to every service in a stack in real time, which the README abbreviates as CODER. It is built on three primitives: workers that register with the engine and then register triggers and functions, triggers that can be a call, an HTTP endpoint, a cron schedule, a queue subscription, a state change or a stream event, and functions with stable namespaced identifiers such as `content::classify` and `orders::validate`.
How do I install iii?
The README gives one command, `curl -fsSL https://install.iii.dev/iii/main/install.sh | sh`, which fetches an install script from a domain and pipes it into a shell with no checksum and no pinned version. A Docker image is published at `iiidev/iii`, and the engine is a Cargo workspace you can build from source with `cargo build -p iii`.
Which languages does the iii SDK support?
Node.js, Python, Rust and Go, all named `iii-sdk`. Node installs with pnpm or npm, Python with pip, and Rust by adding the crate to `Cargo.toml`. The Go SDK is the exception, installed with `go get github.com/iii-hq/iii/sdk/packages/go/iii`, so it is distributed from the repository rather than from a package registry.
Can I add services to a running iii system?
Yes. Workers are declared in `worker-compose.yaml`, or added at runtime through a running Compose daemon with `iii trigger -n dev compose::add worker=queue`. The new worker joins the live catalog, other workers are notified and can call it immediately, and the catalogue is browsable at workers.iii.dev.
Is telemetry enabled by default in iii?
The Makefile exports `III_TELEMETRY_ENABLED := false` for local development, so every make target inherits it switched off. The README names a telemetry worker among the engine-supplied workers that live in this repository, but it does not describe what that worker collects or where it sends it, so the code is where that question would be answered.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/iii-hq-iii)Star history chart for your README
[](https://hysenlabs.com/projects/iii-hq-iii)Was this useful?