mistral.rs: A Rust-based inference engine that trades vLLM peak throughput for model flexibility
Fast, flexible LLM inference
At a glance
- What is it?
- mistral.rs is a Rust inference engine that loads many model families, handles text, image, video, audio, and embeddings, and serves OpenAI and Anthropic compatible APIs. Its own benchmarks show it beating llama.cpp on prefill but trailing vLLM on large MoE models, so the right choice depends on your hardware and model mix.
- Who is it for?
- Adopt mistral.rs if you need one engine for many model architectures and modalities, especially if automatic model loading and its Q8 prefill lead over llama.cpp on the tested GPUs matter to you. Skip it if your workload is dominated by large sparse MoE models on multi-GPU servers, where vLLM shows a clear throughput lead in the project's own benchmarks.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
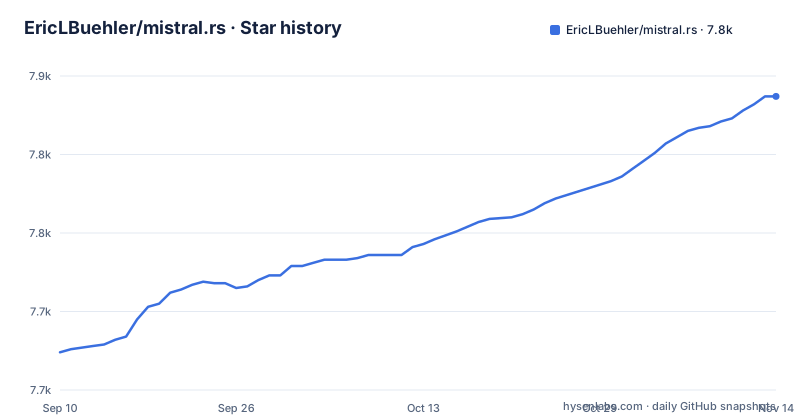
- EricLBuehler/mistral.rs7,837 ★ · +163
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| EricLBuehler/mistral.rs | 7.7k | 7.8k |
163 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What problem does mistral.rs actually solve?
Most inference engines tie you to one ecosystem. llama.cpp is GGUF-centric. vLLM is Python and PyTorch-centric, with its own serving stack. mistral.rs is a Rust engine that tries to be the universal adapter: it loads Hugging Face models and GGUF files, detects the architecture, weight format, and chat template automatically, and serves both OpenAI and Anthropic compatible APIs from one process. The intended user is an engineer who wants to run a wide range of open models, including multimodal ones, without maintaining several runtimes. The README lists support for text, vision, video, audio, speech generation, image generation, and embeddings. That breadth is the project's core value proposition, and it is rare to find it in a single binary.
How the engine works: loading, quantizing, and serving
The data flow is visible from the README's feature list. You point mistral.rs at a model. It detects the architecture, the weight format, and the chat template. For GGUF files, you can pass a local file with `-f` or select a published artifact with `--quant`. The tokenizer, configuration, and multimodal projector files are discovered when metadata identifies them unambiguously. For non-GGUF Hugging Face repositories, `--quant` selects a prebuilt UQFF artifact when one exists, and otherwise applies ISQ, which is in-situ quantization. The engine then serves via `mistralrs serve`, which exposes OpenAI-compatible `/v1` endpoints and Anthropic-compatible `/v1/messages` and `/v1/messages/count_tokens`. A Prometheus `/metrics` endpoint records per-request counts and latency labeled by method, route, and status. The built-in web UI at `/ui` shows reasoning, code execution, plots, and files, and lets you edit a message to branch with its own Python state. That UI is a differentiator; most engines force you to bolt on a separate frontend.
Getting it running: install commands and first steps
The repository ships installer scripts, install.sh and install.ps1, at its root, and the README links a Quickstart page on docs.mistralrs.dev. The README names `mistralrs serve` as the process that exposes the API endpoints. The `mistralrs tune` command recommends quantization and device mapping based on the model config and detected hardware. That is a practical first step after installation. The Python SDK and Rust crate are available for programmatic use, with their own documentation links.
Benchmark claims: strong prefill, mixed decode results
The README includes a v0.8.2 CUDA benchmark report comparing mistral.rs against llama.cpp and vLLM. On Q8 prefill, mistral.rs beats llama.cpp by a wide margin on Gemma 4 models. For example, on H100 SXM, mistral.rs reaches 26220.6 tokens per second versus llama.cpp's 11702.1 for Gemma 4 E4B. Decode is closer: 223.1 versus 183.0 on the same hardware. Against vLLM in BF16, the picture is less flattering. On the Gemma 4 26B-A4B model, vLLM leads prefill by a factor of roughly eight to ten on B200 and H100, and decode is also faster. On the smaller E4B model, mistral.rs is competitive or ahead on prefill, and it leads decode on all three GPUs. The README does not explain why the large MoE model shows such a gap. The benchmark methodology is described: mean tokens per second across prompt lengths and decode depths from 128 to 16384 tokens, with 256 generated tokens for decode. A full report is linked at `releases/v0.8.2/report.md`, which would be the place to verify host metadata and commands.
The UQFF format and GGUF loading: a deliberate bet
mistral.rs introduces its own quantized format, UQFF, which the project claims is faster for prefill than GGUF Q8_0. The benchmarks support that claim for the tested models. But a new format creates a compatibility question. The README says `--quant` selects a matching artifact from GGUF repositories, and for other Hugging Face repositories it uses a prebuilt UQFF when available, otherwise ISQ. That means you are not forced into UQFF. If you already have GGUF files, you can load them directly. The project also supports companion-projector GGUF loading for multimodal models, which is a practical touch. The risk is that UQFF is not the ecosystem standard. If you need to share quantized models with other tools, GGUF remains the safer choice. mistral.rs supports both, but its performance advantage is tied to UQFF, so you may have to weigh portability against speed.
Where it is the wrong tool: large MoE and multi-GPU serving
The benchmark table for Gemma 4 26B-A4B on B200 shows vLLM at 28532.8 tokens per second prefill versus mistral.rs at 3467.3. That is not a small gap. If your production workload is dominated by large sparse MoE models on data-center GPUs, vLLM appears to be the better choice based on the project's own numbers. mistral.rs is not positioned as a replacement for vLLM in that niche. The README's performance claims focus on GGUF and UQFF, and on decode where the differences are modest. If you need to scale one model across many GPUs with tensor parallelism, vLLM or another distributed engine is likely the safer path. Check the documentation for mistral.rs's own multi-GPU options before deciding.
Agentic features and API compatibility: more than a toy
The README lists an agentic runtime with web search, local Python code execution, shell execution, OpenAI-compatible Skills, session management, and custom tool hooks. Skills are uploaded as `/v1/skills` bundles and referenced from Responses requests. File inputs can be uploaded via `/v1/files` and attached to Responses or Chat parts. This is a substantial feature set that goes beyond simple inference. The Anthropic Messages API support means you can point Claude-oriented clients at mistral.rs. The web UI with inline code execution and branching Python state is another differentiator. These features make mistral.rs attractive for prototyping agents and for teams that want a single server for both OpenAI and Anthropic style clients. The trade-off is complexity. Each feature adds surface area for bugs, and running shell execution and Python code from a web UI is a serious security consideration. The workspace includes mistralrs-sandbox and mistralrs-code-exec crates, so read the agents guide for how sandboxing and resource limits work.
Maintenance, license, and what to verify before adoption
The project is under the MIT license, which is permissive and familiar. The repository shows regular releases: v0.9.3 on 2026-09-07, v0.9.4 on 2026-09-24, and v0.9.5 on 2026-10-19. That cadence suggests active maintenance. But the README mentions features like Muse Glimmer 30B and DiffusionGemma, which are niche model families. The project is broad, and broad means more code to maintain. The documentation links point to a separate docs site, which is a good sign, but the README itself is thin on operational details. Before adopting, you should verify that your specific model is in the supported models list at the documentation reference. You should also run the benchmark report commands on your own hardware, because the README's numbers are for specific GPUs and model revisions. The Prometheus metrics and the `/ui` are useful for operations, but check the HTTP API reference for authentication and rate limiting. For a production deployment, those are questions to answer before you commit.
Editorial conclusion
Adopt mistral.rs if you need one engine for many model architectures and modalities, especially if automatic model loading and its Q8 prefill lead over llama.cpp on the tested GPUs matter to you. Skip it if your workload is dominated by large sparse MoE models on multi-GPU servers, where vLLM shows a clear throughput lead in the project's own benchmarks. Before committing, verify that your exact model and hardware combination appears in the project's benchmark reports, and test with the `mistralrs tune` command to see what quantization and device mapping it recommends.
Frequently asked questions
what is mistral rs
A Rust project for fast, flexible LLM inference, published as a `mistralrs` binary plus a Rust crate and a Python SDK. It serves OpenAI-compatible `/v1` endpoints and Anthropic-compatible Messages endpoints from the same process, detects architecture, weight format and chat template for supported Hugging Face models and GGUF files, selects quantization with `--quant`, exposes Prometheus metrics at `/metrics`, and ships a web UI at `/ui`.
mistral.rs vs llama.cpp performance
The README's own v0.8.2 tables compare mean tokens per second across prompt lengths from 128 to 16384 with 256 decode tokens. On Q8, mistral.rs UQFF leads llama.cpp GGUF Q8_0 in every row, with prefill on Gemma 4 E4B on GB10 at 7395.7 against 3973.7. On BF16 against vLLM the result is mixed: mistral.rs leads on B200 prefill for E4B at 43547.8 against 39431.2 and trails on H100 SXM, and trails widely on the 26B-A4B model, with 3467.3 against 28532.8 prefill on B200.
mistral rs vs candle
They are not competitors: candle is the tensor and neural network library mistral.rs depends on. Four candle crates, candle-core, candle-nn, candle-flash-attn-v3 and candle-metal-kernels, are workspace dependencies at version 0.11.1, so upgrading candle means changing those versions in Cargo.toml.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 3 in the last 30 days; newest first.
- Six Serving Engines on Four Accelerators: Gemma 4 E2B on an RTX 3050, a T4, an L4 and a TPU v5edev.to · Nov 13, 2026 · 15 points · 1 comments
- Six Serving Engines on One Tesla T4: Gemma 4 E2B on a Turing GPUdev.to · Nov 11, 2026 · 4 points · 0 comments
- Six Serving Engines, One 8 GB GPU: Gemma 4 E2B on an RTX 3050dev.to · Nov 8, 2026 · 20 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ericlbuehler-mistral-rs)Star history chart for your README
[](https://hysenlabs.com/projects/ericlbuehler-mistral-rs)Was this useful?