Dragonfly: A Redis and Memcached Compatible Store That Scales Vertically
A modern replacement for Redis and Memcached
At a glance
- What is it?
- Dragonfly is a C++ in-memory data store that speaks the Redis and Memcached APIs without code changes. Its pitch is multi-core throughput on a single instance, and the README's own numbers show where that pitch holds and where it does not.
- Who is it for?
- Adopt Dragonfly if you run a single-threaded Redis instance that is CPU-bound and you want more throughput without adding a cluster layer or changing client code. Do not adopt it if your workload is already sharded across many Redis processes and your bottleneck is network, since the README's own numbers show Dragonfly's advantage narrowing to roughly parity on smaller instances and Memcached still beating it on read latency.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
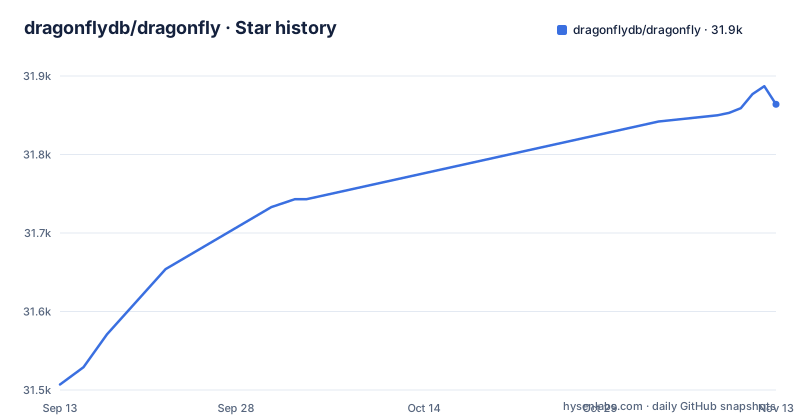
- dragonflydb/dragonfly31,864 ★ · +357
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| dragonflydb/dragonfly | 31.5k | 31.9k |
357 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem Dragonfly Targets: One Core Is Not Enough
Redis is single-threaded for command execution. The README states this directly when it explains why the first benchmark uses an m5.large instance, describing that instance type as commonly used to run Redis due to its single-threaded architecture. Once one core is saturated, adding CPU to the machine does not add throughput. The usual answer is to shard across multiple Redis processes or a cluster, which pushes complexity into the application or into a proxy layer. Dragonfly's stated goal is to remove that step. The README claims it delivers 25X more throughput than legacy in-memory datastores and can run on up to 80% less resources for the same sized workload. Those are marketing figures from the project itself, and the benchmark tables further down the same README are more modest, which is worth noting before you plan a migration. The audience is teams already running Redis or Memcached who want more capacity per instance and are willing to accept a younger implementation to get it.
What the Repository Layout Says About the Architecture
The project is written in C++. The README says the benchmark on the small instance shows that the algorithmic layer inside Dragonfly that allows it to scale vertically does not take a large toll when running single-threaded. In other words, on one core Dragonfly is roughly at parity with Redis, and the gap opens only as cores are added.
The Benchmark Tables, Read Carefully
The README's first comparison runs memtier_benchmark with -c 20 --test-time 100 -t 4 -d 256 --distinct-client-seed on an m5.large. For SETs, Redis reports 159K QPS at P99.9 1.16ms and Dragonfly 173K QPS at P99.9 1.26ms. For GETs, Redis reports 194K QPS at P99.9 0.8ms and Dragonfly 191K QPS at P99.9 0.95ms. That is close to a tie, and Dragonfly is slightly behind on GET throughput and on tail latency in both cases. Move to m5.xlarge with -t 6 and the picture changes: SETs go from Redis 190K QPS at P99.9 2.45ms to Dragonfly 279K QPS at P99.9 1.95ms, and GETs from Redis 220K QPS at P99.9 0.98ms to Dragonfly 305K QPS at P99.9 1.03ms. On c6gn.16xlarge the README claims a 25X increase over Redis single process, crossing 3.8M QPS, and in pipeline mode with --pipeline=30 it claims 10M QPS for SET and 15M QPS for GET. Against Memcached on the same instance type, Dragonfly is reported at 3844 thousand QPS for SET versus 806, and 3717 versus 2100 for GET, but Memcached shows lower read latency at 0.34ms P99 and 0.6ms P99.9 against Dragonfly's 1ms and 2.4ms. The honest summary is that Dragonfly wins on throughput at scale and loses on read latency to Memcached and on small-instance tail latency to Redis.
Getting It Running
The README points to a quick-start document at docs/quick-start rather than embedding the commands, and it links a build-from-source guide at docs/build-from-source.md. It also references a container image through the ghcr.io package badges. What the README does show is the client-side story: because Dragonfly is compatible with the Redis and Memcached APIs, the tools you already use apply. The benchmark commands are the clearest example, since they are plain memtier_benchmark invocations run from a separate load-test instance against the server. If you are evaluating it, the practical first step is to point an existing memtier_benchmark run at a Dragonfly instance on hardware comparable to your current Redis host and compare the output against your own baseline, not against the README's tables.
Where Dragonfly Is the Wrong Tool
The README's own numbers make the first limitation clear. On the m5.large, Dragonfly does not beat Redis on GET throughput or on P99.9 latency. If your Redis instance is small and lightly loaded, migrating buys you almost nothing and costs you a new dependency. The second limitation is read latency against Memcached. Memcached reports 0.34ms P99 and 0.6ms P99.9 on the GET benchmark where Dragonfly reports 1ms and 2.4ms. If your workload is a pure read cache with tight tail-latency requirements, Memcached's lower latency is the documented result, and Dragonfly's throughput advantage does not compensate for it. Third, the licence metadata in the repository is NOASSERTION. That means GitHub could not map the licence file to a known identifier. I am not giving legal advice, but a team that needs a clear OSI-approved licence for procurement should read the actual licence file in the repository before adopting, because the metadata alone will not answer the question. Fourth, compatibility claims need verification against your specific command set, especially if you use modules, Lua scripting, or less common data structures.
How It Differs From Running Redis in Cluster Mode
The obvious alternative is not another server but another topology: keep Redis and shard across several processes or a cluster. That approach is proven and well understood, and it scales horizontally by adding machines. The difference in approach is where the complexity lands. Redis Cluster pushes key-slot routing, cross-slot operation restrictions, and failover semantics into the client or a proxy. Dragonfly's approach is to scale vertically inside one process, so the client sees a single endpoint and a single keyspace, which the README frames as requiring no code changes to adopt. The trade-off is that vertical scaling has a ceiling: you are bounded by the largest machine you can buy, and the README's own benchmarks show capacity growing with instance size rather than staying flat. A cluster has no such single-machine ceiling, at the cost of operational complexity. Neither approach is universally better, and the choice depends on whether your constraint is engineering time or hardware spend.
Maintenance, Releases, and Upgrade Cost
The release cadence visible in the repository is active: v1.40.2 on 2026-09-03, v2.0.0 on 2026-09-16 and v2.0.2 on 2026-10-07, with the last push on 2026-10-04. Frequent patch releases mean you should expect to track patch versions rather than pinning a minor and forgetting it. The project maintains translations of the README in Simplified Chinese, Japanese, Korean, Portuguese and Thai, and it publishes an AGENTS.md guide for AI agents, both of which suggest a funded, organized effort rather than a single-maintainer project. If you run Dragonfly with snapshots enabled, check the project docs on snapshot compatibility before upgrading across versions.
Editorial conclusion
Adopt Dragonfly if you run a single-threaded Redis instance that is CPU-bound and you want more throughput without adding a cluster layer or changing client code. Do not adopt it if your workload is already sharded across many Redis processes and your bottleneck is network, since the README's own numbers show Dragonfly's advantage narrowing to roughly parity on smaller instances and Memcached still beating it on read latency. Before committing, verify three things yourself: that every command your application uses is implemented in your target version, that your licence situation matches the repository's NOASSERTION metadata, and that your eviction and persistence settings behave as expected under your real key sizes.
Frequently asked questions
Is Dragonfly a drop-in replacement for Redis?
The project states that Dragonfly is fully compatible with the Redis and Memcached APIs and requires no code changes to adopt, and that it supports common Redis arguments where applicable. `port` is the Redis connection port, with a default of 6379.
How do I install and start Dragonfly?
Container images are published under the `dragonflydb/dragonfly` package listing, and the quick start lives in the repository under `docs/quick-start`. Arguments follow the Redis shape, so `dragonfly --requirepass=foo --bind localhost` starts the server with a password and a local bind.
How does Dragonfly compare with Memcached on reads?
In the project's own comparison on a c6gn.16xlarge instance, Memcached shows lower read latency, 0.34ms at the 99th percentile against 1ms for Dragonfly. Dragonfly reports the higher GET throughput in the same table, 3717 thousand QPS against 2100, and the project notes that Memcached's read advantage comes with lower throughput.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Dragonfly License ChangeHacker News · Nov 4, 2026 · 2 points · 3 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dragonflydb-dragonfly)Star history chart for your README
[](https://hysenlabs.com/projects/dragonflydb-dragonfly)Was this useful?