html2pdf.js: client-side HTML to PDF in the browser
Client-side HTML-to-PDF rendering using pure JS.
At a glance
- What is it?
- html2pdf.js renders a DOM element to a PDF entirely in the browser by chaining html2canvas and jsPDF behind a promise-based Worker API. It is convenient when the PDF has to be produced on the client, and the wrong tool when you need selectable text or a server-side pipeline.
- Who is it for?
- Adopt html2pdf.js when the PDF must be produced in the browser from markup the visitor already sees, and when a rasterised page is acceptable. Do not adopt it when the output has to keep selectable text, stay small, or be generated without a browser.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
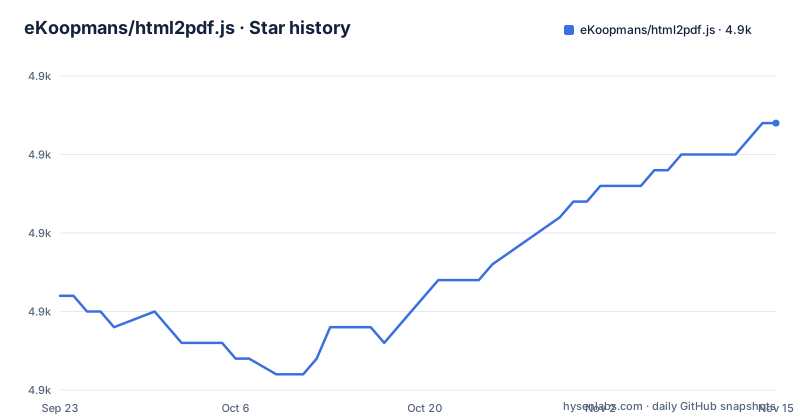
- eKoopmans/html2pdf.js4,937 ★ · +11
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| eKoopmans/html2pdf.js | 4.9k | 4.9k |
11 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What html2pdf.js actually solves, and for whom
The package turns a DOM element into a downloadable PDF without a server. The README states that it "converts any webpage or element into a printable PDF entirely client-side using html2canvas and jsPDF." Those two dependencies do the real work: html2canvas draws the element into a canvas, and jsPDF packs the resulting image into a PDF file. html2pdf.js is the glue, and the glue is the whole product.
That narrows the audience. It fits a front-end developer who already has the receipt, invoice preview or report on screen and wants a download button next to it, with no round trip and no rendering service. It does not fit a back-end job that has to produce thousands of documents, because the README is explicit: html2pdf.js "will not run in Node.js, it must be run in a browser." That single sentence removes the server-side use case from the table, and anyone who needs it should look at a different class of tool before reading further.
The trade-off is baked into the design. Because the element is rasterised into a canvas first, the PDF contains an image of the page, not text. Selection, search and copy inside the resulting file do not work the way they do in a text-native PDF. For a visual receipt that is fine. For a contract or an invoice that downstream software has to parse, it is a dead end.
The from, toContainer, toCanvas, toImg, toPdf, save pipeline
Calling html2pdf() with no arguments returns a Worker object, and the README describes the workflow as ".from() -> .toContainer() -> .toCanvas() -> .toImg() -> .toPdf() -> .save()". Each stage is a promise, and each stage has a prerequisite system so that intermediate steps run implicitly when you skip them. That is why the short form works at all: html2pdf().from(element).save() creates the canvas and the PDF object on the way to saving, without you naming those steps.
The Worker is a subclass of Promise, and the README documents three different continuation methods with different behaviour. The plain .then() re-binds this to the Worker and adds progress tracking. .thenCore() re-binds this but skips progress tracking. .thenExternal() is a true Promise method and "exits" the chain, so no further Worker methods can be chained after it. If you are inserting your own logic between rendering steps, that distinction decides whether the chain survives.
The source is not limited to an element. The from method takes a src and an optional type, and the README lists 'string', 'element', 'canvas' and 'img' as valid types. The same pattern applies to the output side: to() converts to 'container', 'canvas', 'img' or 'pdf', and each target also has a direct method. The aliases saveAs, using, export and run map onto save, set, output and then. They are convenience names, not extra capability, and mixing them in one file makes the chain harder to read.
Installing html2pdf.js from npm, CDN or the console
The README gives four install routes: CDN, raw JS, NPM and Bower. The npm install is the one to use in a bundler project, and the package name includes the .js suffix, which the README calls out explicitly.
npm install --save html2pdf.jsAfter that, importing the package and pointing it at an element is the whole first use. The README's basic example takes an element by id and passes it to the library, which then prompts the user to save the file.
var element = document.getElementById('element-to-print');
html2pdf(element);
The README notes that html2pdf.js "will not run in Node.js", so this code belongs in browser-side JavaScript, not in a build script or a server route. If you prefer a script tag, the README's CDN example pins a specific version and includes an integrity hash and a crossorigin attribute. Pinning is deliberate: the README says a CDN URL "will lock you to a specific version, which should ensure stability and give you control over when to change versions." cdnjs carries past versions if you need to move.
There is also a console route for pages you cannot modify. You paste a helper that appends the bundle script to document.head, then call html2pdf(document.body) to capture the whole page. That is a debugging and one-off capture technique, not a deployment path, and it depends on the CDN being reachable from the page.
Page breaks and image quality are the two knobs that matter
The README devotes separate sections to page breaks and to image type and quality, which is a fair signal about where the friction lives. Page breaks have their own settings and modes, with a pagebreaks.html file in the demo folder and a pagebreaks section in the README table of contents.
Image type and quality control the trade between file size and sharpness, because the content is an image. Raising quality raises the size of the embedded data. There is no text layer to fall back on, so the only lever is how many pixels and how much compression go into the canvas. For a one-page receipt this is invisible.
Progress tracking is documented as a separate feature and is wired into the Worker's .then() method. The README notes that .thenCore() omits progress tracking, which means the choice of continuation method is also a choice about whether you can show a progress indicator. If you plan to display a progress bar during a long render, that detail decides which method you chain with.
Where html2pdf.js is the wrong tool
The canvas round trip is the limitation. Everything the element contains becomes pixels, so the PDF has no selectable or searchable text, no accessible reading order, and no embedded fonts. Accessibility tooling that reads a PDF will see an image. If a workflow downstream needs to extract line items from the file, this library cannot supply them.
The dependency chain is also a maintenance surface. html2pdf.js depends on html2canvas and jsPDF, and the package.json adds dompurify as well. Each of those has its own release cadence and its own rendering quirks, and a fix in one of them may not reach you until html2pdf.js ships a new build.
Finally, fidelity is not guaranteed. html2canvas re-implements enough of CSS rendering to draw a page to a canvas, and complex layouts, unusual fonts or elements that depend on browser-native painting can come out differently from what is on screen. The demo folder includes all-tags.html, css-selectors.html and lorem-ipsum.html, which cover a range of markup. Treat the output as a close visual copy, not a faithful reproduction, and check the specific markup you care about.
html2pdf.js versus jsPDF on its own
The obvious comparison is html2pdf.js against jsPDF, and the difference is the input format. jsPDF is a document builder: you construct a PDF by issuing drawing and text commands, and the result contains real, selectable text. html2pdf.js is a capture tool: you hand it an element that already exists in the DOM, and it converts what is rendered into an image inside a jsPDF document.
That means jsPDF is the better choice when the PDF is a data artefact. Tables of numbers, generated reports and anything a machine will read later belong in a text-native document, and building it with explicit commands gives you control over fonts, spacing and file size. It is more work, because you write the layout twice: once in HTML for the screen and once in jsPDF calls for the file.
html2pdf.js wins when the layout already exists and duplicating it is the expensive part. A styled invoice preview, a certificate, a printable dashboard card: the browser has already done the layout, and rasterising it is a few lines. The cost shows up later, in file size and in the loss of text. Choosing between them is really a question about who consumes the PDF, a person looking at it or a program reading it.
Maintenance, licence and what an upgrade costs
The repository is not archived, and the last push was on 2026-11-02. The most recent release listed is v0.14.0 from 2026-01-12, following v0.13.0 on 2026-01-07 and v0.12.1 on 2025-09-17. Those dates describe a project that ships occasionally rather than continuously, and the gap between v0.12.1 and v0.13.0 is roughly four months. Plan for version bumps rather than a stream of patches.
The version number is still below 1.0, which is worth weighing if you depend on a stable API surface. The Worker API is documented in detail, including the alias table, but a pre-1.0 release carries no compatibility promise that a 1.x release would. Reading the release notes before bumping is the cheap precaution.
The licence is MIT, stated in both the README and package.json. That covers html2pdf.js itself. It does not automatically describe the dependencies: html2canvas and jsPDF are separate projects with their own licences, and the README's dependencies section points at them. If your organisation has rules about the licence of every package in the tree, check those two as well as this one. Nothing here is legal advice.
Editorial conclusion
Adopt html2pdf.js when the PDF must be produced in the browser from markup the visitor already sees, and when a rasterised page is acceptable. Do not adopt it when the output has to keep selectable text, stay small, or be generated without a browser. Before committing, verify the licence situation for html2canvas and jsPDF, check the version of the bundle you pin, and test one page break in the target browser.
Frequently asked questions
How do I use html2pdf.js to turn an element into a PDF?
Get the element with document.getElementById, then pass it to html2pdf, as in the README's example: var element = document.getElementById('element-to-print'); html2pdf(element);. That generates the PDF and prompts the user to save it.
What is html2pdf.js?
It is a JavaScript library that converts a webpage or element into a printable PDF entirely client-side, using html2canvas and jsPDF underneath. The README describes it as client-side HTML-to-PDF rendering in pure JS.
How does html2pdf.js differ from jsPDF?
jsPDF is one of the two libraries html2pdf.js is built on, and it builds a PDF from explicit drawing and text commands, so the output contains real text. html2pdf.js instead captures an existing DOM element as an image and places it in a jsPDF document, which is less work when the layout already exists but loses selectable text.
Is there an alternative to html2pdf.js?
Using jsPDF directly, one of the two libraries html2pdf.js is built on, produces a text-native PDF instead of a rasterised one, at the cost of writing the layout yourself.
How do I convert HTML to PDF in JavaScript with html2pdf.js?
Include the library, then pass a DOM element to it: var element = document.getElementById('element-to-print'); html2pdf(element);. The README notes it must be run in a browser and will not run in Node.js.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ekoopmans-html2pdf-js)Star history chart for your README
[](https://hysenlabs.com/projects/ekoopmans-html2pdf-js)Was this useful?