bb-browser: driving your logged-in Chrome from a CLI or MCP server
Your browser is the API. CLI + MCP server for AI agents to control Chrome with your login state.
At a glance
- What is it?
- bb-browser is an MIT-licensed TypeScript CLI and MCP server that runs commands inside your real Chrome session, so agents act with your existing logins. The design removes API keys and headless bot detection, and it also removes the isolation that made those approaches predictable.
- Who is it for?
- Adopt bb-browser when the work happens on sites where you already hold a session and no API exists: research across arXiv, Zhihu and GitHub, or pulling a YouTube transcript. Do not adopt it as a general scraping engine for unattended jobs, or anywhere the blast radius of your own credentials matters.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 169 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
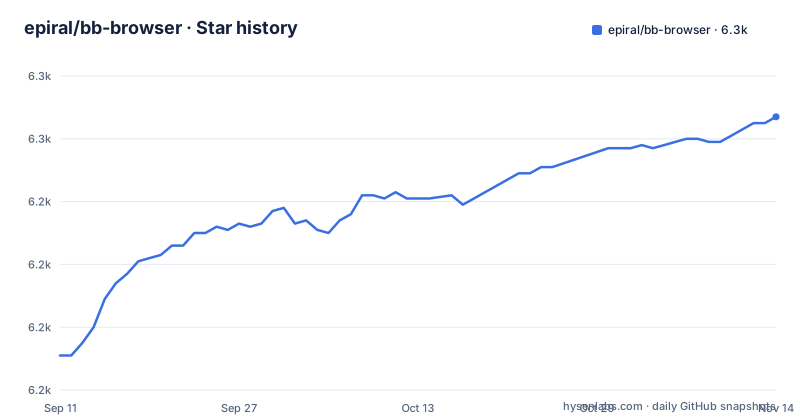
- epiral/bb-browser6,267 ★ · +76
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| epiral/bb-browser | 6.2k | 6.3k |
76 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: most of the web has no API, but it has your session
The README claims that 99% of websites do not offer an API. That number is the project's own framing, not a measurement, but the underlying situation is familiar to anyone who has tried to script a site: the data is rendered for a human, behind a login, and the only machine interface is whatever internal endpoint the page itself calls. The usual responses are to write a scraper, to drive a headless browser, or to give up and ask for an API key that will not be issued. bb-browser takes a fourth position. Instead of asking the site for a machine interface, it uses the human one, and it does so from the browser you are already signed into. The intended user is an AI agent operating through a CLI or an MCP client such as Claude Code or Cursor, and the person configuring that agent. The README's own example list is the clearest statement of scope: search tweets, read Zhihu trending, search arXiv, pull a stock quote from Eastmoney, search jobs on BOSS Zhipin, fetch a Wikipedia summary, retrieve a YouTube transcript, search Stack Overflow.
How an adapter actually runs inside the tab
The mechanism described in the README is that the adapter runs eval inside your browser tab, then either calls fetch() with your cookies or invokes the page's own webpack modules. That single sentence explains both the project's reach and its fragility. A tier 1 adapter, in the README's classification, is a direct cookie-authenticated fetch, which is why Reddit, GitHub and V2EX are listed at roughly a minute of work. Tier 2 adds a bearer token and a CSRF token, which is the Twitter and Zhihu case. Tier 3 reaches into webpack injection or a Pinia store, which is what Twitter search and Xiaohongshu require, and the README puts that at around ten minutes. The tiers are not a maturity ladder. They are a description of how much of the site's internal implementation an adapter depends on, and tier 3 adapters break when the site ships a new bundle. The transport path is documented as CLI or MCP over stdio into the CLI, then HTTP to a daemon, then a CDP WebSocket into the browser. The daemon listens on 127.0.0.1:19824 by default.
Install, the first three commands, and the daemon flags
Installation is a global npm package on Node 18 or newer: npm install -g bb-browser. The README's quick start is three commands. bb-browser site update pulls community adapters, bb-browser site recommend inspects your browsing habits and reports which adapters match, and bb-browser site zhihu/hot runs one. Adapters live in the separate epiral/bb-sites repository, one JS file per command, which is why site update exists as a distinct step. For MCP clients the configuration is an mcpServers entry with command npx and args ["-y", "bb-browser", "--mcp"]. There is a second execution path: if you use OpenClaw, the --openclaw flag routes through its built-in browser and the README states that no Chrome extension or daemon is required, as in bb-browser site reddit/hot --openclaw. Daemon binding is configurable with --host, and the README gives two reasons: 127.0.0.1 to force IPv4 and work around macOS IPv6 issues, or 0.0.0.0 to expose the daemon over Tailscale or ZeroTier. That second option deserves a pause. The daemon is the component holding a CDP connection to a browser with your logins, and 0.0.0.0 makes it reachable on every interface.
The automation surface beyond site adapters
bb-browser is also a general browser automation CLI, and this is the part that does not depend on the community adapter set. The README lists open, snapshot -i for an accessibility tree, click @3 and fill @5 "hello" against element references, eval for arbitrary JavaScript, fetch with an authenticated session, network requests with --with-body to capture traffic, and screenshot. Three flags apply across commands: --json for structured output, --jq for inline filtering, and --tab for concurrent multi-tab work. The --jq flag is what makes the output usable by an agent without a parsing step, and the README's example shows it: bb-browser site xueqiu/hot-stock 5 --jq '.items[] | {name, changePercent}'. There is also bb-browser site info, which prints an adapter's arguments, example and domain. The network --with-body command is the one the README points at for adapter authoring, since it is how an agent observes the calls a page makes before writing a tier 1 or tier 2 adapter.
Where the design breaks down
The README's comparison table presents the absence of anti-bot detection as an advantage: the site thinks it is you, because it is you. Read the same property from the other side and it is the project's largest risk. Every command runs with your cookies, in your profile, against your account. A misbehaving or outdated adapter is not a failed scrape; it is your account doing something you did not intend. The second limitation is stability. Tier 3 adapters reach into webpack modules and Pinia stores, which are private implementation details that change without notice, so an adapter that worked last month can fail silently after a frontend deploy. The release cadence shown in the repository metadata is high, with three releases in May 2026 alone, which is consistent with adapters chasing site changes but also means the surface moves. Third, the daemon is a local service with a CDP connection to your browser. The README documents --host 0.0.0.0 for Tailscale / ZeroTier remote access, so treating it as a trusted-network-only option is the cautious reading. Finally, the adapter catalogue is not part of this repository. The README states that the 103 commands across 36 platforms are community-driven via bb-sites, so adapter quality, correctness and upkeep sit outside the bb-browser codebase and its MIT licence.
Playwright and Selenium solve the opposite problem
The natural comparison is Playwright or Selenium, and the README's table frames the difference as headless and isolated versus your real Chrome. The practical consequence is about reproducibility. Playwright launches a browser you control, with a profile you define, so a run is repeatable: same browser build, same storage state, same viewport, and a test that either passes or fails for reasons in your code. bb-browser runs against whatever your Chrome currently is, with whatever extensions and sessions it currently holds, which is exactly why it works on sites that detect automation and exactly why it is a poor fit for a scheduled job that must behave identically every night. Server-side scraping libraries sit at a third point: no browser at all, cookie extraction or reverse-engineered endpoints, and a maintenance burden that lands on you when the site changes. bb-browser moves that burden into the adapter file and the community that maintains it. None of these is strictly better. The choice is which failure mode you can live with: a test that fails because the environment drifted, a scraper that breaks when the endpoint changes, or a command that runs as you and cannot be sandboxed.
Maintenance, versioning and the MIT licence
The repository is TypeScript, MIT licensed, not archived, and last pushed 2026-05-29 according to the metadata. The release history shows bb-browser-v0.11.6 on 2026-05-11, v0.11.5 on 2026-05-07, and v0.11.4 on 2026-05-07, so the project is pre-1.0 and shipping frequently. Pre-1.0 plus frequent releases means CLI flags and output shapes can change between minor versions, and the README's own examples are the contract you would be testing against. The MIT licence covers the bb-browser code. It does not cover the bb-sites adapters, which live in a separate repository, and it says nothing about the terms of service of the 36 platforms the adapters target. Automating a site with your own credentials is a decision about your account and that site's rules, not a licensing question. If you depend on an adapter, the version of that file matters as much as the version of the CLI, and site update is the command that will change it under you.
Editorial conclusion
Adopt bb-browser when the work happens on sites where you already hold a session and no API exists: research across arXiv, Zhihu and GitHub, or pulling a YouTube transcript. Do not adopt it as a general scraping engine for unattended jobs, or anywhere the blast radius of your own credentials matters. Before installing, run bb-browser site info on the adapters you intend to depend on and read their args and domain fields, because those files come from the separate bb-sites repository and their quality is not covered by the bb-browser release.
Frequently asked questions
What does bb-browser need before it will run?
Node.js 18 or newer, which is what the engines field in package.json asks for, and a Chrome profile you are already signed into. On Linux the repository's own Dockerfile runs headed Chrome under Xvfb, because headless mode is what anti-bot systems detect first.
Does bb-browser need an API key?
No, and that is the design rather than an accident. The adapter runs inside your own tab, calls fetch() with your cookies or reaches into the page's webpack modules, so the site sees the session that is already there.
How many sites does bb-browser actually cover?
The README states 103 commands across 36 platforms, and those adapters live in the separate bb-sites repository rather than in the npm package. `bb-browser site update` is what pulls them onto your machine.
Is bb-browser still being worked on?
The last push to the repository was on 2026-05-29 and the newest listed release tag is bb-browser-v0.11.6, published 2026-05-11. The manifest already reads 0.14.2, so the published tags trail the version in the source tree.
What is the difference between bb-browser and Playwright?
Playwright gives you a headless, isolated browser with no login state, so a script has to authenticate on its own. bb-browser attaches to the Chrome you already use, where the session is present and the page handles authentication itself.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/epiral-bb-browser)Star history chart for your README
[](https://hysenlabs.com/projects/epiral-bb-browser)Was this useful?