EvoScientist: a self-evolving multi-agent research system you run yourself
🔬 Harness Vibe Research with Self-evolving AI Scientists
At a glance
- What is it?
- EvoScientist is an Apache-2.0 Python package that runs a six-agent research team with a persistent memory graph, shipped through a CLI, a TUI and a Docker image. It is opinionated, it needs model API keys, and it assumes you are comfortable reading its own configuration files.
- Who is it for?
- Adopt EvoScientist if you want an opinionated research agent you can run on your own machine or in Docker, and if you are willing to supply your own model and search API keys and read the configuration it writes. Do not adopt it if you need a stable, versioned API for production software, or if you cannot accept that the memory graph and skill files are generated artifacts whose contents change as you use them.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
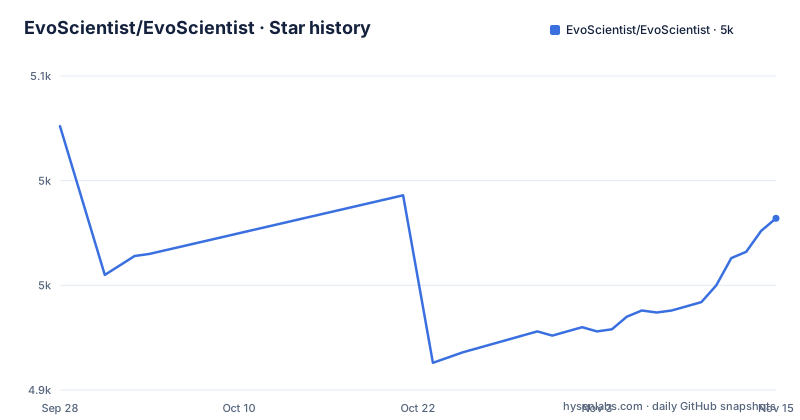
Star history
- EvoScientist/EvoScientist4,982 ★ · -44
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| EvoScientist/EvoScientist | 5k | 5k |
-44 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem EvoScientist solves, and who it is aimed at
Most agent frameworks give you a loop and leave the research method to you. EvoScientist takes the opposite position: the README describes it as "opinionated and ready to use out of the box", and that word carries weight. The project ships a fixed team of six sub-agents (plan, research, code, debug, analyze, write) plus a memory layer that is distilled each turn and linked into a knowledge graph that persists across sessions. The target user is a researcher or research engineer who wants an assistant that accumulates context over weeks rather than starting from an empty prompt every time.
The framing is deliberate. The README contrasts human-in-the-loop with what it calls a human-on-the-loop paradigm, where the AI is a research buddy that co-evolves with the human and, in the project's words, internalizes scholarly taste. That is a claim about long-run behaviour, not a feature you can check in a single run. The practical consequence is that EvoScientist is not a library you call from your own code. It is an application you drive, and it keeps state you did not write.
Six sub-agents, a memory graph and where your data lands
The mechanism visible in the repository is a LangGraph-based agent stack built on deepagents, with LangChain provider integrations for Anthropic, OpenAI, Google, NVIDIA, DeepSeek, Ollama and OpenRouter.
State lives in two places. The workspace directory is where the agent reads and writes files, and the data directory holds sessions, global skills, memories and config. In the Docker setup those are split explicitly: ./workspace is bind-mounted to /workspace, and a named volume evosci-data is mounted at /home/evosci/.evoscientist. That split is the important architectural detail. If you delete the volume you lose the accumulated memory graph and skills; if you delete the workspace you lose the artifacts. They are separate lifecycles and the compose file treats them that way.
The self-evolving part is the memory layer. According to the README it is auto-distilled each turn and self-links into a knowledge graph that grows across sessions.
Installing EvoScientist and running a first task
The package is on PyPI as EvoScientist and requires Python 3.11 or newer. The README points at the PyPI project page and the project website. The compose file reads a .env file through env_file.
uv syncThe repository carries a uv.lock, so uv sync installs the exact resolved set. If you prefer plain pip, the package name on PyPI is EvoScientist, and pyproject.toml declares the same dependency ranges.
The container path avoids the Python setup entirely. The compose file pulls ghcr.io/evoscientist/evoscientist:latest, reads your .env through env_file, and mounts the two directories described above.
docker compose upThe service is declared with stdin_open and tty, so it attaches to your terminal rather than running detached. Expect a terminal interface on first launch, not a web page; the README shows the WebUI, CLI/TUI and mobile surfaces as separate entry points.
Pinned upper bounds and provider churn
The dependency list contains three pins that tell you something about maintenance reality. openrouter is capped below 0.11.0 with a comment about SSE regressions causing teardown noise and mid-turn ReadTimeout. textual is capped below 8.2.7 because a Kitty report-all-keys change breaks CJK input on iTerm2. And deepagents is pinned with ~=0.7.32.
These are honest, documented workarounds, and they are also a warning. EvoScientist sits on top of a fast-moving layer of LangChain provider packages, and the maintainers are absorbing upstream breakage by holding versions back. If you install it into an environment where another tool needs a newer openrouter or textual, you have a conflict to resolve. The practical answer is to give EvoScientist its own virtual environment or its own container, which is what the Dockerfile does with /opt/venv.
The version cadence supports the same reading. Three releases landed between 2026-10-17 and 2026-10-31 (v0.3.7, v0.3.8 and v0.4.0), and the last push to the repository was on 2026-11-02. That is a project moving quickly, which is good for capability and bad for anyone who wants a frozen interface.
When EvoScientist is the wrong tool
It is the wrong tool if you need a deterministic pipeline. The self-evolving memory means the same prompt can take a different path on Tuesday than it did on Monday, because the distilled memory and the linked knowledge graph have changed. For a literature review that is acceptable. For a regulated process where you must reproduce an output exactly, it is disqualifying.
It is also the wrong tool if you have no budget for model calls. The architecture fans a task out across six agent roles and distills memory every turn.
Finally, the question of whether it replaces a scientist has a plain answer in the README's own framing: it is a research buddy that co-evolves with a human researcher. The awards section lists benchmark placements and an AI-Generated Best Paper recognition, but benchmark placement is a claim about a specific evaluation, not a statement about your domain. Treat the agent as a fast, well-read collaborator whose output you still have to verify.
How EvoScientist differs from a plain deepagents setup
The honest comparison is not against another product but against the framework EvoScientist is built on. deepagents gives you a general-purpose agent scaffold; EvoScientist fixes the roles, adds the memory distillation and knowledge graph, and ships the CLI, TUI, WebUI and container packaging around it. If you already run a deepagents stack, adopting EvoScientist means trading configurability for a working research loop out of the box.
Against a general coding agent, the difference is the persistence and the role split. A coding agent starts each session fresh and writes files. EvoScientist additionally writes memories and skills that survive into later sessions and change how later sessions behave. That is the whole proposition, and it is also the whole risk.
The provider story is where EvoScientist is genuinely broader than most single-vendor tools. The README lists Anthropic, OpenAI, Google, MiniMax and NVIDIA with one config to switch, and pyproject.toml adds LangChain integrations for DeepSeek, Ollama and OpenRouter.
Licence, upgrade cost and what to check before you commit
EvoScientist is Apache-2.0, declared in pyproject.toml and shown on the repository badge. That is a permissive licence with an explicit patent grant. It does not settle the question of what happens to the memories and skills the agent generates, because those are your data and the licence text governs the software, not your outputs. Check your own institution's rules before feeding unpublished material into a hosted model endpoint; this is a policy question, not a licensing one, and the repository does not address it.
The upgrade cost is real. Because the project absorbs upstream breakage with upper bounds, a version bump can move several provider packages at once. Upgrading means re-running uv sync against a new uv.lock and checking that your provider still works, and the three releases in October 2026 suggest that check will come up often. If you run the container, pin the image tag rather than tracking latest, since the compose file as written uses the latest tag.
One more thing worth verifying on your own machine: the Dockerfile builds a runtime image from a uv Python 3.11 base and copies Node 24 in from a separate stage, then links npm and npx. If you want an image built from your own checkout, build it by uncommenting the build block in docker-compose.yml instead of pulling the published image.
Editorial conclusion
Adopt EvoScientist if you want an opinionated research agent you can run on your own machine or in Docker, and if you are willing to supply your own model and search API keys and read the configuration it writes. Do not adopt it if you need a stable, versioned API for production software, or if you cannot accept that the memory graph and skill files are generated artifacts whose contents change as you use them. Before committing, verify two things against your own setup: that the provider you intend to use is listed in the README or pyproject.toml, and that the pinned dependency ranges in pyproject.toml resolve on your Python version.
Frequently asked questions
What is vibe research in EvoScientist?
The README uses the phrase in its opening line, describing the project as aiming to harness vibe research through self-evolving AI scientists that autonomously explore, generate insights and iteratively improve. It is the project's own label for its working style.
What does an AI scientist do in EvoScientist?
EvoScientist runs six sub-agents covering plan, research, code, debug, analyze and write, working together on a task. It also distills memory each turn into a knowledge graph that persists across sessions, so the system accumulates context instead of starting fresh.
How do I install EvoScientist?
The repository requires Python 3.11 or newer and ships a uv.lock, so uv sync installs the resolved dependency set. Alternatively, docker compose up pulls ghcr.io/evoscientist/evoscientist:latest and mounts ./workspace and the evosci-data volume.
Which model providers does EvoScientist support?
The README lists Anthropic, OpenAI, Google, MiniMax and NVIDIA, and pyproject.toml also depends on LangChain integrations for DeepSeek, Ollama and OpenRouter.
Does EvoScientist need a web search API key?
pyproject.toml lists tavily-python, the Tavily search client, as a dependency.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/evoscientist-evoscientist)Star history chart for your README
[](https://hysenlabs.com/projects/evoscientist-evoscientist)Was this useful?