fish2018/pansou: a self-hosted netdisk search API with an async plugin system
PanSou is a high-performance search API for cloud-drive resources, supporting Telegram channel and plugin search. Designed for performance and scalability with concurrent multi-channel/multi-plugin search, smart result ranking and cloud-drive type classification. Docker-based, integrating frontend and backend for one-click startup. For learning and research only; not for commercial use. https://t.me/s/webhtv
At a glance
- What is it?
- PanSou is a Go service that fans a keyword out across Telegram channels and plugins, then sorts and groups the netdisk links it finds. It ships as a Docker image with the frontend bundled, and the README is explicit that it is for study, not for running as a business.
- Who is it for?
- Self-host PanSou if you want a netdisk link search endpoint on your own machine and you accept that the upstream channels and plugins can change without notice. Do not adopt it as a commercial product: the README states it is for study and research and asks that it not be used for profit.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 34 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
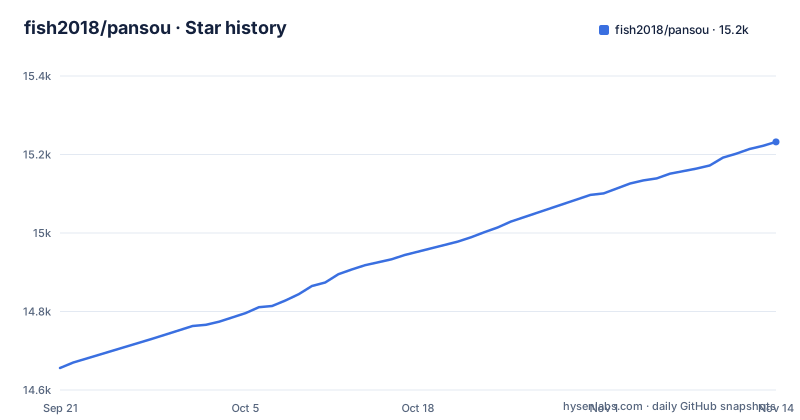
- fish2018/pansou15,232 ★ · +576
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| fish2018/pansou | 14.7k | 15.2k |
576 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap PanSou fills: one query, many netdisk sources
Netdisk links are scattered. A film might be on Baidu, a series on Quark, a software package on 115, and the only index of any of it is a Telegram channel that reposts share links all day. Searching each channel by hand does not scale, and the channels themselves are noisy: the same link appears repeatedly, older posts go stale, and link formats differ per provider.
PanSou turns that into a single HTTP endpoint. You send a keyword, it queries the Telegram channels listed in CHANNELS and the plugins listed in ENABLED_PLUGINS concurrently, extracts the links, classifies them by provider, and returns a sorted result set. The README lists fourteen categories it recognizes, including baidu, aliyun, quark, guangya, tianyi, uc, mobile, 115, pikpak, xunlei, 123, magnet, ed2k and others. That classification is the part that saves the most work: you get a magnet link in the magnet bucket instead of a bare string you have to inspect.
The audience is narrow and technical. You need to be comfortable running a container or building Go, and you need to understand that the search quality depends entirely on which channels and plugins you enable. PanSou is not a crawler with its own index. It is an aggregator over sources that other people maintain.
How the search pipeline actually works
The repository layout shows the split: api/, service/, plugin/, model/, config/, util/, with main.go at the top. The service layer is where the concurrency lives. According to the README, searches run concurrently across TG channels and plugins, with a worker pool managing the concurrent tasks, and the CONCURRENCY value defaults to being calculated automatically rather than fixed.
The plugin side is the more interesting design. PanSou supports an asynchronous mode described as "respond quickly, keep processing": a plugin that is slow does not hold up the response. ASYNC_RESPONSE_TIMEOUT defaults to 4 seconds, so the client gets whatever is ready by then, and the remaining plugin work continues in the background. ASYNC_MAX_BACKGROUND_WORKERS and ASYNC_MAX_BACKGROUND_TASKS bound that background work, defaulting to CPU cores times five and workers times five respectively, and ASYNC_CACHE_TTL_HOURS defaults to 1. The trade-off is real: a slow source may contribute nothing to the first response, and its results only surface on a later query for the same keyword.
Caching is two-tier. The README describes a sharded in-memory plus sharded disk cache, with SHARD_COUNT derived from the number of CPU cores by default (4 to 64, rounded up to a power of two), CACHE_TTL at 60 minutes, CACHE_MAX_SIZE at 100 MB, and CACHE_PATH at ./cache. CACHE_WRITE_STRATEGY accepts immediate or hybrid, with hybrid as the default, which suggests writes are batched rather than flushed on every entry. Ranking combines plugin level, recency and priority keywords, which means two deployments with different ENABLED_PLUGINS will order the same results differently.
Installing PanSou with Docker and running a first search
The README gives two deployment shapes. The integrated build bundles the frontend and listens on port 80; the backend-only image listens on 8888. The single command for the integrated version is the shortest path to something you can look at in a browser.
docker run -d --name pansou -p 80:80 ghcr.io/fish2018/pansou-webAfter that container starts, the web UI is on port 80 of the host. This image is the one to use if you want to click through results rather than script against the API.
For the API-only image, the README recommends Compose and gives a curl step to fetch the compose file first. The compose file in the repository pins the image to ghcr.io/fish2018/pansou:latest, maps 8888:8888, sets PORT=8888, and carries long CHANNELS and ENABLED_PLUGINS lists.
docker run -d --name pansou -p 8888:8888 ghcr.io/fish2018/pansou:latestOnce it is up, a search is a POST with a JSON body containing kw. The README's example searches for 速度与激情.
curl -X POST http://localhost:8888/api/search \
  -H "Content-Type: application/json" \
  -d '{"kw":"速度与激情"}'
The response is the aggregated, classified result set. If you enable authentication, every API route except login requires a bearer token, and the flow is two calls: log in, then pass the token.
curl -X POST http://localhost:8888/api/auth/login \
  -H "Content-Type: application/json" \
  -d '{"username":"admin","password":"admin123"}'
The response carries token, expires_at and username. AUTH_ENABLED defaults to false, AUTH_USERS takes the form user1:pass1,user2:pass2, AUTH_TOKEN_EXPIRY defaults to 24 hours, and AUTH_JWT_SECRET is auto-generated unless you set it. For a source build, the README requires Go 1.18 or later and the go.mod declares go 1.25.0, so the stated floor is looser than what the module actually asks for.
Where PanSou breaks down
The dependency on third-party channels is the largest limitation, and it is structural rather than a bug. CHANNELS is a list of Telegram channel names, and the compose file and Dockerfile each carry their own long list. Channels get renamed, go private or stop posting.
Plugins are the same story with an extra step. The README states that ENABLED_PLUGINS must be specified explicitly, which is a deliberate safety choice: you opt in to each source. But it also means the default Docker image's plugin list is whatever the maintainer picked, and the plugin files under plugin/ are scrapers against sites that can change markup at any time. A plugin that worked when it was written can return empty results indefinitely without raising an error the caller sees.
The async design has a cost that is easy to miss. With ASYNC_RESPONSE_TIMEOUT at 4 seconds, a slow plugin's results are not in the first answer. If you are building a UI that shows one result page, users will see a subset. The background work is bounded by ASYNC_MAX_BACKGROUND_WORKERS and ASYNC_MAX_BACKGROUND_TASKS.
Finally, this is the wrong tool if you need a search index you control. PanSou stores no corpus. It queries live sources on every cache miss, so results are only as available as the sources are, and there is no offline mode.
PanSou against a general web search API
The natural comparison is a hosted search API such as a general web search service. Those return ranked web pages; PanSou returns netdisk share links and magnet URIs. The difference in approach matters more than the difference in results.
A web search API maintains its own crawl and index, so latency is low and availability is contractual. PanSou maintains no index at all. Its freshness comes from the channels it reads, which is an advantage for netdisk links specifically, because a link posted ten minutes ago in a channel is already searchable, whereas a general crawler may never index a Telegram post. The cost is that PanSou inherits every availability problem of its sources.
Within the same niche, a TG-only search bot is the closer alternative. A bot queries one channel set and returns messages; PanSou adds provider classification and a ranking function on top, and exposes all of it as an HTTP API rather than a chat interface. If you only ever search one channel, a bot is less machinery. If you want to script against the results or build your own frontend, the API shape is the reason to pick PanSou.
Maintenance, licensing and what a fork implies
The repository is not archived, and the last push was on 2026-10-12, so the codebase is being touched. The repository has no published GitHub releases, which means the documented install paths point at moving tags: ghcr.io/fish2018/pansou:latest and ghcr.io/fish2018/pansou-web. Pulling latest on a schedule means you take whatever was pushed. If you need reproducibility, build from a pinned commit using the Dockerfile, which takes VERSION, BUILD_DATE and VCS_REF as build arguments for exactly that purpose.
The upgrade cost is concentrated in two places: the plugin directory and the channel list. A plugin written against a site's current HTML is the part most likely to need attention, and the repository ships a plugin development guide plus a skill document for AI clients, which is a signal that plugin upkeep is expected to be ongoing rather than occasional. The channel list needs periodic review for the same reason.
The licence is MIT. That permits commercial use as a matter of copyright, but the README states the project is for study and research and asks that it not be used for profit in any form. Those two things are not in conflict legally, but they are a clear statement of the author's intent, and anyone planning to run this behind a paid product should read that line before anything else. This is a description of the project's terms, not legal advice.
Editorial conclusion
Self-host PanSou if you want a netdisk link search endpoint on your own machine and you accept that the upstream channels and plugins can change without notice. Do not adopt it as a commercial product: the README states it is for study and research and asks that it not be used for profit. Before trusting it, verify that the channels in CHANNELS still exist, that the plugins you list in ENABLED_PLUGINS are the ones you actually want, and whether you need AUTH_ENABLED=true, since the default is an open API on port 8888.
Frequently asked questions
What is PanSou and who is it for?
PanSou is a netdisk resource search API service written in Go that searches Telegram channels and plugins concurrently, classifies the links it finds by netdisk provider and sorts the results. It is aimed at people who want a self-hosted search endpoint rather than a chat bot, and the README states it is for study and research only.
How do I install PanSou with Docker Compose?
The README recommends Compose for both images. For the backend-only version, download the compose file with curl from the pansou repository, then run docker-compose up -d and open http://localhost:8888. The compose file maps port 8888 and sets PORT, CHANNELS and ENABLED_PLUGINS.
Does PanSou require authentication by default?
No. AUTH_ENABLED defaults to false, so the API is open unless you turn it on. Setting AUTH_ENABLED=true with AUTH_USERS in the form user1:pass1,user2:pass2 makes every API route except the login endpoint require a JWT token, which the README's example obtains from POST /api/auth/login.
Why do PanSou plugin searches return nothing?
Plugins are scrapers against external sites, and the README requires ENABLED_PLUGINS to be specified explicitly, so a plugin that is not listed never runs. A listed plugin can also return empty results if the site it targets changed, and the asynchronous mode means a slow plugin's results may not appear in the first response because ASYNC_RESPONSE_TIMEOUT defaults to 4 seconds.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fish2018-pansou)Star history chart for your README
[](https://hysenlabs.com/projects/fish2018-pansou)Was this useful?