Fish Speech S2 Pro: A 4B Dual-AR TTS with Inline Emotion Tags
GitHub describes it as SOTA Open Source TTS. The repository metadata lists Python as its primary language. The metadata lists the NOASSERTION license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Fish Speech S2 Pro is an open-source multilingual text-to-speech model that uses a dual-autoregressive architecture and natural language tags for fine-grained emotional control. This review covers its architecture, setup, and the practical trade-offs of adopting it.
- Who is it for?
- Adopt Fish Speech S2 Pro if you need state-of-the-art multilingual TTS with fine-grained emotional control and are willing to manage a 4B-parameter model plus the dual-AR inference stack. Skip it if you require a permissive license (the codebase is under the Fish Audio Community License and the S2-Pro weights remain under the Fish Audio Research License) or if you need to deploy on edge devices, given the 4B slow AR and 400M fast AR components.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
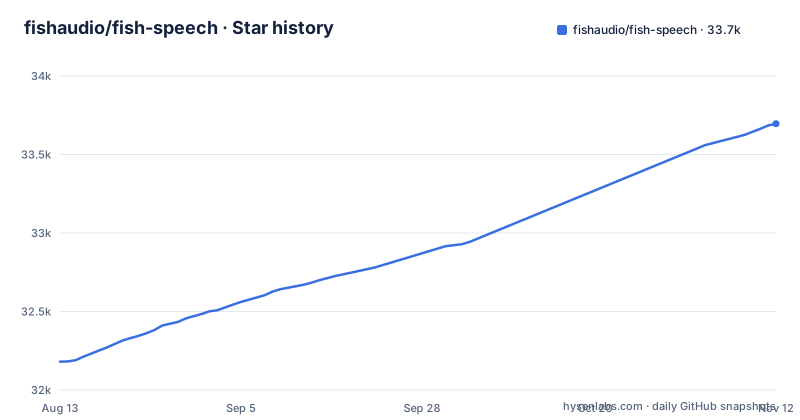
Star history
- fishaudio/fish-speech33,696 ★ · +1,516
| Repository | 2026-08-13 | 2026-11-12 |
|---|---|---|
| fishaudio/fish-speech | 32.2k | 33.7k |
1,516 Stars in the last 91 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Fish Speech Solves and Who It Is For
Fish Speech S2 Pro targets a specific gap in open-source TTS: fine-grained control over prosody and emotion without needing a separate voice actor or extensive audio editing. The README describes S2-Pro as the previous-generation flagship (4B parameters, about a hundred languages); the new-generation flagship is Drama 3 (35B-A3B). The core problem it addresses is that most TTS models offer only flat, neutral output, and you cannot easily inject a whisper, a laugh, or a shift in volume at a precise point in a sentence. S2 Pro's answer is inline tags like `[whisper]` or `[excited]` placed anywhere in the text. This is for developers building voice assistants, audiobook generators, game dialogue systems, or any application where emotional range matters. The README describes S2-Pro as small enough to deploy on a consumer GPU.
The Dual-AR Architecture: Why Two Autoregressive Models
The architecture is the most distinctive part of the project. S2 Pro uses a master-slave design with two autoregressive transformers. The slow AR, with 4 billion parameters, operates along the time axis and predicts the primary semantic codebook. The fast AR, with 400 million parameters, generates the remaining nine residual codebooks at each time step. This is a classic RVQ audio codec setup with 10 codebooks at roughly 21 Hz. The asymmetry is deliberate: the slow AR handles the high-level linguistic content, while the fast AR fills in acoustic detail. The README claims this design boosts inference speed while maintaining audio fidelity. The trade-off is that you cannot run just one part; you need both models, and the 4B slow AR sets the memory floor. For comparison, many smaller TTS models are single-pass, but they do not offer the same tag-driven control.
Getting It Running: Installation and Inference Paths
The README points to the official documentation at speech.fish.audio for installation, command-line inference, WebUI, and server inference. There is a Docker setup mentioned, which is often the easiest path for reproducible deployment. The key integration notes are for serving: the README explicitly references SGLang-Omni and vLLM-Omni for server-side inference. For SGLang, the README links the SGLang-Omni README for the fishaudio_drama_3 model. For vLLM, there is a recipe and a user guide for online serving. The README strongly recommends SGLang-Omni for users who care about efficiency. The command-line inference is documented, but the exact commands are not in the README, so you would need to visit the docs. The WebUI is an option for testing without writing code, which is useful for evaluating the tag syntax quickly. The Docker setup likely bundles the dependencies, which is a sensible default given the model's size.
Fine-Grained Control: The Tag System
The tag system is the project's main selling point. You can insert `[whisper in small voice]` or `[professional broadcast tone]` directly into the text, and the model interprets these as instructions. The README lists an emotion library with tags like `[pause]`, `[emphasis]`, `[laughing]`, `[inhale]`, `[singing]`, `[angry]`, `[whisper]`, `[screaming]`, and many more. It also claims support for over 15,000 unique tags, including free-form descriptions. This is not a fixed set of presets; the model can handle arbitrary text descriptions, which is a significant flexibility gain over discrete emotion labels. The mechanism is sub-word level control, meaning tags can affect a single word or phrase, not just the whole utterance. This is a different approach from models that use a global emotion parameter. The trade-off is that you must learn the tag syntax and anticipate how the model will interpret a phrase like `[with strong accent]`.
Benchmark Claims and What They Mean
The README includes a benchmark table with strong numbers: a WER of 0.54% on Chinese Seed-TTS Eval, 0.99% on English, and a 81.88% win rate on EmergentTTS-Eval. It also reports an Audio Turing Test posterior mean of 0.515, which it says surpasses Seed-TTS by 24% and MiniMax-Speech by 33%. On the multilingual MiniMax test set, it claims the best WER in 11 of 24 languages and best SIM in 17 of 24. These are impressive if true, but they are self-reported and not independently verified. The README also compares favorably to Qwen3-TTS and MiniMax Speech-02 on WER. As an engineer, you should treat these numbers as indicative but not gospel. The benchmark conditions, such as the exact test set and the prompt format, matter. The model's performance in your specific domain may differ, especially if your text includes unusual punctuation or code-switching. The S2-Pro section of the README reports RTF 0.195 on a single H200 and about 100 ms to first audio.
Reinforcement Learning Alignment and Its Implications
The model uses Group Relative Policy Optimization (GRPO) for post-training alignment. The README says it uses the same model suite for data cleaning and annotation as reward models, which it claims resolves distribution mismatch between pre-training data and post-training objectives. The reward signals are multi-dimensional, covering semantic accuracy, instruction adherence, and acoustic preference scoring. This is a notable design choice: instead of using a separate reward model, they reuse the same model family. That reduces training complexity but may introduce bias, since the reward model shares the same blind spots as the generator. For users, this means the model is optimized to follow instructions, which is good for the tag system, but it also means that the model's behavior is shaped by the RL process, and you may see unexpected outputs when the text falls outside the training distribution.
Licensing and Maintenance Costs
The license is listed as NOASSERTION, but the README states the codebase and its model weights are released under the Fish Audio Community License, while the S2-Pro weights remain under the Fish Audio Research License. Neither is a permissive license like Apache 2.0 or MIT. The README warns that they will take action against any violation. This has direct implications for commercial use: you must read the LICENSE file carefully to understand what you can and cannot do. The README also includes a legal disclaimer that they hold no responsibility for illegal usage, and it refers to DMCA and local laws. For maintenance, the project's last push was 2026-09-16, and the latest release is v3.0.0-beta (2026-10-13), following v2.0.0-beta (2026-03-10). The beta status of the newest release suggests that stability is not guaranteed. The documentation is spread across multiple sites (speech.fish.audio, HuggingFace, GitHub), which can be a maintenance burden. You should budget time for tracking releases and re-testing your integration.
Alternatives and When to Choose Them
The most direct alternative is a single-pass autoregressive TTS like Qwen3-TTS or MiniMax Speech-02, both mentioned in the README's benchmark comparisons. These models are likely simpler to deploy because they do not require a dual-AR setup or a specific serving stack like SGLang-Omni. The difference in approach is that they may offer global emotion control rather than sub-word tags. If your application does not need fine-grained control, a simpler model could be easier to maintain and less resource-intensive. Another alternative is a traditional concatenative TTS, but that is a completely different approach, requiring a voice database and offering no emotional variation. For most developers, the choice comes down to whether the tag system justifies the extra complexity. If you need precise emotional expression, the inline tag system is S2 Pro's main draw.
Editorial conclusion
Adopt Fish Speech S2 Pro if you need state-of-the-art multilingual TTS with fine-grained emotional control and are willing to manage a 4B-parameter model plus the dual-AR inference stack. Skip it if you require a permissive license (the codebase is under the Fish Audio Community License and the S2-Pro weights remain under the Fish Audio Research License) or if you need to deploy on edge devices, given the 4B slow AR and 400M fast AR components. Before committing, verify the exact license terms for your use case, test the tag syntax on your target languages, and check the SGLang-Omni or vLLM-Omni integration guides, which the README points to for serving.
Frequently asked questions
what is fish speech
Fish Speech is a Python text-to-speech project from Fish Audio, published as fish-speech version 3.0.0 and requiring Python 3.10 or newer. Its newest model is Drama 3 (35B-A3B); S2-Pro is the previous-generation 4B parameter model on HuggingFace that uses a Dual-Autoregressive architecture with a 400M fast component, an RVQ codec of 10 codebooks at about 21 Hz, and inline bracketed tags for emotion and prosody.
is fish speech open source
The README says the code and model weights are released under the Fish Audio Community License (pyproject.toml gives the same name), with the S2-Pro weights remaining under the Fish Audio Research License, and states that action will be taken against violations of it. The repository's license field records NOASSERTION, so the terms are only in the LICENSE file itself. It also carries a legal disclaimer about illegal usage and DMCA.
how to install fish speech
The README has no install command of its own. It sends you to https://speech.fish.audio/install/, with a Docker Setup section on the same page, and the repository ships compose.yml with a server service on port 8080, hidden behind a profile that you must name explicitly. In-tree requirements are Python 3.10 or newer and torch 2.8.0, with optional extras named stable, cpu, cu126, cu128 and cu129.
how to use fish speech
The project splits usage into four documented paths on speech.fish.audio: command line inference, WebUI inference, server inference, and Docker setup. If you want it behind an existing inference stack instead, the README points to the SGLang-Omni model README and to the vLLM-Omni Fish Speech S2 Pro recipe and text-to-speech user guide rather than documenting those routes itself.
fish speech vs qwen3-tts
The README's comparison is its own benchmark table, which reports S2 at 0.54% Chinese and 0.99% English word error rate on Seed-TTS Eval against 0.77 and 1.24 for Qwen3-TTS, plus an Audio Turing Test posterior mean of 0.515. Those numbers come from the project, not from an independent evaluation, so treat them as a claim to check rather than a settled result.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fishaudio-fish-speech)Star history chart for your README
[](https://hysenlabs.com/projects/fishaudio-fish-speech)Was this useful?