jieba: A Mature Chinese Tokenizer That Still Stops at Hard Boundaries
Jieba: Chinese word segmentation.
At a glance
- What is it?
- jieba is a Python library for Chinese word segmentation with four modes, custom dictionaries, and keyword extraction. Its latest release, v0.42.1, dates from January 2020, but that stability comes with limits you should know before adopting it.
- Who is it for?
- Adopt jieba if you need a well-documented, MIT-licensed Chinese tokenizer for Python 2/3 with custom dictionary support and TF-IDF or TextRank keyword extraction. Do not adopt it if you require modern deep-learning segmentation out of the box, active maintenance, or guaranteed thread safety.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 27 months ago, on August 21, 2024.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
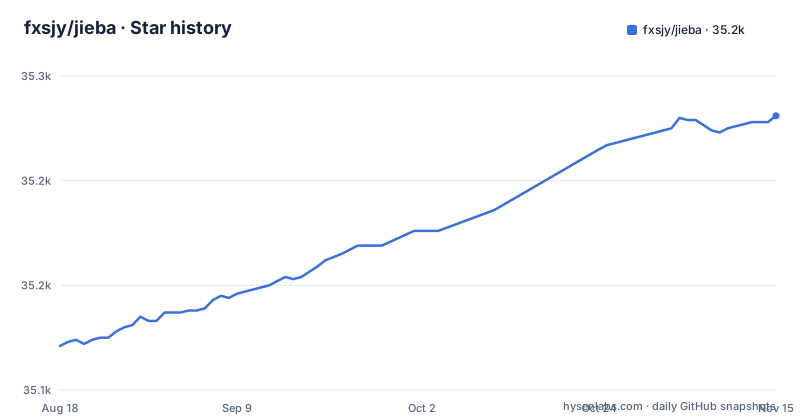
- fxsjy/jieba35,231 ★ · +110
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| fxsjy/jieba | 35.1k | 35.2k |
110 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What jieba Solves and Who It Serves
Chinese text has no spaces between words, so any NLP pipeline needs a segmentation step. jieba addresses this with a dictionary-based approach that also handles unknown words through an HMM. It targets Python developers who need a fast, local, no-service tokenizer for tasks like search indexing, text analysis, or preprocessing for downstream models. The README positions it as a general-purpose component, and the four modes give you a trade-off between precision and recall. If you are building a Chinese search engine, a content classifier, or a simple chatbot, jieba is a plausible default. It is less suited for production systems that demand continuous updates or that need to handle highly specialized jargon without heavy dictionary customization.
The Core Mechanism: DAG, Dynamic Programming, and HMM
The segmentation pipeline is described clearly in the README. First, jieba scans the sentence against a prefix dictionary to build a directed acyclic graph (DAG) of all possible word combinations. Then it uses dynamic programming to find the path with the maximum probability, based on word frequencies from the built-in dict.txt. For words not in the dictionary, it falls back to an HMM that models the likelihood of a character being part of a word, using the Viterbi algorithm to decode the best sequence. This two-stage design is why jieba can segment a sentence like "他来到了网易杭研大厦" and correctly output "杭研" even though that term is not in the dictionary. The README acknowledges the limits of new-word recognition by recommending custom dictionaries for higher accuracy.
Four Modes, One API: Choosing the Right Cut
jieba.cut accepts parameters that change the segmentation behavior. Full mode (cut_all=True) returns every possible word in the sentence, which is fast but ambiguous. The README example shows "我来到北京清华大学" becoming "我/ 来到/ 北京/ 清华/ 清华大学/ 华大/ 大学", which is noisy but useful for recall-oriented tasks. Default mode (cut_all=False) is the precise mode: it returns the most likely segmentation, such as "我/ 来到/ 北京/ 清华大学". Search mode (jieba.cut_for_search) further splits long words to support inverted index construction, as seen in the output for "中国科学院" which yields both the whole term and its parts. The fourth mode, paddle, uses a deep learning model from PaddlePaddle and requires a separate installation. The API returns a generator by default, so you can iterate lazily, or use jieba.lcut to get a list directly. This flexibility is a strength, but it also means you must understand which mode fits your use case, because the output can differ drastically.
Custom Dictionaries: The Real Power, With a Catch
The built-in dictionary is not comprehensive, especially for domain-specific terms. jieba lets you load a custom dictionary with jieba.load_userdict(file_name), where each line contains a word, an optional frequency, and an optional part-of-speech tag, separated by spaces. The README shows how adding "创新办" changes the segmentation of a sentence from "创新 / 办" to "创新办". You can also adjust the dictionary at runtime with add_word and del_word, and use suggest_freq to tune the frequency of a specific segment. The catch is that the automatically computed frequency may not work when the HMM new-word discovery is active, as stated in the README. This means you might need to experiment with the tune parameter to get the desired result. The custom dictionary is a solid feature, but it requires manual effort to maintain, and the format is strict: UTF-8 encoding, space-separated, three columns max.
Keyword Extraction and POS Tagging: Built-in, But Basic
Beyond segmentation, jieba includes keyword extraction and part-of-speech tagging. The jieba.analyse module offers extract_tags based on TF-IDF and textrank based on the TextRank algorithm. You can supply custom IDF and stop-word files, which is useful if your domain differs from the default corpus. The POS tagger (jieba.posseg) assigns tags compatible with the ictclas scheme, and in paddle mode it uses a different tag set with 24 lowercase tags and 4 uppercase named-entity tags. These features are convenient because they come with the library, but they are not state-of-the-art. The TextRank implementation uses a fixed window size of 5, configurable via the span property, and it builds an undirected weighted graph. If you need more sophisticated keyword extraction, you might outgrow this quickly. You should test on your own data to see if the quality meets your needs.
Parallel Processing and the Paddle Dependency
jieba offers a parallel mode that splits text by lines and distributes them across multiple Python processes using the multiprocessing module. The README notes that this mode is not supported on Windows, which is a real limitation if you are on that platform. The paddle mode, introduced in v0.40, uses a deep learning model and requires installing paddlepaddle-tiny==1.6.1, a specific version. This is a heavy dependency and a potential source of conflicts with other ML libraries. The README says paddle mode is loaded lazily via enable_paddle(), so you only pay the import cost if you use it. However, the pinned version is old (1.6.1), and the latest release dates from 2020, so you may face compatibility issues with newer Python versions or other packages. If you do not need deep-learning segmentation, you can ignore paddle mode, but if you do, be prepared for dependency management.
Maintenance Status and What It Means for You
The repository's last push was 2024-08-21, and the latest release, v0.42.1, dates from 2020-01-20. The README claims Python 2/3 compatibility, but Python 2 is end-of-life, and the project has not seen a commit in years. This is not necessarily a reason to avoid jieba, because the core algorithm is stable and the API is unlikely to change. However, you should treat it as a frozen library: no new features, no bug fixes, and no security patches. The MIT license gives you freedom to fork and modify, but you take on the maintenance burden. Before adopting it, check if your Python version is still supported by the library's dependencies (setup.py's classifiers list Python 2.6, 2.7, 3.2, 3.3 and 3.4).
Editorial conclusion
Adopt jieba if you need a well-documented, MIT-licensed Chinese tokenizer for Python 2/3 with custom dictionary support and TF-IDF or TextRank keyword extraction. Do not adopt it if you require modern deep-learning segmentation out of the box, active maintenance, or guaranteed thread safety. Before integrating, verify that the default dictionary covers your domain, test the HMM mode on your own text for out-of-vocabulary errors, and check whether the paddle mode's pinned dependency (paddlepaddle-tiny==1.6.1) conflicts with your existing ML stack. The last push was 2024-08-21 and the latest release, v0.42.1, dates from January 2020, so treat it as close to frozen: it works, but you own the fixes.
Frequently asked questions
How do you use Jieba in a Python program?
Install with pip install jieba, reference it with import jieba, then call jieba.cut for generators or jieba.lcut for lists, choosing precise, full, search or paddle mode for the task.
What is Jieba?
Jieba, Chinese for to stutter, is a Chinese text segmentation module built to be the best Python Chinese word segmentation component, supporting four cutting modes, traditional Chinese and custom dictionaries.
What is Jieba in Python?
It is a Python 2 and 3 compatible module exposing cut, cut_for_search, lcut, Tokenizer, analyse keyword extraction and posseg tagging, installable with pip install jieba.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fxsjy-jieba)Star history chart for your README
[](https://hysenlabs.com/projects/fxsjy-jieba)Was this useful?