GEPA: Reflective Prompt and Code Optimization Without Gradients
Optimize prompts, code, and more with AI-powered Reflective Optimization
At a glance
- What is it?
- GEPA (Genetic-Pareto) optimizes prompts, code and configurations by having an LLM read execution traces and propose targeted fixes. It installs with pip and runs against any metric you can measure, but it is not a drop-in replacement for reinforcement learning.
- Who is it for?
- Adopt GEPA if you already have a measurable evaluator and want prompt or configuration improvements without gradient training; the AIME quickstart and the optimize_anything API are the fastest ways to check fit. Do not adopt it if you need a stable API surface for a long-lived production pipeline, since the package is at 0.1.4.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
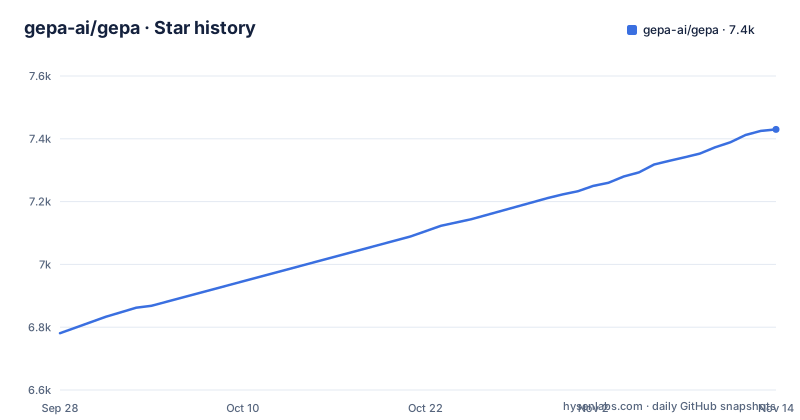
- gepa-ai/gepa7,430 ★ · +649
| Repository | 2026-09-28 | 2026-11-14 |
|---|---|---|
| gepa-ai/gepa | 6.8k | 7.4k |
649 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What GEPA Solves and Who It Is For
GEPA stands for Genetic-Pareto. The README describes it as a framework for optimizing any system with textual parameters against any evaluation metric, and the tagline is blunt about the scope: "If you can measure it, you can optimize it." The targets it names are prompts, code, agent architectures, scheduling policies and vector graphics. That is a wider net than most prompt-optimization libraries cast.
The intended user is someone who already has a scoring function. The optimize_anything example requires you to supply an evaluator that returns a float, so the framework assumes measurement exists before optimization begins. If you cannot score an output, GEPA has nothing to work with. That constraint is the real gate on adoption, not the install.
The comparison the README draws is against reinforcement learning and gradient-based methods. Its claim is that those approaches collapse execution traces into a single scalar reward, while GEPA uses an LLM to read error messages, profiling data and reasoning logs to diagnose why a candidate failed. The stated evaluation budget is 100 to 500 evaluations versus 5,000 to 25,000 or more for GRPO, which the README summarizes as 35x faster than RL. Treat those as the project's own figures from its paper and blog, not as independent measurements.
How the Reflection and Pareto Loop Actually Runs
The README describes the loop in numbered steps. First, select a candidate from the Pareto frontier, which it defines as candidates excelling on different task subsets. Second, execute that candidate on a minibatch and capture full execution traces. Third, reflect: an LLM reads the traces and proposes a change. Fourth, mutate: generate an improved candidate informed by accumulated lessons from all ancestors. Fifth, accept: add it to the pool if improved and update the Pareto front.
The design point worth noticing is the Pareto frontier. A single scalar reward picks one winner and discards everything else. Keeping candidates that win on different subsets preserves diversity, which is what lets later reflection steps combine strengths from different lineages. It also means GEPA holds a population in memory, not one best string.
The optimize_anything API exposes the trace channel directly. Inside the evaluator you call oa.log() with output and error text, and the README says that Actionable Side Information feeds back into reflection. This is the mechanism that separates GEPA from a random mutation loop: the reflection model sees what went wrong, not just that the score was low. Whether that produces a better fix depends entirely on the quality of what you log.
Installing GEPA and Running the AIME Quickstart
Installation is a single pip command. The README gives it without qualification:
pip install gepaTo track the main branch instead of the released version, the README offers a git install:
pip install git+https://github.com/gepa-ai/gepa.gitThe package declares requires-python >=3.10, <3.15 in pyproject.toml, so Python 3.14 is supported but 3.15 is not. The base package has no dependencies at all; the optional full extra includes litellm, tenacity and tqdm. Note the litellm exclusions (1.92.0, 1.92.1, 1.93.0, 1.93.1, 1.94.0, 1.94.1 and 1.95.0), which the pyproject comment explains as a wheel-availability workaround rather than a feature decision.
The first real use is the AIME math example. It initializes a dataset, defines a seed prompt, and calls gepa.optimize with a task model and a separate reflection model:
import gepa

trainset, valset, _ = gepa.examples.aime.init_dataset()

seed_prompt = {
    "system_prompt": "You are a helpful assistant. Answer the question. "
                     "Put your final answer in the format '### <answer>'"
}

result = gepa.optimize(
    seed_candidate=seed_prompt,
    trainset=trainset,
    valset=valset,
    task_lm="openai/gpt-4.1-mini",
    max_metric_calls=150,
    reflection_lm="openai/gpt-5",
)

print("Optimized prompt:", result.best_candidate['system_prompt'])
What you should see is a printed system prompt that differs from the seed. The README reports that this run takes GPT-4.1 Mini from 46.6% to 56.6% on AIME 2025, a ten point gain, for 150 metric calls. The result object exposes best_candidate, which is a dictionary keyed the same way as the seed you passed in.
For non-prompt artifacts, the optimize_anything entry point works differently. You write an evaluator that returns a float and log trace text through oa.log, then pass a seed string, the evaluator, an objective description and a GEPAConfig. The engine config in the README example sets max_metric_calls=100.
Where GEPA Is the Wrong Tool
The clearest limitation is the one the README states as a strength. GEPA assumes an LLM can read your traces and reason about them. If your evaluator returns a number with no accompanying text, you have removed the input the reflection step depends on, and the loop degrades toward blind mutation. Logging is not optional in practice even though the API makes it look optional.
Cost scales with metric calls, not with wall-clock time. Each reflection step is an LLM call, and each candidate evaluation runs your system on a minibatch. A 150-call budget against a slow agent is still 150 executions of that agent. GEPA reduces the number of evaluations relative to RL, but it does not make evaluation free.
The package is at version 0.1.4, released on 2026-07-15, with earlier releases on 2026-07-14. The last push to the repository was on 2026-11-02. A pre-1.0 version number is a signal about API stability. If you need a frozen interface for a long-lived pipeline, this is a risk you are accepting knowingly.
Finally, GEPA optimizes text. If your problem is a numeric hyperparameter or a model weight, the framework has nothing to offer; the README's own examples are all string artifacts, from system prompts to SVGs.
GEPA Versus dspy.GEPA and Plain Reinforcement Learning
The most direct alternative is dspy.GEPA, which the README calls the recommended path for AI pipelines and describes as the most powerful way to use GEPA for prompt optimization. The difference is not the optimizer; it is the substrate. In DSPy you compile a program whose modules carry signatures, and the optimizer mutates the prompts inside those modules. In standalone GEPA you pass a dictionary of strings and read back a dictionary of strings. DSPy gives you structure and composability across a multi-module pipeline; standalone GEPA gives you a smaller dependency surface and works on artifacts that are not prompts at all, such as the SVGs and scheduling policies the README names as targets.
Against reinforcement learning, the split is about where the learning signal lives. RL trains weights from scalar reward across thousands of rollouts. GEPA leaves the model frozen and edits the text around it. The README's own framing is that RL knows a candidate failed but not why, while GEPA reads the trace. The trade-off is that GEPA cannot improve anything the model does not already know how to do; it can only make the instructions better. If your task requires capabilities the base model lacks, prompt optimization will plateau, and no amount of reflection will move it.
Licence, Maintenance and Upgrade Cost
GEPA is MIT licensed, stated in the README badge and in the pyproject.toml license field. MIT is permissive: it allows commercial use, modification and redistribution provided the copyright notice and licence text are retained. That is the standard reading, not legal advice for your situation.
Maintenance signals are mixed. The last push was on 2026-11-02, and the repository is not archived. The release cadence shows 0.1.2 and 0.1.3 on 2026-07-14 and 0.1.4 on 2026-07-15, three releases in two days, followed by more than three months of commits without a release. That pattern suggests active work on main with releases cut in batches.
The upgrade cost is concentrated in the optional dependencies. The pyproject comment documents that litellm 1.92.0 introduced a native extension with manylinux wheels only, so on platforms without a wheel pip builds an sdist that needs Rust. The project responded by excluding the affected releases (1.92.0 through 1.95.0, while 1.92.2 stays allowed) and noting that each exclusion should be re-checked against PyPI before it is dropped. If you install the full extra, those exclusions are what keep pip from building litellm from source. The base package has no dependencies, so a minimal install avoids this class of problem entirely.
Editorial conclusion
Adopt GEPA if you already have a measurable evaluator and want prompt or configuration improvements without gradient training; the AIME quickstart and the optimize_anything API are the fastest ways to check fit. Do not adopt it if you need a stable API surface for a long-lived production pipeline, since the package is at 0.1.4. Verify first that your evaluator can run inside the optimize_anything callable and that your Python version falls inside the >=3.10, <3.15 range declared in pyproject.toml.
Frequently asked questions
What does GEPA stand for?
GEPA stands for Genetic-Pareto. The name reflects the two mechanisms in the optimizer: evolutionary mutation of candidates and Pareto-aware selection that keeps candidates excelling on different task subsets.
How does GEPA prompt optimization work?
The README describes a loop that selects a candidate from the Pareto frontier, executes it on a minibatch to capture full execution traces, then has an LLM reflect on those traces and propose a change. The reflection model reads error messages, profiling data and reasoning logs rather than a single scalar reward.
Can GEPA reflective prompt evolution outperform reinforcement learning?
The README states that GEPA needs 100 to 500 evaluations versus 5,000 to 25,000 or more for GRPO, which it summarizes as 35x faster than RL. Those are the project's own figures from its paper, not independent measurements.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/gepa-ai-gepa)Star history chart for your README
[](https://hysenlabs.com/projects/gepa-ai-gepa)Was this useful?