A course index, twelve algorithm directories, and two entries marked Coming soon
Repo for the Deep Reinforcement Learning Nanodegree program
At a glance
- What is it?
- Udacity's deep reinforcement learning repository is the public companion to a Nanodegree program, organized as one directory per algorithm plus a lab and three Unity based projects. Its notebooks target Python 3.6 and PyTorch 0.4, its benchmarks cite episode counts without seeds, and the PPO tutorial it advertises is not in the tree.
- Who is it for?
- Use this repository as a study archive and as a map of the classical to deep progression, where the ordering from dynamic programming through tile coding to DQN and DDPG is the actual teaching content.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 130 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
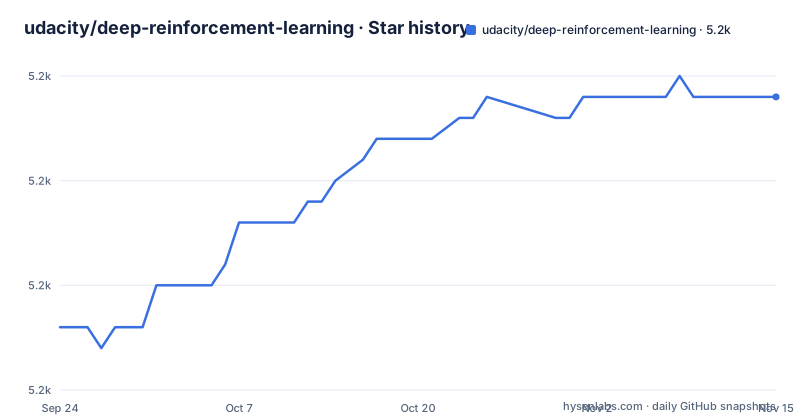
- udacity/deep-reinforcement-learning5,184 ★ · +11
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| udacity/deep-reinforcement-learning | 5.2k | 5.2k |
11 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The root is one directory per algorithm, plus four Unity projects
The layout is the syllabus. Every tutorial gets its own folder: `dynamic-programming/`, `monte-carlo/`, `temporal-difference/`, `discretization/`, `tile-coding/`, `dqn/`, `hill-climbing/`, `cross-entropy/`, `reinforce/`, `ddpg-pendulum/`, `ddpg-bipedal/`, and `finance/`. The lab and the three graded projects sit alongside them as `lab-taxi/`, `p1_navigation/`, `p2_continuous-control/`, and `p3_collab-compet/`.
Two more entries tell you how the project is governed. `CODEOWNERS` sits at the root, and `cheatsheet/` holds a PDF the README recommends for study. A `python/` directory also sits at the root.
The README is a table of contents with descriptions attached, not a guide. Each entry says what you will implement, from policy evaluation and policy iteration in dynamic programming through Sarsa, Q-Learning, and Expected Sarsa in temporal-difference, to hill climbing with adaptive noise scaling for the pole balancing cart and Monte Carlo policy gradients in `reinforce/`. Read it as a reading list with one line of intent per folder.
There is no CHANGELOG and no release history to fall back on, so a folder that changes shape over time leaves no trace in the repository itself.
The documented stack is Python 3.6 and PyTorch 0.4
Two sentences fix the environment for everything in the repository. The tutorials say that all of the code is in PyTorch (v0.4) and Python 3. The dependency setup then opens with step one: create and activate a new environment with Python 3.6.
PyTorch (v0.4)
Python 3.6
Read those two versions as a floor and a ceiling at once. Python 3.6 reached end of life years ago, and PyTorch 0.4 predates every current install path, so nothing in this repository installs on a machine you built this month without recreating an older toolchain or rewriting the notebooks.
The same age shows up in the benchmark identifiers. The environments named in the results table are `Acrobot-v1`, `Cartpole-v0`, `MountainCar-v0`, `MountainCarContinuous-v0`, `Pendulum-v0`, `BipedalWalker-v2`, `LunarLander-v2`, `CarRacing-v0`, `FrozenLake-v0`, `Blackjack-v0`, and `CliffWalking-v0`. That generation of environment names is the clearest signal of when this material was written, and it matters because a modern install of the same library will not necessarily resolve those identifiers.
The last push to the default `master` branch was on 2026-07-08, so the repository is being touched.
The benchmark table gives episode counts with no seeds attached
One section of the README is a results table, and it is the only quantitative claim in the repository. The entries that carry a number are:
`Cartpole-v0` with hill climbing, solved in 13 episodes. `Cartpole-v0` with REINFORCE, solved in 691 episodes. `MountainCarContinuous-v0` with the cross-entropy method, solved in 47 iterations. `MountainCar-v0` with uniform-grid discretization and Q-Learning, solved in fewer than 50000 episodes. `LunarLander-v2` with DQN, solved in 1504 episodes.
Each number is attached to one algorithm, one environment, and one notebook, and that is the entire context. No random seed, no tolerance definition for what counts as solved, no hardware note, and no statement about how many runs were attempted before the published one. Treat the spread as the honest part: 13 episodes for hill climbing against 691 for REINFORCE on the same environment says more about the two methods than any of the individual figures.
Three entries have no number at all, and their notebooks are still linked: `Acrobot-v1` with tile coding and Q-Learning, `Pendulum-v0` with DDPG, and `BipedalWalker-v2` with DDPG. So the table is a partial record, not a leaderboard.
PPO is announced in bold and missing from the tree
The tutorials list has twelve entries that resolve to directories and two that do not. Proximal Policy Optimization appears as a bolded bullet with the note that it is coming soon, and there is no `ppo/` directory anywhere in the repository. The Box2d benchmarks repeat the pattern: `CarRacing-v0` with deep Q-Networks is listed with DQN in bold and marked as coming soon, and no notebook is linked for it.
So a reader who scans the directory listing will find twelve algorithm folders and no sign of PPO, while a reader who scans the README will find PPO promised in the same list as Sarsa and DDPG. The italic markers are the only signal, and they are easy to lose in a list of that length.
Robotics is the third gap, and a different kind. That entry is not marked as coming soon; it is an external link to `dusty-nv/jetson-reinforcement`, described as a C++ API for training agents from virtual robotic simulation in 3D. The robotics lessons therefore live in another repository and another language, and the C++ part of the curriculum is not in this tree at all.
The finance tutorial has the opposite shape again: it stays in the repository as `finance/` and is described as training an agent to discover optimal trading strategies, with no benchmark line attached to it.
The four projects need Unity, so there are two toolchains
The README says all of the projects use rich simulation environments from Unity ML-Agents. It lists a lab and three projects: the Taxi Problem lab in `lab-taxi/`, Navigation in `p1_navigation/`, where the agent collects yellow bananas while avoiding blue ones, Continuous Control in `p2_continuous-control/`, where a robotic arm reaches target locations, and Collaboration and Competition in `p3_collab-compet/`, where a pair of agents play tennis.
Pair that with the tutorial stack and the shape of the course becomes clear. The notebooks want Python 3.6 and PyTorch 0.4; the projects want a Unity environment from ML-Agents. Nothing in the repository turns one into the other, so a learner moving from the first project to the second is switching runtime, not just switching folder.
The review process is tied to the program rather than to the code. The README says that in the Deep Reinforcement Learning Nanodegree program you receive a review of your project, and that those reviews exist to give personalized feedback on what can be improved in your code. So the three `p1`, `p2`, and `p3` directories are coursework with a grader attached, which is a different artifact from a maintained example. The homepage field points at the course page on Udacity's site rather than at documentation for the code.
Solution notebooks sit in the same folders as the exercises
The benchmark table links to files named for what they are: `Dynamic_Programming_Solution.ipynb`, `Monte_Carlo_Solution.ipynb`, `Temporal_Difference_Solution.ipynb`, `Discretization_Solution.ipynb`, `Tile_Coding_Solution.ipynb`, `Deep_Q_Network_Solution.ipynb` under `dqn/solution/`, plus `Hill_Climbing.ipynb`, `CEM.ipynb`, `REINFORCE.ipynb`, and two `DDPG.ipynb` files.
Committed solutions next to the exercises is a deliberate design for a teaching repository, and it is the right call for a learner who wants to compare an implementation against a reference. It also means the repository cannot double as a benchmark suite, because nothing distinguishes a reference run from any other run of the same notebook.
Two directory names add to the picture. `dqn/solution/` puts the reference implementation one level deeper than the exercise, which tells you the exercise and the answer are separate files in the same folder. And `python/` sits at the root alongside the algorithm folders.
The study aid most likely to survive the toolchain problem is `cheatsheet/cheatsheet.pdf`, since a PDF of algorithm summaries does not care which Python you installed.
No releases, a course homepage, and a MIT license
Maintenance facts here are thin, and they should shape how you use the code. The repository has no GitHub releases at all, so there is no version to pin, no upgrade path, and nothing to diff against. The license is MIT and a `LICENSE` file sits at the root, which makes reuse of the notebooks simple.
The rest of the metadata points back at the course rather than at a library. The description calls it the repo for the Deep Reinforcement Learning Nanodegree program, and the homepage is the Udacity course page. `CODEOWNERS` at the root, a `.github/` directory, and the README's invitation to follow the program for project reviews all describe a teaching artifact.
Contributing is not the path the README offers. There is no contributing guide and no pull request guidance in the README. For a collection of implementation notebooks, that is defensible: the content is the course, and the course has its own owner. For anyone planning to depend on this code, it is the deciding fact.
The last push to `master` was on 2026-07-08, which is recent enough that the files still get attention, and recent enough that nobody has rewritten the Python 3.6 setup steps.
Editorial conclusion
Use this repository as a study archive and as a map of the classical to deep progression, where the ordering from dynamic programming through tile coding to DQN and DDPG is the actual teaching content. Do not adopt it as a library, a benchmark suite, or a starting point for new work: there are no releases to pin, the notebooks assume an end of life Python, the environment identifiers are from an older generation of Gym, and the PPO tutorial the README advertises does not exist in the tree.
Frequently asked questions
What is deep reinforcement learning in this repository?
The repository teaches it as a progression of implementations: dynamic programming, Monte Carlo methods, temporal-difference methods such as Sarsa, Q-Learning, and Expected Sarsa, discretization and tile coding for continuous state spaces, and then the neural approaches including DQN, hill climbing, the cross-entropy method, REINFORCE, and DDPG. All of the code is in PyTorch (v0.4) and Python 3.
Where are the deep reinforcement learning examples?
One directory per algorithm, including `dynamic-programming/`, `monte-carlo/`, `temporal-difference/`, `discretization/`, `tile-coding/`, `dqn/`, `hill-climbing/`, `cross-entropy/`, `reinforce/`, `ddpg-pendulum/`, `ddpg-bipedal/`, and `finance/`, plus the `lab-taxi/` lab and three Unity ML-Agents projects named `p1_navigation/`, `p2_continuous-control/`, and `p3_collab-compet/`.
Is PPO part of this deep reinforcement learning course?
Proximal Policy Optimization is listed in the tutorials with a note that it is coming soon, and the repository contains no PPO directory. The same applies to the `CarRacing-v0` DQN benchmark, which is also marked as coming soon.
Is DQN covered in the deep reinforcement learning tutorials?
Yes. The `dqn/` tutorial is described as exploring how to use a Deep Q-Network to navigate a space vehicle without crashing, and a solution notebook is linked from the benchmarks for `LunarLander-v2`, which is reported as solved in 1504 episodes.
How do I set up the environment to run these deep reinforcement learning notebooks?
The README's dependency section starts by telling you to create and activate a new environment with Python 3.6, and the tutorials state that all code is in PyTorch (v0.4) and Python 3. The three project directories additionally use Unity ML-Agents environments.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/udacity-deep-reinforcement-learning)Star history chart for your README
[](https://hysenlabs.com/projects/udacity-deep-reinforcement-learning)Was this useful?