Paper2Code (PaperCoder): Turning a Machine Learning Paper into a Code Repository
Paper2Code: Automating Code Generation from Scientific Papers in Machine Learning
At a glance
- What is it?
- PaperCoder is a three-stage multi-agent LLM pipeline that reads a paper and writes a repository. It installs with pip, runs from scripts/run.sh, and costs roughly $0.50 to $0.70 per paper on o3-mini.
- Who is it for?
- Adopt PaperCoder if you already have a paper in LaTeX or the s2orc-doc2json JSON form and want a first draft repository rather than a blank editor. Do not adopt it if you need a guaranteed runnable artifact: the pipeline emits code, not a verified build.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
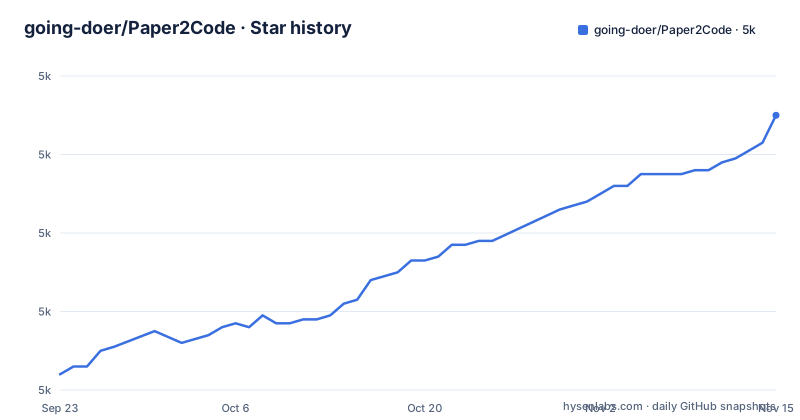
- going-doer/Paper2Code5,030 ★ · +66
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| going-doer/Paper2Code | 5k | 5k |
66 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What PaperCoder actually produces, and for whom
Reading a machine learning paper and reimplementing it is slow, and the gap between the prose and a working repository is where most of the effort sits. Paper2Code is the research project behind PaperCoder, a multi-agent LLM system that takes a paper and emits a code repository. The README frames the output as a repository, not a snippet: the example run writes planning_artifacts, analyzing_artifacts and coding_artifacts into outputs/Transformer, and the final code into outputs/Transformer_repo.
The intended user is someone who already has the paper in machine-readable form and wants a starting point. That is a narrower audience than "anyone who reads papers." If your paper exists only as a scanned PDF with no LaTeX source, you have to run the PDF-to-JSON conversion first, which the README treats as an optional preprocessing step rather than part of the core pipeline. The project also ships a benchmark dataset on Hugging Face under iaminju/paper2code and describes its own evaluation harness, so part of the audience is researchers comparing code-generation methods rather than engineers shipping software.
Planning, analysis, coding: the three-agent pipeline
The mechanism is a staged decomposition, and the output folder names mirror it. Planning agents read the paper and produce a plan. Analysis agents work through the artifacts of that plan. Coding agents turn the analysis into files. Each stage writes its own artifacts directory, so the intermediate state is inspectable after a run: outputs/Transformer/planning_artifacts, analyzing_artifacts and coding_artifacts sit next to the final Transformer_repo.
That separation is the design decision worth noting. Because the stages persist their output, a failure in coding does not destroy the plan, and you can read what the system believed about the paper before it wrote any code.
The system runs against two backends. With OpenAI it uses the API and the README estimates $0.50 to $0.70 for o3-mini on one paper. With vLLM it runs open weights locally, defaulting to deepseek-ai/DeepSeek-Coder-V2-Lite-Instruct. The two paths are separate shell scripts rather than a flag, which means the model choice is baked into which script you invoke.
Installing Paper2Code and running the bundled example
The quickest path is the OpenAI backend. Install the client, export the key, and run the script from the scripts directory. The README warns that the o3-mini path needs a current openai package.
pip install openai
export OPENAI_API_KEY="<OPENAI_API_KEY>"
cd scripts
bash run.sh
By default this runs the example paper, Attention Is All You Need. You should end up with an outputs directory containing Transformer, Transformer_repo and the three artifact folders. The README states that to run your own paper you modify the environment variables rather than editing the script, though it does not enumerate which variables those are.
If you would rather not pay per run, the vLLM path swaps the backend. The default model is deepseek-ai/DeepSeek-Coder-V2-Lite-Instruct, and the README points at the vLLM repository if installation fails.
pip install vllm
cd scripts
bash run_llm.sh
For LaTeX input there are separate entry points, run_latex.sh and run_latex_llm.sh, which take the paper source instead of the JSON form. If you only have a PDF, the README routes you through allenai/s2orc-doc2json: clone it, start the Gradle service in grobid-0.7.3, then call process_pdf.py with -i, -t and -o pointing at your PDF, a temp directory and an output directory. That is three tools and a Java service before PaperCoder itself runs, which is the real cost of the PDF path.
The evaluation harness scores repositories, it does not verify them
Paper2Code ships its own judge. codes/eval.py takes a paper, a generated repository, and optionally a gold repository, then asks a model to critique implementation components, assign severity levels and produce a 1 to 5 correctness score averaged over 8 samples using o3-mini-high. The README shows a reference-based run reporting a score of 4.5000 with 8 of 8 valid.
Read that number carefully. It is a model's opinion of the code, averaged over samples, not a test suite result. The README describes the evaluation as a model critiquing key implementation components and generating a correctness score. A repository can score well on component critique and still fail to import. The reference-free mode removes the gold repository from the comparison entirely, which makes it useful for triage but not for correctness claims.
This is the honest boundary of the project: it automates the writing of plausible code and the grading of that code by a model. If your acceptance criterion is "the numbers reproduce," the harness does not measure that, and you will need your own tests.
Where PaperCoder is the wrong tool
The pipeline assumes the paper describes something implementable from text alone. Papers whose contribution is a dataset, a theoretical bound, a hardware result, or a systems trick that depends on undocumented infrastructure will produce code that looks reasonable and does nothing useful.
Cost and rate limits are the second constraint. The README puts an o3-mini run at $0.50 to $0.70, and the evaluation step adds its own calls: 8 samples per repository with o3-mini-high. Sweeping several papers or re-running after tweaks multiplies that. The vLLM path avoids per-token billing but moves the cost to local GPU capacity and model quality, and the default is a Lite model rather than a frontier one.
Finally, there is no release history in the repository. The repository has no published GitHub releases, and the last push was on 2026-03-25. Treat it as a research artifact you drive by hand, not a service.
How it differs from Papers with Code and from plain LLM prompting
The comparison people reach for is Papers with Code, and the difference is categorical. Papers with Code is a catalogue: it indexes papers and links to implementations that humans wrote and released. PaperCoder generates an implementation when no release exists. If a paper already has an official repository, the reference-based evaluation path in eval.py expects you to point gold_repo_dir at it, which is an admission that the generated repository is being measured against human code rather than replacing it.
The other alternative is prompting a general coding assistant with the paper text. That is cheaper to start and gives you a conversation. PaperCoder's difference is the fixed three-stage decomposition with persisted artifacts per stage, plus a scoring harness that produces a comparable number across papers. You get reproducibility and an inspectable plan; you give up the ability to interrupt and redirect mid-run, which is exactly what a chat session gives you. For a one-off paper, prompting is probably faster. For comparing methods across a benchmark, the staged pipeline is the point.
Licence, dependencies and what upgrading costs you
The repository is Apache-2.0, which permits commercial use and modification, and the LICENSE file sits at the top level. Two caveats are worth stating plainly without pretending to be legal advice. First, the licence covers this repository, not the papers you feed it or the code the model emits; generated output may resemble training data in ways neither the licence nor the README addresses. Second, the evaluation path sends paper content and repository code to OpenAI, so anything confidential in a paper under review leaves your machine when you run eval.py.
Dependency cost is real. requirements.txt pins openai>=1.65.4, vllm>=0.6.4.post1, transformers>=4.46.3 and tiktoken>=0.9.0. vLLM is the heavy one, and the README itself tells you to consult the official vLLM repository if installation fails, which is a sign the maintainers expect friction there. The OpenAI path needs only openai and, for evaluation, tiktoken. Because the project has no releases, there are no versioned upgrade notes: you track the master branch.
Editorial conclusion
Adopt PaperCoder if you already have a paper in LaTeX or the s2orc-doc2json JSON form and want a first draft repository rather than a blank editor. Do not adopt it if you need a guaranteed runnable artifact: the pipeline emits code, not a verified build. Before committing, verify that scripts/run.sh picks up your own paper rather than the bundled Attention Is All You Need example, and check whether your inputs match the JSON schema produced by process_pdf.py.
Frequently asked questions
What is Paper2Code and what does PaperCoder do?
Paper2Code is the research project, presented at ICLR 2026, and PaperCoder is the multi-agent LLM system it introduces. PaperCoder transforms a paper into a code repository through three stages: planning, analysis and code generation.
How do I install and run Paper2Code?
Install the openai package, export OPENAI_API_KEY, then run bash run.sh from the scripts directory. For open weights, install vllm and run bash run_llm.sh, which defaults to deepseek-ai/DeepSeek-Coder-V2-Lite-Instruct.
How much does a Paper2Code run cost?
The README estimates $0.50 to $0.70 for using o3-mini on one paper. The vLLM path avoids API billing but requires local hardware and uses an open model instead.
Does PaperCoder work with a PDF instead of LaTeX?
Yes, but it is a separate preprocessing step. The README directs you to clone allenai/s2orc-doc2json, start its Gradle service, and run process_pdf.py to convert the PDF into JSON before running the pipeline.
How is a generated repository evaluated?
codes/eval.py uses a model-based approach in reference-based or reference-free mode, critiquing implementation components and producing a 1 to 5 correctness score averaged over 8 samples with o3-mini-high. It is a model judgement, not an execution test of the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/going-doer-paper2code)Star history chart for your README
[](https://hysenlabs.com/projects/going-doer-paper2code)Was this useful?