LiteRT-LM: Google's edge inference layer for LLMs, from CLI to C API
LiteRT-LM is Google's production-ready, high-performance, open-source inference framework for deploying Large Language Models on edge devices.
At a glance
- What is it?
- LiteRT-LM is Google's open-source orchestration layer for running large language models on edge devices. It wraps LiteRT with a cross-platform API, a CLI, and prebuilt C libraries, but its real value depends on the model formats and delegates you plan to use.
- Who is it for?
- Adopt LiteRT-LM if you are building on-device GenAI features for Android, iOS, Web, or IoT and you are willing to commit to the LiteRT model format and Google's toolchain. Do not adopt it if you need to run models that are not converted to .litertlm, or if you cannot absorb breaking C API changes; the README marks C API 1.0.0 as breaking.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
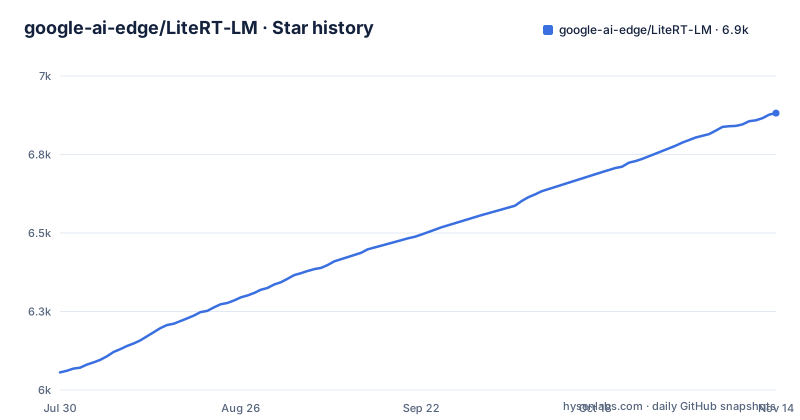
- google-ai-edge/LiteRT-LM6,882 ★ · +826
| Repository | 2026-07-30 | 2026-11-14 |
|---|---|---|
| google-ai-edge/LiteRT-LM | 6.1k | 6.9k |
826 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LiteRT-LM actually does
LiteRT-LM is not a model runtime by itself. It is an orchestration layer that sits on top of LiteRT, Google's existing on-device inference engine. The README describes it as a production-ready orchestration layer to run LLMs with LiteRT. In practice, that means it handles the plumbing around model loading, tokenization, sampling, and hardware delegation, so you can call a high-level API instead of wiring LiteRT's low-level components yourself. The target audience is developers shipping GenAI features in mobile apps, desktop apps, or browser extensions, and the README names Chrome, Chromebook Plus, and Pixel Watch as production users. If you are building a one-off script to test a model on your laptop, the CLI is the entry point. If you are embedding inference in a product, you would use one of the language APIs or the C API prebuilt.
The model format and the Hugging Face pipeline
The key constraint is the model format. The CLI examples pull from Hugging Face repos like litert-community/gemma-4-E4B-it-litert-lm and then run a file with the .litertlm extension, for instance gemma-4-E4B-it.litertlm. That extension is not a standard GGUF or ONNX. It is a LiteRT-specific container that presumably bundles the weights, tokenizer, and maybe metadata. The README does not explain the conversion process, but the existence of community repos with the -litert-lm suffix suggests that you must find or create a converted model. This is a real adoption barrier. If your model is not already converted, you will need to use LiteRT's conversion tooling, which is not documented in this README. The upside is that the format is designed for edge deployment, so it can include int4 quantization (the example model name gemma-3n-E2B-it-int4 implies that).
Running it: the CLI and the uv path
The quickest way to try LiteRT-LM is through the Python CLI installed with uv. The README gives this exact command: uv tool install litert-lm, then litert-lm run --from-huggingface-repo=google/gemma-3n-E2B-it-litert-lm gemma-3n-E2B-it-int4 --prompt="What is the capital of France?". For a more advanced example, the README's v0.19.0 section shows a command for Linux, macOS, Windows or Raspberry Pi that enables speculative decoding: litert-lm run --from-huggingface-repo=litert-community/gemma-4-E4B-it-litert-lm gemma-4-E4B-it.litertlm --backend=gpu --speculative-decoding=on --prompt="What is the capital of France?". The --backend flag accepts gpu, and the README mentions NPU acceleration. The --speculative-decoding flag is a concrete configuration option, and the README links a blog post saying multi-token prediction drafters make Gemma 4 models up to 3x faster at inference.
The C API prebuilt: a step toward language bindings
The repository root has c/ and prebuilt/ directories, and the README's v0.19.0 notes announce C API 1.0.0 as a breaking change: functions that can fail now return LiteRtLmStatusCode with results in out_* parameters, and only litert_lm_* symbols are exported. If you already call the C API, plan for that break when you upgrade.
Hardware acceleration and the YNNPACK experiment
LiteRT-LM's performance pitch rests on GPU and NPU delegates. The README claims peak performance via GPU and NPU accelerators, and the CLI example uses --backend=gpu. The v0.19.0 notes in the README add accelerated logit masking for faster constrained decoding on GPUs and say GPU sampling now matches CPU for the same seed. The broader point is that hardware support is uneven across platforms. The README lists Android, iOS, Web, Desktop, and IoT, but it does not specify which delegates are available on each. You will need to check the technical overview page for the performance benchmarks and the delegate matrix.
Multi-modality and tool use: the agentic angle
Beyond text generation, LiteRT-LM supports vision and audio inputs, according to the Key Features list. The README also mentions tool use, which is function calling for agentic workflows. The Google AI Edge Gallery app is cited as a way to try function calling on-device, and the README links to a blog post about fine-tuning FunctionGemma. This is a differentiator compared to simpler edge runtimes that only do text completion. However, the README does not go into the details of how the tool use API works, what functions you can define, or how the model is fine-tuned for that purpose. If your use case is a chat assistant that can call external APIs, LiteRT-LM seems to have first-party support, but you will need to dig into the documentation to understand the exact interface.
Licence and maintenance cost
The project is licensed under Apache-2.0, which is permissive for commercial use, but that does not cover the models themselves. The Gemma models have their own licence terms, which you must check separately. The repository is actively maintained, with releases v0.18.0 on 2026-10-06, v0.18.1 on 2026-10-20 and v0.19.0 on 2026-11-02. That cadence suggests fast iteration, but it also means you will need to track releases for bug fixes and API changes. The C API is versioned, and its 1.0.0 release was a breaking change. The README mentions Swift, JavaScript, and Flutter APIs and has a Supported Language APIs table with a status column. Before adopting, check the language-specific guides on the official site to see if your language is marked as stable or experimental.
Where LiteRT-LM is the wrong tool
If you need to run a model that is not available in the LiteRT-LM format, this framework is not for you. The conversion pipeline is not described in the README, and the examples all rely on pre-converted Hugging Face repos. If you want to run a custom fine-tuned model, you will have to convert it yourself, and the tooling for that is not shown here. Also, if you are targeting a platform that is not in the supported list, such as a custom embedded Linux board without arm64, you may not get prebuilt binaries. Finally, if you are looking for a pure Python solution that you can pip install and forget, the uv tool is convenient, but the C API and the native runtime are C++ at heart, so debugging issues may require C++ knowledge.
Alternatives and how they differ
The most direct alternative is llama.cpp, which is a C++ inference engine for LLMs that uses GGUF model files. The key difference is that llama.cpp is a standalone runtime, not an orchestration layer. You load a GGUF file and run it with a simple command, and it supports a wide range of hardware backends including CPU, CUDA, Metal, and Vulkan. LiteRT-LM, by contrast, is tied to the LiteRT ecosystem and the .litertlm format, which is less portable. If you want to run a model on a Raspberry Pi with minimal setup, llama.cpp might be simpler because it does not require a specific model conversion. Another alternative is ONNX Runtime with the GenAI extensions, which supports edge deployment and has a more established model conversion path from PyTorch. The difference is that ONNX is a broader standard, while LiteRT-LM is Google-specific and optimized for Google's hardware and software stack, such as Chrome and Pixel devices. If you are already invested in Google's ecosystem, LiteRT-LM is a natural fit. If you want maximum model portability, choose a GGUF-based runtime.
Editorial conclusion
Adopt LiteRT-LM if you are building on-device GenAI features for Android, iOS, Web, or IoT and you are willing to commit to the LiteRT model format and Google's toolchain. Do not adopt it if you need to run models that are not converted to .litertlm, or if you cannot absorb breaking C API changes; the README marks C API 1.0.0 as breaking. Before committing, verify that your target models (Gemma, Llama, Phi-4, Qwen) have a prebuilt LiteRT-LM conversion, and check the performance benchmarks on the technical overview page for your specific hardware. The project is actively maintained with frequent releases, so test on your actual deployment target.
Frequently asked questions
Which models are supported by LiteRT-LM?
The project names Gemma, Llama, Phi-4 and Qwen, and adds 'and more'. Anything narrower than that is deferred to a linked technical overview page rather than stated in the repository.
What is LiteRT-LM?
It is an Apache-2.0 C++ orchestration layer for running large language models with LiteRT, built for cross-platform execution on Android, iOS, Web, desktop and IoT devices such as a Raspberry Pi.
How do I use LiteRT-LM?
Install the CLI as a tool with uv tool install litert-lm, then run litert-lm run with a Hugging Face repository, a model artifact name, an optional --backend flag and an inline --prompt value.
What is LiteRT-LM for on-device AI?
It targets Android, iOS, Web, Desktop and IoT hardware with GPU and NPU acceleration, accepts vision and audio inputs, and supports function calling for agentic workflows. It is stated to power on-device features in Chrome, Chromebook Plus and Pixel Watch.
What is the difference between LiteRT-LM and LiteRT?
LiteRT-LM is the orchestration layer, and LiteRT is the runtime it drives, so the two are used together rather than chosen between. The repository declares C++ as the primary language and Apache-2.0 as the license.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 3 in the last 30 days; newest first.
- Six Serving Engines on Four Accelerators: Gemma 4 E2B on an RTX 3050, a T4, an L4 and a TPU v5edev.to · Nov 13, 2026 · 15 points · 1 comments
- Six Serving Engines on One Tesla T4: Gemma 4 E2B on a Turing GPUdev.to · Nov 11, 2026 · 4 points · 0 comments
- Six Serving Engines, One 8 GB GPU: Gemma 4 E2B on an RTX 3050dev.to · Nov 8, 2026 · 20 points · 1 comments
- Cleanup Walk: an Android app that turns screen time into a neighborhood cleanup.dev.to · Oct 10, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-ai-edge-litert-lm)Star history chart for your README
[](https://hysenlabs.com/projects/google-ai-edge-litert-lm)Was this useful?