Tunix: A JAX-native post-training library for TPU-centric LLM work
A Lightweight LLM Post-Training Library
At a glance
- What is it?
- Tunix is a JAX-based library from Google for SFT, DPO, PPO, GRPO, and agentic RL on TPUs. It targets teams already invested in the JAX/Flax stack, with vLLM and SGLang-JAX for rollout, but its early-stage status and TPU focus demand careful verification.
- Who is it for?
- Adopt Tunix if your team is already on JAX and TPUs, needs SFT, DPO, or RLHF-style training, and can tolerate an early-stage codebase with active development. Do not use it if you are on NVIDIA GPUs or want a mature, stable API.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
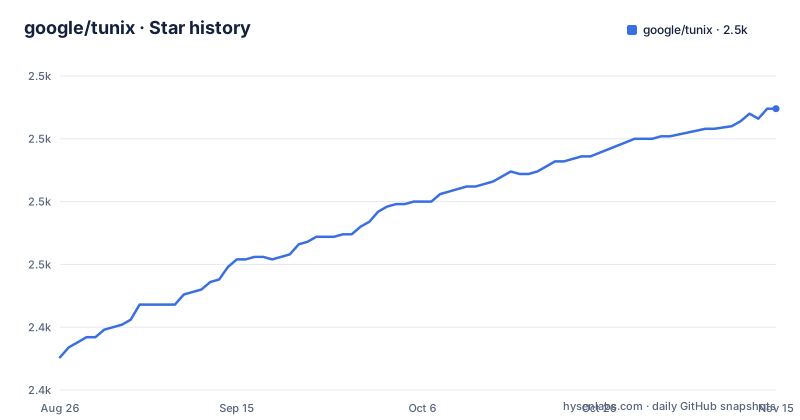
- google/tunix2,512 ★ · +99
| Repository | 2026-08-26 | 2026-11-15 |
|---|---|---|
| google/tunix | 2.4k | 2.5k |
99 Stars in the last 81 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Tunix actually solves
Tunix fills a specific gap: post-training large language models on TPU hardware using JAX. Most popular post-training frameworks are built around PyTorch and CUDA, which leaves TPU users stitching together custom training loops. Tunix aims to be the intermediate layer between low-level JAX utilities like Flax, Optax, and Orbax, and high-level model implementations like MaxText and MaxDiffusion. It covers supervised fine-tuning (SFT), preference optimization (DPO, ORPO), and reinforcement learning (PPO, GRPO, and newer variants like DAPO and Dr.GRPO). The intended audience is engineers who already run JAX workloads on TPUs and want a library that gives them these algorithms without abandoning their existing stack. If you are on GPUs, this library is not for you.
The architecture: a layer between JAX utilities and models
The README describes Tunix as sitting between foundational tools (Flax, Optax, Orbax) and optimized models like MaxText and MaxDiffusion. That means it does not reimplement model definitions from scratch; it integrates with existing JAX model families. The library uses Flax NNX as its modeling framework, which is a newer API for neural networks in Flax. For rollout during RL, it integrates with vLLM and SGLang-JAX, both of which have TPU support. The design is modular: components are meant to be reusable and composable, so you can swap out parts of the training loop. The documentation mentions micro-batching for efficient execution at the component level. This architecture is a trade-off: you get tight coupling with the JAX ecosystem, but you lose the plug-and-play compatibility that PyTorch-based libraries offer.
Installation and getting started
The README points to the official documentation for installation and quick start. For TPU users integrating vLLM and tpu-inference, there are two setup paths. The first is a Docker image build that uses a Dockerfile and installs pinned dependencies from requirements/requirements.txt and requirements/special_requirements.txt. The second is a local TPU VM or developer-machine install using scripts/install_tunix_vllm_requirement.sh, which installs the same requirement files outside Docker. These are separate entry points: if you build the Docker image, you do not need to run the install script inside the container. The README gives no direct pip install command, so you must follow the linked quickstart. Note that the Dockerfile path in the README is a local developer path (/usr/local/home/lancewang/...), which is a sign that the documentation may not be fully polished for external users.
Supported algorithms and models
Tunix covers a broad set of post-training methods. For SFT, it supports full fine-tuning and PEFT with LoRA. For preference optimization, it has DPO and ORPO. For RL, it lists PPO, GRPO, GSPO-Token, DAPO, and Dr.GRPO. Agentic RL is a newer addition, with multi-turn tool use, asynchronous rollout, and trajectory batching. The model support includes Gemma, Llama, and Qwen families. The README mentions that Gemma4 models are supported as of April 2026. The breadth is impressive, but it also means each algorithm and model combination may have different maturity levels. The README does not specify which algorithms are production-ready versus experimental. The release notes for v0.1.6 mention "Agentic RL & VLM," suggesting that vision-language model support is also in the works.
Performance and rollout integrations
A key selling point is performance on TPUs. The README claims SOTA training performance on TPUs, but it does not provide benchmarks or numbers. It highlights native integration with vLLM and SGLang-JAX for rollout, which is important because RL training is bottlenecked by generation speed. It also mentions native MaxText model integration for high-performance kernels, and specifically references splash attention and GMM MoE in the Qwen3 model code. These are concrete features: splash attention is a kernel optimization, and GMM MoE refers to grouped matrix multiplication for mixture-of-experts. The claim of scaling to thousands of devices via Pathways is ambitious, but without benchmark data, you cannot verify it. If you need evidence of performance, you will have to run your own tests.
Limitations and failure modes
The most obvious limitation is the hardware scope: Tunix is built for TPUs. If you are on NVIDIA GPUs, this library is the wrong tool. Even on TPUs, the integration with vLLM and SGLang-JAX is specific to TPU versions, and the installation instructions assume you have a TPU VM or are building a Docker image for TPU. The README states that Tunix is under active development and the contribution process is still being formalized. That suggests the API may change between releases. The v0.1.5 release was a "Critical Issue Fix for v0.1.4," which indicates that bugs can appear in minor releases. Another failure mode is the reliance on specific model implementations: if your model is not in the supported list (Gemma, Llama, Qwen), you will need to write your own integration. The README does not explain how to add a new model, just that the documentation covers it.
Alternatives and how they differ
The most direct alternative is TRL (Transformer Reinforcement Learning), a PyTorch-based library from Hugging Face that supports SFT, DPO, PPO, and GRPO. TRL works on GPUs and CPUs, and it integrates with the Hugging Face ecosystem, making it easy to use with any model on the Hub. The key difference is the underlying framework: TRL is PyTorch and CUDA, while Tunix is JAX and TPU. If you are already using JAX, switching to TRL means rewriting your training loop. Another alternative is veRL (Volcano Engine Reinforcement Learning), which is also PyTorch-based but focuses on large-scale RL with vLLM rollout. Neither alternative offers native TPU support in the way Tunix does. The choice comes down to your hardware and framework preferences.
Maintenance, license, and upgrade cost
Tunix is licensed under Apache-2.0, which is permissive and allows commercial use, modification, and distribution, with the caveat that you should review the full license text for any patent or notice requirements. The project is actively developed, with the last push in June 2026 and a release cadence of roughly every few months. The v0.1.x versioning indicates pre-1.0 status, meaning breaking changes are possible. The README notes that the contribution process is still being formalized, which could affect how quickly issues are fixed. Upgrade cost is moderate: you will need to track releases and test your training recipes after each update. The documentation and examples are the main resource for migration, but the README's truncated and developer-specific paths suggest that documentation may lag behind the code. Plan for time to verify that your existing Tunix scripts still work after an upgrade.
Editorial conclusion
Adopt Tunix if your team is already on JAX and TPUs, needs SFT, DPO, or RLHF-style training, and can tolerate an early-stage codebase with active development. Do not use it if you are on NVIDIA GPUs or want a mature, stable API. Before committing, verify that your models (Gemma, Llama, Qwen) are in the supported list, check the current documentation for the exact installation steps, and test the Docker or install script on your specific TPU environment, because the README's paths are from a developer's machine and may not match the repository.
Frequently asked questions
what is tunix google
Tunix, short for Tune-in-JAX, is a JAX based library for post-training large language models, covering supervised fine-tuning, reinforcement learning and agentic RL. It integrates with Flax NNX and with vLLM and SGLang-JAX for rollout, is licensed Apache-2.0 and requires Python 3.11 or newer.
Which JAX versions does the tunix package exclude?
The requirement reads `jax[tpu]>=0.6.0,!=0.7.2,<0.11.1`. Comments in pyproject.toml give the reasons: Jax 0.7.2 has a performance regression on OSS, and Jax 0.11.1 removed jax.experimental.hijax.MutableHiType, which flax through 0.12.8 still subclasses.
Does the Tunix Dockerfile run the install script?
Yes. It copies scripts/install_tunix_vllm_requirement.sh and requirements/ into the image and then runs `RUN bash scripts/install_tunix_vllm_requirement.sh`, even though the README states you do not need to run the install script inside the container build.
Which post-training algorithms does Tunix implement?
Supervised fine-tuning with full weights, PEFT, DPO and ORPO; reinforcement learning with PPO and GRPO, plus GSPO-Token, DAPO and Dr.GRPO; and agentic RL with multi-turn tool use, asynchronous rollout and trajectory batching and grouping.
What version of Tunix is declared in pyproject.toml?
0.1.8, under the package name google-tunix, with the classifier Development Status :: 3 - Alpha. The most recent GitHub release is v0.1.7, dated 2026-06-11.
Which model families does Tunix support?
Gemma, Llama and Qwen families, with a full list on the hosted models page. A news entry for 2026/01 links into tunix/models/qwen3/model.py for the efficient kernel work covering splash attention and GMM MoE.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-tunix)Star history chart for your README
[](https://hysenlabs.com/projects/google-tunix)Was this useful?