gosom/google-maps-scraper: a Go scraper for Google Maps business data
scrape data from Google Maps. Extracts data such as the name, address, phone number, website URL, rating, reviews number, latitude and longitude, reviews,email and more for each place
At a glance
- What is it?
- The project bundles a CLI, a local Web UI and a REST API around one Go binary that drives a headless Chromium through Playwright. It is aimed at lead generation and local business research, and the MIT licence keeps the code open.
- Who is it for?
- Adopt it if you already run Docker and want a self-hosted extraction pipeline you can script, because the README offers CSV/JSON output from the command line, a Web UI and a REST API. Do not adopt it if you need a hosted service with a support contract.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
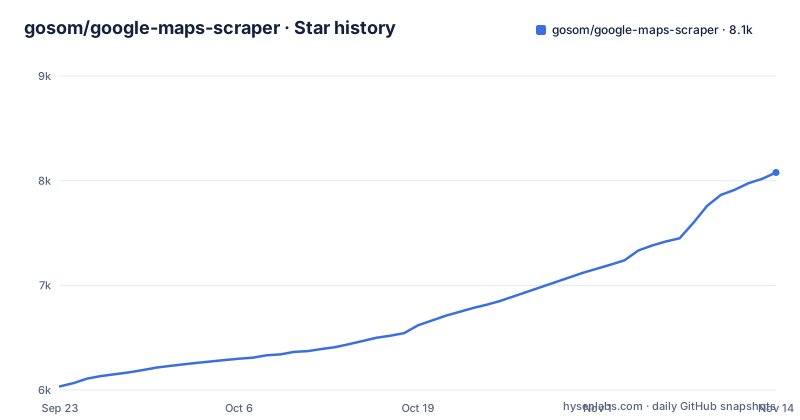
- gosom/google-maps-scraper8,078 ★ · +2,044
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| gosom/google-maps-scraper | 6k | 8.1k |
2,044 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What gosom/google-maps-scraper extracts and who it is for
The README describes the output as business leads: name, address, phone number, website URL, rating, review count, latitude and longitude, reviews, and email addresses. That is a lead-generation field set rather than a general-purpose web scraping toolkit. The README names the intended uses directly: lead generation, local business research, sales prospecting, data enrichment, and developer automation. If your job is to assemble a list of dentists in a city, or to enrich a CRM with phone numbers and coordinates, the field set matches the task.
The project is written in Go and ships as a single binary. The Dockerfile builds it with CGO_ENABLED=0 and copies the result to /usr/bin/google-maps-scraper, so the runtime image contains one executable plus the Chromium libraries Playwright needs. That packaging choice tells you who the project is for: people who want to run extraction themselves, on their own machine or their own infrastructure, not people who want to buy a hosted API key. The README also points to a SaaS Edition in docs/saas.md for a multi-user scraping platform, which is a separate deployment path rather than the default.
How the Go binary drives Chromium through Playwright
The mechanism is visible in the dependency list and the Dockerfile rather than in prose. go.mod requires github.com/mxschmitt/playwright-go v0.6100.0 and github.com/gosom/scrapemate v1.4.0. The Dockerfile installs the Playwright CLI at v0.6100.0, runs playwright install chromium --with-deps into /opt/browsers, and sets PLAYWRIGHT_BROWSERS_PATH and PLAYWRIGHT_DRIVER_PATH as environment variables in both the build and final stages. So the scraper is not an HTTP-only parser: it launches a real Chromium instance and reads the rendered page. That is the reason the final image carries libnss3, libatk, libgbm1 and the rest of the browser runtime libraries.
Around that core, the repository layout shows a queue and storage layer. go.mod includes riverqueue/river with the riverpgxv5 driver, jackc/pgx/v5 and modernc.org/sqlite, so jobs can be persisted in Postgres or SQLite. The top-level directories include gmaps/, scraper/, runner/, deduper/, leadsdb/, s3uploader/, ratelimit/ and rqueue/, which suggests the data flow is: a search query is queued, a runner picks it up, the scraper drives Chromium and extracts place records, the deduper removes repeats, and the result is written to a leads database or uploaded to S3. The README's own summary of the agent workflow says the agent plans the searches, runs a small validation, starts the full local scrape, and monitors it, which is consistent with a queued job model rather than a single blocking call.
Installing it and running a first scrape
The README gives two entry points. The one it calls the easiest is the AI agent skill, which needs Docker and Node.js on macOS, Linux, or Windows through WSL. The command installs the skill into an Agent Skills-compatible tool such as Claude Code, Codex, Cursor or GitHub Copilot:
npx skills add gosom/google-maps-scraperAfter that you describe the leads you want in plain language, for example asking for dentists in Berlin with websites and email addresses. The README states the agent checks for the latest skill and Docker image, and that for larger crawls you can supply your own proxy, continue without one, or review three randomly selected proxy sponsors. Proxy credentials are entered through a masked local terminal prompt and are never pasted into the agent chat.
The second entry point is the binary itself. The Makefile defines a build target that produces bin/google_maps_scraper, and a docker target that builds an image with Playwright:
make build
make docker
The Makefile sets VERSION to 1.18.1 and the cross-compile target emits bin/google_maps_scraper-1.18.1-linux-amd64, a darwin-amd64 build, and a windows-amd64.exe. The Dockerfile's ENTRYPOINT is google-maps-scraper, so a container run starts the scraper directly. The README's goal table points at the Command Line section for CSV/JSON output, the Web UI section for a browser interface, and the REST API section for calling it from an application. What you should expect to see after a first run is a CSV or JSON file containing one row per place with the fields listed earlier.
Where the documentation is thin: legality, rate limits and failure modes
The README's opening sections describe extraction, proxies and scale, and list sponsors who sell proxy bandwidth, but they do not state a position on whether scraping Maps is permitted. You are responsible for the legal question.
The failure modes you can infer from the architecture are the usual ones for browser-driven scraping. Chromium is heavy: the final image installs a long list of graphics and accessibility libraries precisely because a headless browser needs them, so memory per worker is not small, and the README's own framing of "larger crawls" implies that proxy supply becomes the constraint before CPU does. Because the scraper depends on the rendered page, a change to how Maps renders results can break extraction in a way that an API-based tool would not experience. Unless you confirm what happens to an in-flight job when a worker dies, treat the queue as at-least-once and deduplicate downstream. The deduper/ directory exists, which suggests the project expects duplicates.
It is also the wrong tool for some jobs. If you need a few dozen records once, the Docker plus Chromium setup is more machinery than the task deserves. If you need country-scale coverage with no keyword list, the README's own sponsor banner for Scrap.io advertises exactly that, which is an implicit admission that the open-source path is keyword-driven.
How it compares with SerpApi and the hosted scrapers it advertises
The README carries banners for SerpApi, SearchApi, Scrap.io, HasData, G Maps Extractor and Coreclaw. That is an unusual amount of competitor surface inside a project's own README, and it is worth reading as a map of the alternatives. Most of them are hosted services, and G Maps Extractor is a Chrome extension. You send a query and receive structured JSON, and the vendor absorbs the browser fleet, the proxy pool and the breakage when Maps changes. SerpApi is described as a Google Maps API and 30+ search engine APIs, which is the API-key model. Scrap.io is described as extracting all Google Maps listings at country scale with no keywords needed, which is the opposite of this project's keyword-driven search flow.
The trade-off is control against operational burden. With gosom/google-maps-scraper you run the Chromium fleet, you supply or accept a proxy, and you own the queue and the storage. In exchange there is no per-request billing and no vendor deciding which fields you may have. With a hosted API you get a stable interface and someone else's uptime, and you pay per call. Neither is strictly better; the deciding question is whether your team wants to operate a browser farm. The README's SaaS Edition documentation under docs/saas.md suggests the maintainer is aware that some users want the hosted shape without leaving the codebase.
Licence, maintenance and upgrade cost
The licence is MIT, per the badge and the LICENSE file at the repository root. MIT is permissive: you can use the code commercially, modify it and redistribute it, provided the copyright notice and permission notice are retained. That is a description of the licence text, not legal advice; if you plan to redistribute a modified binary, have your own counsel read the file.
The maintenance signal is strong on recency. The last push was on 2026-10-21, and the most recent release, v1.18.1, was tagged on 2026-09-20, with v1.18.0 on 2026-09-13 and v1.17.4 on 2026-08-22. That is three releases in about a month, and the repository is not archived. The Makefile hardcodes VERSION := 1.18.1, which means a release requires a source edit, so expect version bumps to appear as commits rather than as a purely tag-driven pipeline.
The upgrade cost is dominated by the browser, not the Go code. go.mod pins playwright-go at v0.6100.0 and the Dockerfile pins the same version as an ARG, so a Playwright bump touches both files. The base images are golang:${GO_VERSION}-trixie and debian:trixie-slim with GO_VERSION defaulting to 1.27.1, so a Go toolchain bump is a single ARG change. Because the scraper reads rendered pages, the practical upgrade risk is not the library version but an upstream change in how Maps renders results; a pinned image will keep working until that changes, and then you will need a code fix rather than a version bump.
Editorial conclusion
Adopt it if you already run Docker and want a self-hosted extraction pipeline you can script, because the README offers CSV/JSON output from the command line, a Web UI and a REST API. Do not adopt it if you need a hosted service with a support contract. Verify two things before committing: that a small scrape returns the fields you actually need, and that your own proxy or network setup is acceptable to the maintainer's stated workflow, since proxy credentials are entered through a masked local terminal prompt rather than passed as plain flags.
Frequently asked questions
How do I install gosom/google-maps-scraper?
The README's easiest path is the AI agent skill, installed with npx skills add gosom/google-maps-scraper, which requires Docker and Node.js on macOS, Linux, or Windows through WSL. Alternatively, build the binary from source with make build or build the Playwright image with make docker.
How do I use gosom/google-maps-scraper?
After installing the skill, you describe the leads you want in plain language and the agent plans the searches, runs a small validation, starts the full local scrape and monitors it. The README also points to a Command Line section for CSV/JSON output, a Web UI section for a browser interface, and a REST API section for calling it from an application.
Is gosom/google-maps-scraper free?
The code is MIT licensed, so there is no licence fee and you can use it commercially if you retain the copyright and permission notices. The README advertises a separate SaaS Edition in docs/saas.md and lists third-party sponsors.
Does Google Maps allow scraping with this tool?
The README's opening sections describe extraction, proxy usage and scale without stating a position on whether scraping Maps is permitted, so check that question yourself.
Is there a tool that can scrape addresses from Google Maps?
The README says gosom/google-maps-scraper extracts the name, address, phone number, website URL, rating, review count, latitude and longitude, reviews and email for each place. Addresses are part of the documented output alongside the other business fields.
What is the best free Google Maps scraper?
The repository does not rank itself against other tools, so it makes no claim about being the best. It does list SerpApi, SearchApi, Scrap.io, HasData, G Maps Extractor and Coreclaw as sponsors, most of which are hosted alternatives with a different operating model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/gosom-google-maps-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/gosom-google-maps-scraper)Was this useful?