GPUStack: A GPU Cluster Manager That Treats Model Serving and Dev Instances as One Problem
Project brief: A GPU cluster manager for high-performance AI model serving (vLLM, SGLang) and on-demand SSH-accessible GPU instances.
At a glance
- What is it?
- GPUStack is an open-source GPU cluster manager for orchestrating inference engines like vLLM and SGLang, and for provisioning SSH-accessible GPU instances on demand. It targets teams that need both production serving and interactive dev workloads on the same heterogeneous GPU fleet.
- Who is it for?
- Adopt GPUStack if you run vLLM or SGLang workloads across on-prem, Kubernetes, or cloud GPUs and want a single control plane for both production serving and SSH-accessible dev instances. Skip it if you need Windows or macOS worker nodes, or if your GPU fleet is exclusively Kubernetes and you prefer native K8s operators.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
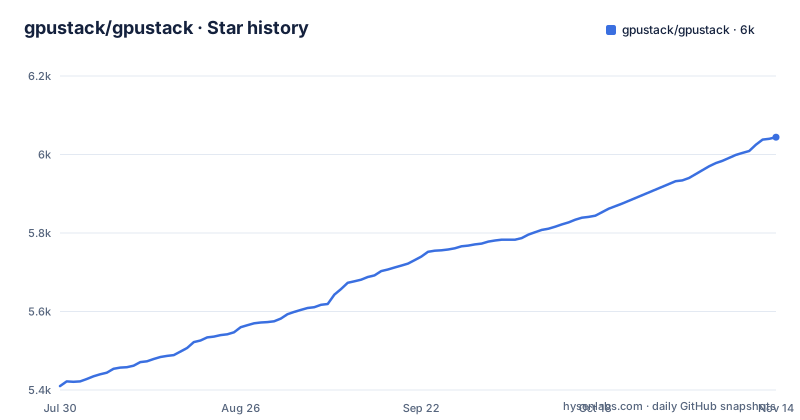
Star history
- gpustack/gpustack6,044 ★ · +634
| Repository | 2026-07-30 | 2026-11-14 |
|---|---|---|
| gpustack/gpustack | 5.4k | 6k |
634 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What GPUStack Actually Solves
GPUStack is a GPU cluster manager that addresses two distinct jobs in one tool. First, it configures and orchestrates inference engines, vLLM, SGLang, TensorRT-LLM, or custom ones, so you can deploy models without hand-writing engine flags. Second, it launches SSH-accessible GPU instances on demand, which suits development, fine-tuning, and interactive workloads. The target audience is development teams, IT organizations, and service providers who want to deliver Model-as-a-Service at scale. The README stresses multi-cluster management across on-premises servers, Kubernetes, and cloud providers, so the tool is not tied to one infrastructure. What is unusual is the pairing: most GPU schedulers handle either batch jobs or serving, not both. GPUStack treats serving and interactive instances as the same resource pool, which is a practical choice for teams that share GPUs between production endpoints and engineers who need a shell.
Architecture: One Server, Many Clusters, Pluggable Engines
The architecture, as described in the README, is a single GPUStack server that manages multiple GPU clusters. The server does not require a GPU and can run on a CPU-only machine. Workers connect to the server, and the scheduler allocates GPUs to maximize utilization. The scheduler also selects the appropriate inference engine for each model. The engine selection is pluggable, which is how GPUStack claims 'Day 0 Model Support': when a new model is released, you can deploy it the same day because the engine layer is not hardcoded. The README mentions that the platform supports industry-standard APIs for LLM, voice, image, and video models. The server also includes authentication, access control, and metering of token usage and API request rates. Administrators get Grafana and Prometheus dashboards for system health and metrics. The key architectural point is that the server is a control plane, and workers are the execution plane. This design keeps the server lightweight and lets you scale workers independently.
Getting It Running: Docker Commands and the Join Flow
The quick start is Docker-centric. You start the server with a single command: `sudo docker run -d --name gpustack --restart unless-stopped -p 80:80 --volume gpustack-data:/var/lib/gpustack gpustack/gpustack`. The initial admin password is written to `/var/lib/gpustack/initial_admin_password` inside the container, and you retrieve it with `sudo docker exec gpustack cat /var/lib/gpustack/initial_admin_password`. Then you log into the UI at `http://your_host_ip` with username `admin`. To add a worker, you navigate to the `Clusters` page, click `Add Cluster`, select `Docker` as the provider, and the UI gives you a join command. The README also gives a mirror option for Quay.io if Docker Hub is slow or blocked. Only Linux is supported for workers, and macOS is not supported. Windows users are told to use WSL2 and avoid Docker Desktop.
Performance Tuning: Pre-Tuned Modes and KV Cache Tricks
GPUStack does not just launch vLLM with defaults. The README claims performance-optimized configurations with modes for low latency or high throughput. It offers a platform-managed shared KV cache that lets compatible deployments and replicas reuse cached prefixes, with L2 storage extending capacity and reuse across nodes. It also includes built-in support for speculative decoding methods: EAGLE3, MTP, and N-grams. The README includes a figure showing throughput improvements over default vLLM configurations. The docs link to an 'Inference Performance Lab' for benchmarking methods and results, which is where you would find the concrete data. This is a meaningful feature because vLLM often requires manual tuning of KV cache and speculative decoding parameters. If GPUStack automates that selection, it reduces the expertise needed to get good serving performance. However, the README does not specify how the scheduler decides between low latency and high throughput modes, nor does it say whether the tuning is per-model or per-cluster. That is a gap you would need to verify in the docs.
The GPU Instance Feature: SSH Access on Demand
The second half of GPUStack is the ability to launch SSH-accessible GPU instances on demand. This is for development, fine-tuning, and interactive workloads. The architecture implies that the same scheduler that places model deployments also places instances, so you can allocate a GPU to an engineer who needs a shell. This is a different resource model than serving, where a model runs as a long-lived service. An instance is ephemeral and interactive. The feature list does not say how instance images are defined or how SSH keys are managed. For a team that needs interactive GPU access, this is a potentially valuable feature, but you would have to read the docs or try the UI to understand the trade-offs, such as whether instances support persistent storage.
Accelerator Support: Broad but with Caveats
GPUStack claims support for a wide range of accelerators: NVIDIA, AMD, Ascend NPU, Hygon DCU, MThreads GPU, Iluvatar GPU, MetaX GPU, Cambricon MLU, and T-Head PPU. That is an impressive list, but the quick start only covers NVIDIA. The README says to check the guidelines in the UI when adding a worker for other GPU types, or refer to the installation requirements. This means the out-of-the-box experience is NVIDIA-centric, and non-NVIDIA setup may require extra steps. The worker node requirements are specific: NVIDIA driver, Docker, and NVIDIA Container Toolkit. For other accelerators, the documentation is the source of truth. The README also notes that the server can run on a CPU-only machine, which is practical for separating control from compute. The accelerator list suggests GPUStack is designed for heterogeneous fleets, but the reality is that you need to verify each accelerator's support level in the docs. The README does not state whether all accelerators have equal performance optimization, which is unlikely given the maturity of vLLM support for NVIDIA versus others.
Operational Features: Failure Recovery, Monitoring, and Metering
GPUStack includes what the README calls enterprise-grade operations: automated failure recovery, load balancing, monitoring, authentication, and access control. It also has metering of token usage and API request rates. The Grafana and Prometheus dashboards give administrators visibility into GPU performance and utilization. The README does not explain how failure recovery works, for example whether it restarts a crashed model deployment on the same worker or migrates it to another. Load balancing is also vague: it could be at the HTTP API level or at the GPU allocation level. The metering is concrete, as it tracks token usage and API request rates, which is useful for chargeback in a service provider context. The authentication and access control are built-in, which means you do not need a separate identity provider. For a team that needs to offer model access to multiple users, the built-in auth and metering are a strong point. But the lack of detail on recovery and load balancing means you should test those features in your environment before relying on them.
Limitations and When It Is the Wrong Tool
The most obvious limitation is platform support. Only Linux is supported for worker nodes. macOS is not supported, and Windows requires WSL2 with a warning to avoid Docker Desktop. If your team uses Windows workstations for GPU development, the README suggests WSL2 and avoiding Docker Desktop. Another limitation is the Docker-centric deployment. The quick start requires Docker and the NVIDIA Container Toolkit. If your cluster is Kubernetes-only and you prefer a native K8s operator, GPUStack's Docker-based workers may feel redundant. The README does mention Kubernetes as a supported environment, but the join command shown is for Docker. The performance claims, such as throughput improvements over default vLLM, are not backed by numbers in the README. You would need to visit the Inference Performance Lab to see the methodology. Also, the SSH instance feature is underdocumented in the README, so you cannot assess its security or storage model. GPUStack is the wrong tool if you need Windows or macOS workers, or if you want a pure Kubernetes-native solution without an additional control plane. It is also not ideal for HPC batch workloads, as the README focuses on serving and interactive instances, not job scheduling.
Alternatives: Kubernetes Operators and Standalone Schedulers
The main alternative to GPUStack is a Kubernetes-native approach. Tools like the vLLM Kubernetes operator or KServe (for model serving) and KubeFlow (for training) handle GPU scheduling and inference workloads directly on Kubernetes. The difference in approach is that these tools rely on Kubernetes for cluster management, node discovery, and scheduling. GPUStack, by contrast, has its own server and worker model, which means it can manage clusters that are not Kubernetes, such as a set of bare-metal servers with Docker. If you are already invested in Kubernetes, a native operator may be simpler because it uses the same APIs and RBAC. If you are not, GPUStack gives you a simpler starting point, a single Docker container for the server and a join command for workers. Another alternative is a standalone scheduler like Slurm with a serving shim, but that is more for HPC. The README does not compare itself to these, but the architecture makes the trade-off clear: GPUStack is a self-contained control plane, while Kubernetes operators are extensions of an existing control plane.
Maintenance and License Considerations
GPUStack is licensed under Apache-2.0, which is permissive and allows commercial use, modification, and distribution without copyleft obligations. This is a low-risk license for enterprises. The project is actively maintained, with recent releases including v2.3.0 on 2026-10-23 and v2.3.0rc4 on 2026-10-21. The release cadence suggests regular updates. Maintenance cost likely involves upgrading the server and workers. Since workers are Docker containers, upgrading means pulling a new image and recreating the containers. The README does not mention a migration tool or compatibility guarantees between versions, so you should test upgrades in a staging environment. The server stores data in a Docker volume (`gpustack-data`), which you must back up. Overall, Docker-based deployment keeps maintenance simple.
Editorial conclusion
Adopt GPUStack if you run vLLM or SGLang workloads across on-prem, Kubernetes, or cloud GPUs and want a single control plane for both production serving and SSH-accessible dev instances. Skip it if you need Windows or macOS worker nodes, or if your GPU fleet is exclusively Kubernetes and you prefer native K8s operators. Before adopting, verify that your accelerator is on the supported list (NVIDIA, AMD, Ascend, Hygon, MThreads, Iluvatar, MetaX, Cambricon, T-Head), confirm the Docker and NVIDIA Container Toolkit prerequisites on every worker, and follow the UI guidelines when setting up a cluster.
Frequently asked questions
What is GPUStack?
GPUStack is an open-source GPU cluster manager for AI model serving and GPU instance provisioning. It configures and orchestrates inference engines such as vLLM, SGLang and TensorRT-LLM, and it launches SSH-accessible GPU instances on demand across on-premises servers, Kubernetes clusters and cloud providers.
How does GPUStack relate to vLLM?
vLLM is one of the inference engines GPUStack configures and orchestrates, next to SGLang, TensorRT-LLM and custom engines you add yourself. The performance section compares throughput against default vLLM configurations, and GPUStack adds cluster management, engine configuration, monitoring and token metering around it.
How does GPUStack compare with Ollama?
The README overview does not mention Ollama. The engines named for GPUStack are vLLM, SGLang, TensorRT-LLM and custom engines, and its scope is cluster management, model serving APIs with token metering, and on-demand SSH-accessible GPU instances.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/gpustack-gpustack)Star history chart for your README
[](https://hysenlabs.com/projects/gpustack-gpustack)Was this useful?