ChatterBot: a retrieval chatbot engine that learns from what you feed it
ChatterBot is a machine learning, conversational dialog engine for creating chat bots
At a glance
- What is it?
- ChatterBot is a Python library that stores statements and their responses, then picks the closest matching reply using a similarity search. It is a good fit for scripted or corpus-driven bots, and a poor fit for anything that needs a language model.
- Who is it for?
- Adopt ChatterBot when you want a self-contained Python bot whose replies come from data you control, such as a corpus, a help-desk FAQ export, or a fixed set of conversational turns. Do not adopt it when you need generative answers, multi-turn reasoning, or quality that improves without you supplying more statement-response pairs; the engine only knows what it has been trained on.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
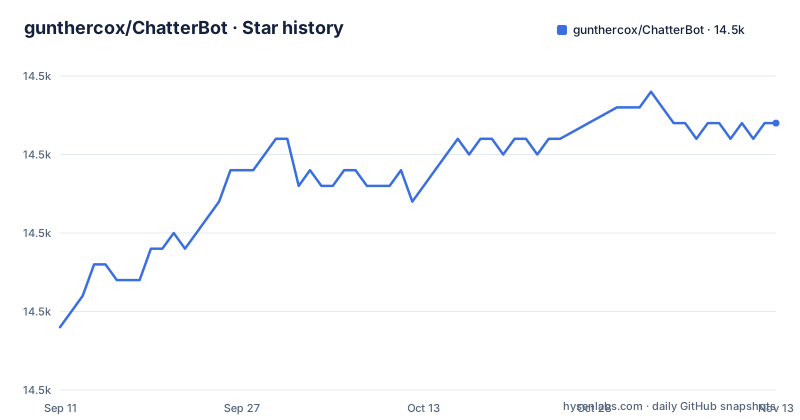
- gunthercox/ChatterBot14,522 ★ · +13
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| gunthercox/ChatterBot | 14.5k | 14.5k |
13 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ChatterBot actually solves, and for whom
ChatterBot is for people who need a bot that answers from a known set of exchanges rather than from a model. The README describes the engine as generating responses based on collections of known conversations, and states that the language independent design allows it to be trained to speak any language. That framing matters. This is not a system that reasons about your question. It is a system that looks up the closest question it has already seen and returns the answer that was most often attached to it.
The audience follows from that. If you are building a FAQ bot for a product with a fixed set of questions, or a demo bot that needs to run entirely inside your own process without calling an external API, ChatterBot fits. If you want a bot that handles paraphrases, follow-up questions, or topics you never trained on, it does not. The README's own example conversation shows the boundary clearly: the bot answers a greeting, then shifts to asking about hats. That is the behaviour of a retrieval system with no notion of conversational context beyond the last statement.
The training loop: statements in, similarity search out
The mechanism is described plainly in the README. An untrained instance starts with no knowledge. Each time a user enters a statement, the library saves the text of that statement and the text of the statement it was responding to. Over time, the set of statements it can respond to grows.
Selection works by searching for the closest matching known statement, then returning the most likely response based on how frequently that response was issued. So there are two distinct pieces: a similarity comparison between the incoming text and stored statements, and a frequency count over the responses attached to the winning statement. There is no generation step anywhere in this description. Everything the bot says was written by someone, either in the corpus or in a prior conversation.
This design has a direct consequence that the README does not spell out. Because responses are ranked by frequency, a statement that has been answered the same way many times will keep getting that answer, and a single unusual correction will be outvoted. Correcting a bot's behaviour means changing the stored data, not adjusting a parameter.
Getting a bot running: install, train, respond
Installation is a single pip command:
pip install chatterbot
The basic usage example in the README constructs a chatbot by name, creates a corpus trainer, trains on the English corpus, and calls get_response. The import paths are chatterbot for ChatBot and chatterbot.trainers for ChatterBotCorpusTrainer. The corpus name passed to train is a dotted path such as chatterbot.corpus.english, and the README shows that you can narrow it to a subset with chatterbot.corpus.english.greetings or chatterbot.corpus.english.conversations.
Multiple training calls accumulate, so a bot trained on greetings and then on conversations has both sets available. The README does not show any configuration for storage in the example, and it does not show how to persist a trained bot between process restarts. The README points to docs.chatterbot.us for the full documentation. Treat the storage configuration as something you must look up before deploying, not something the README hands you.
Where the retrieval approach breaks down
The failure mode is built into the design. A retrieval engine can only return responses that exist in its store, and it can only match against statements it has seen. Ask a question that is semantically close to a trained statement but lexically distant, and the similarity search has nothing good to latch onto. The README's own sample output illustrates the ceiling: the bot's third line is a non sequitur, because the engine treats each incoming statement independently and has no model of what a sensible next turn would be.
The frequency ranking compounds this. If during training a statement appeared with several different responses, the most common one wins every time. There is no way to express that a particular response is better in a particular situation, because situation is not part of the lookup key.
There is also a data problem the README is honest about. Training data for over a dozen languages ships in a separate package, chatterbot-corpus, and the README invites pull requests for additional languages. If your target language is not among the dozen or so covered, you are writing the corpus yourself, and the quality of your bot is capped by the quality of that corpus. For a niche language that is a substantial project on its own.
How this differs from calling a hosted language model
The obvious alternative for a Python chatbot in 2026 is to send the conversation to a hosted language model API and return its text. The difference is not a matter of degree. A hosted model generates a response token by token from a trained parameter set, so it can answer questions it has never literally seen and can produce text that was never written by anyone. The engine the README describes does neither. It retrieves, although the repository also ships examples/openai_example.py and examples/ollama_example.py.
That cuts both ways. Retrieval gives you auditability: every response the bot produces can be traced to a specific statement in your corpus or your conversation history, which is useful when the bot is answering customers and you need to know why it said something. Generation does not give you that. On the other side, generation handles paraphrase, ambiguity and unseen questions without you writing training data for each one, and ChatterBot does not.
The practical split: if the set of questions your bot will face is closed and known, ChatterBot's retrieval is cheaper to reason about and runs without a network dependency. If the set is open, retrieval will fail in ways that are hard to patch, because each failure needs a new training example.
Maintenance, release cadence and licence terms
The repository is active, not archived, and the release history shows a steady cadence: 1.2.15 in August 2026, 1.2.14 in June 2026, 1.2.13 in March 2026. That is roughly quarterly, which is a reasonable pace for a library of this size but not a fast one. pyproject.toml requires Python >=3.10,<3.15, so the supported interpreter is recent and you should expect to keep your Python version current rather than pinning to something older.
Upgrade cost is dominated by the storage layer rather than the API. The public surface shown in the README is small: a constructor, a trainer, a train call, and get_response. That surface is unlikely to churn. What can bite you is a schema change in whatever storage adapter you use, since your training data lives in that store and not in your code. Before upgrading, check the release notes for the version you are moving to.
The licence is BSD 3-clause. That is a permissive licence, which generally means you can use the library in closed-source products provided you retain the copyright notice and licence text, and it includes a clause preventing use of the project's name to endorse derived products. This is a summary, not legal advice; read the licence text at opensource.org/licenses/BSD-3-Clause before relying on it.
What to verify before you build on it
Check your language first. Open the chatterbot-corpus package and confirm that a corpus exists for the language you need. If it does not, budget for writing one, because the README treats corpus contributions as community work rather than something the maintainers supply on request.
Check storage second. The README's quickstart does not configure a database, and training writes every statement and response pair into one. Confirm which backend the current version defaults to and that it can handle your training volume, since a bot trained on a large conversation log will be doing a similarity search over a correspondingly large statement table on every get_response call.
Check the boundary third. Write down the questions your bot must answer, then test whether a corpus-trained instance answers them. If it does not, the fix is more training data, and you should decide now whether you are willing to keep supplying it. A ChatterBot deployment is a data maintenance commitment, not a set-and-forget component.
Editorial conclusion
Adopt ChatterBot when you want a self-contained Python bot whose replies come from data you control, such as a corpus, a help-desk FAQ export, or a fixed set of conversational turns. Do not adopt it when you need generative answers, multi-turn reasoning, or quality that improves without you supplying more statement-response pairs; the engine only knows what it has been trained on. Before committing, verify two things: that the corpus for your target language actually exists in the chatterbot-corpus package, and that your storage backend is reachable and writable before training.
Frequently asked questions
What is a ChatterBot?
A machine-learning based conversational dialog engine built in Python, which generates responses from collections of known conversations. Its design is language independent, so it can be trained to speak any language that has training data available.
how to install chatterbot
From PyPI with pip install chatterbot. The packaging metadata requires Python >=3.10,<3.15, so anything outside that range is refused at install time.
how to use chatterbot in python
Instantiate ChatBot with a name, create a ChatterBotCorpusTrainer for it, call trainer.train with a corpus such as chatterbot.corpus.english, then ask chatbot.get_response for a statement.
chatterbot vs rasa
The ChatterBot README does not compare the two projects. What the repository shows is ChatterBot's own integration surface: examples/openai_example.py, examples/ollama_example.py, examples/django_example/ and the chatterbot.ext.django_chatterbot package that ships migrations.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/gunthercox-chatterbot)Star history chart for your README
[](https://hysenlabs.com/projects/gunthercox-chatterbot)Was this useful?