HiRAG: Hierarchical Graph Retrieval Built on the LightRAG Pipeline
[EMNLP'25 findings] An easy-to-use Graph RAG system using hierarchical knowledge.
At a glance
- What is it?
- HiRAG layers community summaries, bridge edges and naive vector retrieval over a LightRAG-style graph index. The paper reports head-to-head LLM-judge wins against NaiveRAG, GraphRAG and LightRAG, but the repository ships no benchmark harness and the README's quick start is not runnable as printed.
- Who is it for?
- Adopt HiRAG if you already run a LightRAG-style graph index over UltraDomain-like long documents and want to test whether community summaries plus bridge entities improve multi-hop answers. Do not adopt it if you need a packaged service with a stable API or a reproducible benchmark you can run without writing the harness yourself.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 152 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
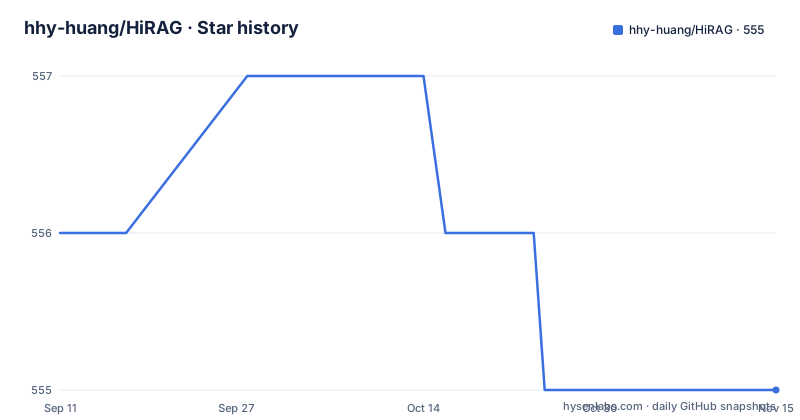
- hhy-huang/HiRAG555 ★ · -1
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| hhy-huang/HiRAG | 556 | 555 |
-1 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The retrieval gap HiRAG claims to fill
Standard RAG retrieves chunks by embedding similarity and hands them to a generator. That works when the answer sits inside one or two passages. It fails on questions that need facts scattered across a long document, where no single chunk is close enough to the query to surface, and where the connecting evidence lives in a different section entirely. Graph RAG addresses this by extracting entities and relations, clustering them into communities, and summarising each community so a query can be answered from summaries rather than raw text. HiRAG's stated contribution is a hierarchy over that structure. The README describes the project as an easy-to-use Graph RAG system using hierarchical knowledge, and the paper is titled Retrieval-Augmented Generation with Hierarchical Knowledge. The intended user is someone building question answering over long, domain-specific corpora: the evaluation datasets are Mix, CS, Legal and Agriculture, drawn from the UltraDomain collection on Hugging Face. If your corpus is a set of short, self-contained documents, the hierarchy adds indexing cost without adding retrievable signal.
How the hierarchy and the retrieval modes fit together
The README does not spell out the indexing algorithm, so the mechanism has to be read from the evaluation commands and the constructor arguments. Indexing is triggered by graph_func.insert() on a text string, and the constructor takes enable_hierachical_mode (spelled that way in the source) plus enable_naive_rag. That pairing suggests the hierarchy is built during insertion, while a flat vector index is optionally maintained alongside it. Retrieval is selected at query time through QueryParam(mode=...). The evaluation scripts expose five modes: hi, hi_nobridge, hi_local, hi_global and hi_bridge. The names map onto the hierarchy directly. Local retrieval stays within fine-grained entities and their immediate neighbourhood. Global retrieval works from the coarser community summaries. Bridge retrieval targets the entities that connect separate communities, which is the layer that matters for multi-hop questions. hi combines them, hi_nobridge drops the bridge layer, and the single-layer modes let you isolate which part of the hierarchy is doing the work. That ablation surface is the most useful thing in the repository: it lets you test whether the bridge layer earns its indexing cost on your own data rather than taking the paper's aggregate numbers on faith.
Installing and running a first query
Installation is a single editable install from the cloned repository: cd HiRAG followed by pip install -e . The README gives no Python version floor and no list of the dependencies that pip will resolve, so treat the install as unverified until you run it. The quick start constructs a HiRAG object with working_dir, enable_llm_cache, enable_hierachical_mode, embedding_batch_num, embedding_func_max_async and enable_naive_rag. The comment on embedding_func_max_async reads according to your machine, which is the only sizing guidance offered. Indexing is then a with-block that opens a text file and passes its contents to graph_func.insert(), and querying is graph_func.query() with a QueryParam. Two gaps are visible in that snippet. QueryParam is used but never imported, and config.yaml, which the README says holds API keys and LLM configuration, is not shown in the quick start at all. The working examples for DeepSeek, ChatGLM and OpenAI live in hi_Search_deepseek.py, hi_Search_glm.py and hi_Search_openai.py at the repository root. Start from one of those files rather than from the README block.
Running the UltraDomain evaluation end to end
The evaluation path is documented more completely than the quick start. From HiRAG/eval, the first step extracts context from the original QA datasets: python extract_context.py -i ./datasets/mix -o ./datasets/mix. The second inserts that context into the graph database with insert_context_deepseek.py, and the README notes you can substitute insert_context_openai.py or insert_context_glm.py depending on which model you are paying for. The third runs answers: python test_deepseek.py -d mix -m hi, with -m taking any of hi, naive, hi_nobridge, hi_local, hi_global or hi_bridge, and the dataset flag taking any UltraDomain split. Scoring is a two-phase batch job. python batch_eval.py -m request -api openai submits the judgments, and python batch_eval.py -m result -api openai collects them. The comparison tables are produced by editing the output_file key to point at a filename such as ./datasets/{DATASET}/{DATASET}_eval_hi_naive.jsonl before rerunning the result phase. That filename convention is the actual switch between the NaiveRAG, GraphRAG and LightRAG comparisons, and it is easy to miss.
What the reported numbers do and do not establish
The result tables are LLM-judge win rates, not accuracy scores. Against NaiveRAG the reported overall split is 87.6 to 12.4 on Mix, and against GraphRAG it narrows to 64.1 to 35.9 on the same dataset. Two things follow. First, the margin over NaiveRAG is large and consistent across all four datasets, which is expected: any graph-structured retrieval should beat flat chunk retrieval on multi-hop questions. The informative comparison is against GraphRAG, where the overall split falls to 54.5 to 45.5 on Legal and 54.0 to 46.0 on Agriculture. On those two datasets the hierarchy is close to a coin flip against a system it is meant to improve on. Second, the judge is an LLM accessed through the openai or deepseek API, so the scores inherit whatever biases that judge has toward longer, more structured answers. The repository does not include a human evaluation or an exact-match baseline. Treat the tables as a reason to run the hi versus hi_nobridge ablation on your own corpus, not as a settled verdict.
The quick start does not run as printed
This is the sharpest limitation. The README's quick start block references QueryParam without importing it, so copying it into a file produces a NameError before any indexing happens. The snippet also omits the config.yaml setup that the surrounding prose says is required for API keys and LLM configuration, and it never states which providers are supported by default. The working examples at the repository root fill both gaps, but a reader who follows the quick start literally will not get a query out. There is a second, quieter issue: the evaluation harness is a set of standalone scripts rather than a package. extract_context.py, insert_context_*.py, test_*.py and batch_eval.py are invoked by path from HiRAG/eval, and the provider is chosen by picking a differently named file rather than by setting a flag. Adding a new provider means copying and editing a script. There are no releases in the repository metadata, so there is no versioned artifact to pin against and no changelog to consult when an upstream API changes shape. The MIT licence and the absence of an archive flag mean the code is open and nominally maintained, but the last push date is the only maintenance signal available.
HiRAG against LightRAG and GraphRAG
The README positions HiRAG directly against LightRAG by naming the comparison in the evaluation config, and the API shape makes the lineage plain: the constructor arguments, the working_dir convention and the insert-then-query pattern all follow LightRAG. The practical difference is the retrieval layer. LightRAG exposes local and global modes over its graph and vector stores. HiRAG adds the bridge layer and a hierarchical mode that combines all three, and it exposes each layer as a separate mode so you can measure them independently. GraphRAG, by contrast, is built around community summarisation as the primary retrieval unit and is heavier to index. HiRAG's reported edge over GraphRAG is widest on Mix and narrowest on Legal and Agriculture, which suggests the hierarchy helps most when the corpus mixes domains. If you already run LightRAG, the migration cost is low because the interfaces line up; the real question is whether the bridge layer changes your answers, and the hi versus hi_nobridge pair is the cheapest way to find out. The README also points to DeepRefine, a separate repository, for refining a knowledge base at test time instead of re-indexing, which is the right place to look if re-indexing cost is your binding constraint.
Editorial conclusion
Adopt HiRAG if you already run a LightRAG-style graph index over UltraDomain-like long documents and want to test whether community summaries plus bridge entities improve multi-hop answers. Do not adopt it if you need a packaged service with a stable API or a reproducible benchmark you can run without writing the harness yourself. Before committing, verify three things: that the QueryParam import missing from the README exists in your installed version, that config.yaml in the cloned repo root actually holds the LLM and embedding keys the quick start implies, and that the corpus you plan to index is closer in length and structure to UltraDomain than to short support tickets.
Frequently asked questions
What is HiRAG?
The reference implementation for HiRAG: Retrieval-Augmented Generation with Hierarchical Knowledge, a paper accepted to EMNLP 2025 Findings. It indexes text into a knowledge graph and retrieves over both entity descriptions and relations.
How do I install HiRAG?
Clone the repository, change into the HiRAG directory and run `pip install -e .`. The distribution is named HiRAG, declares Python 3.9 or newer, and installs exact pinned versions from requirements.txt, including a Neo4j driver and a vector store.
Which retrieval modes does HiRAG support?
The evaluation scripts expose five: hi for the full approach, naive for the baseline, hi_nobridge without bridging, hi_local using only local knowledge and hi_global using only global knowledge. Queries pass the mode through a QueryParam argument.
How were the HiRAG comparison tables produced?
By running batch_eval.py twice, once to request evaluations from an API and once to collect results, with the api argument set to openai or deepseek. The tables report judge scores in pairwise comparisons against naive RAG, GraphRAG and LightRAG across four datasets.
Where do I configure API keys for HiRAG?
In config.yaml at the repository root, which the documentation names as the place for API keys and LLM configuration. Ready-made search scripts for DeepSeek, ChatGLM, OpenAI, Cohere and Ollama sit alongside it at the root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hhy-huang-hirag)Star history chart for your README
[](https://hysenlabs.com/projects/hhy-huang-hirag)Was this useful?