Colossal-AI: A Training Framework That Now Points to a Paid Cloud
Making large AI models cheaper, faster and more accessible. Build your AI agents, chatbots, and RAG applications with HPC-AI Model APIs!
At a glance
- What is it?
- Colossal-AI is an open-source distributed training and inference framework for large models. The v0.5.0 release and the README's heavy promotion of HPC-AI Cloud and Model APIs raise a key question: is the project still primarily a library, or a gateway to a commercial platform?
- Who is it for?
- Adopt Colossal-AI if you need a distributed training and inference framework that supports parallelism strategies like zero, tensor parallel, and pipeline parallel, and you are comfortable with a project whose README now pushes a commercial cloud service. Do not adopt it if you want a purely self-contained library with no commercial tie-in, or if you need features not documented in the README.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
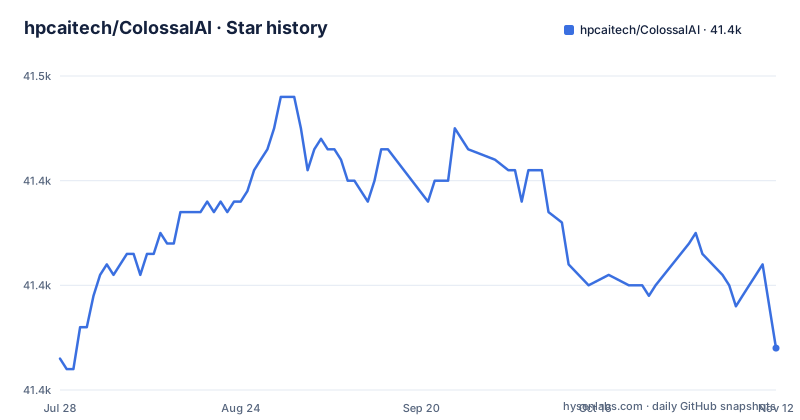
Star history
- hpcaitech/ColossalAI41,424 ★ · +1
| Repository | 2026-07-28 | 2026-11-12 |
|---|---|---|
| hpcaitech/ColossalAI | 41.4k | 41.4k |
1 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Colossal-AI Actually Solves
Colossal-AI addresses the cost and complexity of training and running large AI models. The project's stated goal is making large AI models cheaper, faster, and more accessible. It targets engineers and researchers who need to train models like Llama-style architectures at scale, or who want to fine-tune massive models such as DeepSeek 671B. The README shows benchmarks for 7B and 70B models on 8 and 16 GPUs, with parallelism configurations like zero2 and zero1(dp2)+tp2+pp4. That tells you the framework's core value: it gives you a set of distributed training strategies without forcing you to hand-roll the plumbing. The project also includes Colossal-Inference, an inference component that the blog claims doubles inference speed. So the problem it solves is the engineering overhead of scaling model training and inference across multiple GPUs.
How It Works: Parallelism Strategies and the Shift to Cloud
The repository's mechanism is visible in the benchmark table: it supports data parallel (dp), tensor parallel (tp), and pipeline parallel (pp), plus zero stages. The README shows configurations like zero2(dp8) and zero1(dp2)+tp2+pp4. That means you can mix these strategies to fit a model across GPUs. The framework presumably handles the communication and memory management behind these strategies, but the README does not detail the internal data flow. A more notable shift is that the README now opens with a plug for HPC-AI Cloud, offering B200 GPUs from $2.47/hr and H200 clusters from $1.99/hr. It also promotes HPC-AI Model APIs for building agents, chatbots, and RAG applications, claiming up to 50% cheaper than OpenRouter. This is not a technical mechanism; it is a business model. The project is still Apache-2.0 licensed, but the README's top sections are now commercial advertisements.
Getting It Running: Commands and Config from the README
The opening sections of the README contain no install command or quickstart code snippet. What it does show is a benchmark configuration that implies how you would set up training. For example, the 7B model on 8 H200s uses zero2 with a batch size per DP of 36 and sequence length 4096. The 70B model on 16 GPUs uses zero1(dp2)+tp2+pp4 with batch size 128. These are not literal config keys, but they tell you the framework expects you to specify parallel strategies and batch sizes. The README links to a documentation site and an examples folder. To actually run Colossal-AI, the repository's setup.py builds the package, and compiled extensions are enabled with the BUILD_EXT=1 environment variable. You would also need to refer to the examples directory, which is linked but not described. So the practical setup path is: read the docs, check the examples, and probably use the cloud playground if you want a preconfigured environment.
Where It Falls Short: Documentation Gaps and Commercial Pressure
The README's opening sections are cloud pricing, model API promotions, and a benchmark table, with technical documentation left to the linked documentation site and examples folder. For an engineer evaluating adoption, that means the evaluation work happens off the README. Another failure mode is that the project's direction seems tied to HPC-AI Cloud. The news items link to the company's blog and include its Series A funding, GPU vouchers, Open-Sora and Colossal-Inference. If you want a purely self-hosted library, the commercial push may be a turnoff. Also, the benchmark numbers are presented without methodology details, so you cannot verify them independently.
The Alternative: What Else Is Out There
The obvious alternative is DeepSpeed, a distributed training framework from Microsoft that also supports zero optimization and mixed precision. The difference in approach is that DeepSpeed is a library you integrate into your own training loop, with a focus on memory efficiency through zero stages and offloading. Colossal-AI, at least in this README, is positioning itself as a broader platform with cloud and API services. DeepSpeed does not have a commercial cloud tied to it. Another alternative is PyTorch's native DistributedDataParallel and FullyShardedDataParallel, which are built into PyTorch and require no extra dependency. The difference is that Colossal-AI offers higher-level parallelism strategies like tensor and pipeline parallel out of the box, whereas PyTorch's native tools require more manual setup. If you want a lightweight solution and you are comfortable with PyTorch's built-ins, you might not need Colossal-AI at all.
Maintenance, Upgrades, and License Implications
The repository is not archived, and the last push was on 2026-11-01. The newest release is v0.5.0 from June 4, 2025, with v0.4.9 in March 2025 and v0.4.8 in February 2025 before it, so commits continue without a recent tagged release. The license is Apache-2.0, which is permissive. You can use, modify, and distribute the code, including in commercial products, as long as you preserve the license notice. That is a low-license-risk option compared to copyleft licenses. However, the README's heavy promotion of HPC-AI Cloud suggests that the core team's revenue comes from the cloud, not from the open-source library. That could mean the library gets less attention over time, or it could mean the library is a loss leader. You should verify the project's roadmap and recent commit history beyond the README before committing to it.
The Bottom Line: Who Should Use It and What to Check First
Colossal-AI is for teams that need to train or fine-tune large models across multiple GPUs and want a framework that handles parallelism without building it from scratch. The benchmark table shows it can achieve high TFLOPS per GPU, but those numbers are unverified. If you are an individual developer or a small team without access to multi-GPU clusters, the cloud pricing might be attractive, but you should compare it with other GPU rental services. Before adopting, check the documentation for a quickstart guide and look at the examples folder to see if your model architecture is supported. Also, verify whether the parallelism strategies you need are stable in v0.5.0. The README does not tell you that. If you are allergic to commercial tie-ins, consider DeepSpeed or PyTorch native. But if you like the idea of a unified framework with cloud integration and you are willing to dig into the docs, Colossal-AI is worth a trial run.
Editorial conclusion
Adopt Colossal-AI if you need a distributed training and inference framework that supports parallelism strategies like zero, tensor parallel, and pipeline parallel, and you are comfortable with a project whose README now pushes a commercial cloud service. Do not adopt it if you want a purely self-contained library with no commercial tie-in, or if you need features not documented in the README. Before adopting, verify the exact installation steps and the current state of the parallelism APIs, since the README's focus has shifted to cloud promotion and the newest tagged release, v0.5.0, dates from June 2025.
Frequently asked questions
What is Colossal-AI?
Colossal-AI is a Python project described as making large AI models cheaper, faster, and more accessible, distributed under the Apache-2.0 license. Its own benchmark table reports throughput, TFLOPS per GPU, and peak memory for 7B and 70B models across parallel strategies including zero2(dp8), zero2, and zero1(dp2)+tp2+pp4 on H200 and B200 hardware.
How does Colossal-AI compare with DeepSpeed?
The README's benchmark table does not name DeepSpeed or any other framework as a comparison point. Its benchmark table varies GPU model, parallel strategy, and batch size together and contains no baseline row from a different training system, so a framework comparison cannot be drawn from it.
Does Colossal-AI install on Windows?
No. setup.py raises a RuntimeError on win32 with the message that Windows is not supported yet and suggests trying again within the Windows Subsystem for Linux. The check runs while the package is being built, so a Windows install attempt stops with that error rather than completing partially.
How do you build the compiled extensions in Colossal-AI?
The build reads the BUILD_EXT environment variable and enables extensions only when the value is 1, because the check compares an integer conversion of it against 1 with a default of 0. That path also imports torch and BuildExtension from torch.utils.cpp_extension, and a failed import sets TORCH_AVAILABLE to False rather than failing the whole script.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hpcaitech-colossalai)Star history chart for your README
[](https://hysenlabs.com/projects/hpcaitech-colossalai)Was this useful?