MLflow 3.17: A Platform That Tries to Cover Every Stage of AI Engineering
The open source AI engineering platform for agents, LLMs, and ML models. MLflow enables teams of all sizes to debug, evaluate, monitor, and optimize production-quality AI applications while controlling costs and managing access to models and data.
At a glance
- What is it?
- MLflow is an open source platform for tracking, evaluating, and deploying ML models and LLM agents. This review looks at what the current release actually offers, how it works, and where it may not fit.
- Who is it for?
- MLflow 3.17 is for teams that want a single, self-hosted platform to trace, evaluate, and deploy both traditional ML models and LLM agents. Small teams can start with a single server command and the OpenAI autologging hook.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
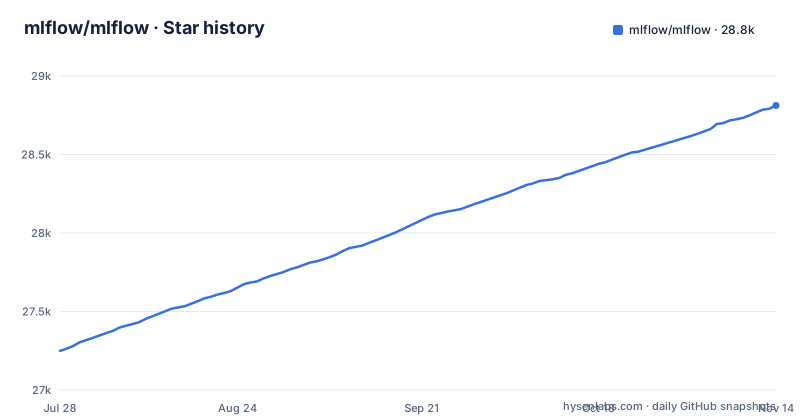
Star history
- mlflow/mlflow28,812 ★ · +1,563
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| mlflow/mlflow | 27.2k | 28.8k |
1,563 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Fragmented Tooling for AI Applications
MLflow addresses a specific pain: teams building AI applications often juggle separate tools for experiment tracking, model registry, prompt versioning, and observability. The README positions MLflow as a single platform for agents, LLMs, and ML models. It claims to cover debugging, evaluation, monitoring, and optimization, plus cost control and access management. The target user is a team that wants to move from ad-hoc scripts to a structured lifecycle without assembling multiple integrations. For ML models, it offers experiment tracking, model evaluation, a registry, and deployment targets like Docker, Kubernetes, Azure ML, and SageMaker. For LLM applications, it adds tracing, evaluation, prompt management, and an AI Gateway. The core promise is that one platform can handle both traditional ML and generative AI workloads, which is rare. Most alternatives focus on one side or the other. That breadth is the main selling point, but it also creates complexity that may not suit every team.
How MLflow Works: Tracing, Evaluation, and the Gateway
The architecture visible in the README shows three distinct layers. First, observability is built on OpenTelemetry, which means traces can be captured from any LLM provider or agent framework that emits OpenTelemetry data. The quickstart shows a simple flow: start the MLflow server, enable autologging for OpenAI, then run your normal code. The server captures traces and metrics, viewable in the UI at localhost:5000. Second, evaluation is a separate module with 50+ built-in metrics and LLM judges, plus the ability to define custom metrics. This is not just a single score; the README mentions tracking quality metrics over time and catching regressions before production. Third, the AI Gateway provides a unified API for all LLM providers, with routing, rate limits, fallbacks, credential management, guardrails, and traffic splitting for A/B testing. The gateway uses an OpenAI-compatible interface, so existing clients can switch without major changes. The data flow is: your application calls the gateway or sends traces via OpenTelemetry, the server stores them, and the UI displays them. The prompt registry adds versioning and lineage tracking for prompts, which ties into evaluation and deployment.
Getting Started: Commands and Configuration
The README gives a concrete three-step setup. First, start the server with `uvx mlflow server`. This assumes you have `uvx` installed, which is a Python package runner. Second, enable logging in your application code: `mlflow.set_tracking_uri("http://localhost:5000")` and `mlflow.openai.autolog()`. Third, run your OpenAI client code as usual. That is the minimal path. For a faster start, the README offers a setup wizard, `curl -LsSf https://mlflow.org/wizard/setup.sh | sh`, run from your project's Git repository with Claude Code, Codex, or OpenCode installed; it guides you through connecting to an MLflow server or Databricks workspace, then launches your coding agent to add tracing to your app. The server runs locally by default, but for production you would need to configure a backend database and storage. The AI Gateway has its own quickstart link, but the README does not show its configuration keys. You would need to consult the docs for gateway-specific setup like provider credentials and routing rules. The tracking URI is the main config key shown, and autologging is the main hook.
Limitations and Failure Modes
The README is heavy on feature lists and light on constraints. If you have complex routing needs, the built-in traffic splitting for A/B testing may not cover all scenarios, such as geographic routing or cost-based optimization across many providers. Another limitation is that the evaluation module, despite 50+ built-in metrics, may not have the specific judge you need. The README says you can define your own, but that requires writing code and understanding the evaluation framework. For teams that only need simple logging, MLflow might be overkill. Also, the README mentions support for Python, TypeScript/JavaScript, Java, and any other language, but the autologging example is only for Python. The biggest failure mode is likely scope creep: a team adopts MLflow for tracing, then discovers the gateway needs separate configuration, and the model registry has its own workflow. The platform tries to do everything, and each feature has its own learning curve.
Alternative Approaches: LangSmith and Managed Gateways
The most direct alternative is LangSmith, which focuses specifically on LLM tracing and evaluation. LangSmith offers a hosted service with deep integration into LangChain, but it is not open source. The difference is that LangSmith gives you a managed backend, so you do not operate a server, but you lose the ability to self-host and customize. For the AI Gateway piece, a dedicated gateway like LiteLLM or a cloud provider's API management service would be a lighter alternative. LiteLLM is a Python library that provides a unified interface to many LLM providers, with cost tracking and fallbacks. The key difference is that MLflow bundles all these features into one platform, while alternatives let you pick and choose. For teams that already have a monitoring stack like Prometheus or Grafana, MLflow's OpenTelemetry integration might be redundant. The choice depends on whether you want a single vendor or best-of-breed components.
Maintenance, Licensing, and Upgrade Considerations
MLflow is licensed under Apache-2.0, which is permissive and allows commercial use, modification, and distribution without copyleft obligations. The repository is actively maintained, with releases like v3.17.2 in October 2026 and a model-catalog release in April 2026. The last push was November 2026, suggesting ongoing development. The README claims over 60 million monthly downloads, but that is a marketing figure, not a quality metric. For upgrades, the frequent releases mean you need to track changelogs for breaking changes. The platform's size means upgrading the server requires testing not just the core tracking but also the gateway, evaluation, and tracing components. The maintenance cost is not trivial: you need to operate a server, configure a database, and manage credentials for the gateway. For a small team, this could be a burden. However, the Apache-2.0 license means you can fork and modify if needed, and the active release cadence suggests bugs are fixed regularly.
Editorial conclusion
MLflow 3.17 is for teams that want a single, self-hosted platform to trace, evaluate, and deploy both traditional ML models and LLM agents. Small teams can start with a single server command and the OpenAI autologging hook. Large teams will want to verify how the AI Gateway handles rate limits and traffic splitting under their specific provider contracts. Teams already invested in a dedicated observability stack like LangSmith or a managed gateway may find MLflow redundant. Before adopting, check whether the built-in evaluation metrics cover your use cases and whether the OpenTelemetry-based tracing integrates with your existing collectors. The project is actively maintained with frequent releases, and the Apache-2.0 license removes most legal friction, but the breadth of features means you should test the exact workflows you need, not just the quickstart.
Frequently asked questions
What is MLflow used for?
MLflow covers two related jobs. For classical machine learning it provides experiment tracking, model evaluation, a model registry, and deployment to batch and real-time scoring on Docker, Kubernetes, Azure ML and AWS SageMaker. For LLM applications and agents it provides OpenTelemetry-based observability, evaluation with 50+ built-in metrics and LLM judges, prompt versioning with lineage, prompt optimization, and an AI Gateway.
Is MLflow a part of Databricks?
The repository does not state an ownership relationship, and the code is Apache-2.0 licensed. What it does show is a dependency on databricks-sdk below version 1, an examples/databricks/ directory, and a setup wizard that can connect either to an MLflow server or to a Databricks workspace, so a hosted path exists alongside the self-run one.
Is MLflow free or paid?
The project is Apache-2.0 licensed and describes itself as open source, and a local server can be started with uvx mlflow server. The setup wizard can also point at a Databricks workspace, which is a hosted product with its own terms rather than part of the open source distribution.
How do I use MLflow locally?
Start a local server with uvx mlflow server, then point the library at it with mlflow.set_tracking_uri set to http://localhost:5000 and enable autologging, for example mlflow.openai.autolog(). Traces and metrics are then browsed in the MLflow UI at that same address.
How do I install MLflow?
For the server, uvx mlflow server runs it without a global install, and the setup wizard does the wiring for you if you want tracing added to an existing application. For working from the source code, note that the development manifest is generated and deliberately leaves mlflow-skinny and mlflow-tracing out of its requirements, and that the release manifest is the separate pyproject.release.toml.
Is MLflow an MLOps tool?
Yes, on the model side: experiment tracking across runs, automated model evaluation integrated with that tracking, a model registry for the model lifecycle, and deployment to Docker, Kubernetes, Azure ML and AWS SageMaker. The project now also positions itself as an AI engineering platform for agents and LLMs, which is the newer half of the same tool.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mlflow-mlflow)Star history chart for your README
[](https://hysenlabs.com/projects/mlflow-mlflow)Was this useful?