huggingface/accelerate: Running Raw PyTorch Scripts on Any Device
🚀 A simple way to launch, train, and use PyTorch models on almost any device and distributed configuration, automatic mixed precision (including fp8), and easy-to-configure FSDP and DeepSpeed support
At a glance
- What is it?
- Accelerate is a HuggingFace library that abstracts the multi-GPU, TPU and mixed-precision boilerplate in a PyTorch training loop, plus an optional CLI launcher. The README's claim is that five added lines are enough for any standard PyTorch training script, but that number hides real constraints around FSDP, DeepSpeed and launch configuration.
- Who is it for?
- Adopt accelerate if you already own a PyTorch training loop and want FP16, BF16, FP8, multi-GPU, TPU or MPI support without writing a launcher per environment. Do not adopt it if you want a Trainer that owns the loop, the scheduler and the checkpoint format.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
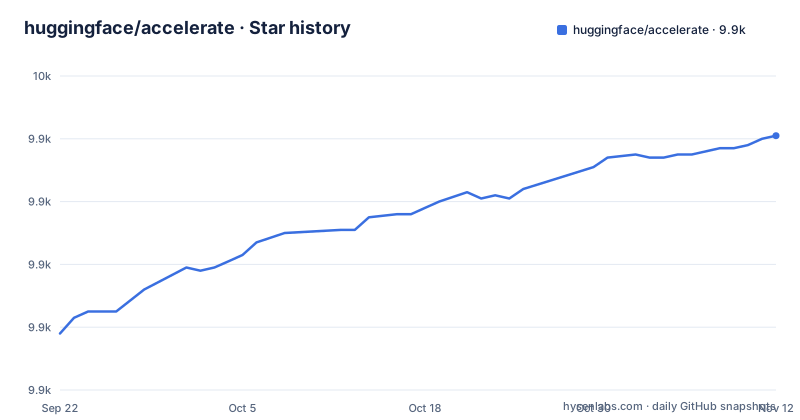
Star history
- huggingface/accelerate9,941 ★ · +63
| Repository | 2026-09-22 | 2026-11-12 |
|---|---|---|
| huggingface/accelerate | 9.9k | 9.9k |
63 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The boilerplate accelerate deletes from a PyTorch training loop
The README states the project was created for PyTorch users who write their own training loop but are reluctant to write and maintain the boilerplate for multi-GPU, TPU and fp16. That is a narrow target and the library respects it. It does not replace the training loop, the optimizer or the dataset class. It replaces the device string, the backward call and the placement of model, optimizer and dataloader.
The README's first diff shows the minimum edit set: import Accelerator, construct it, read device from accelerator.device instead of a literal string, call accelerator.prepare(model, optimizer, data), and replace loss.backward() with accelerator.backward(loss). The second diff goes further and deletes the .to(device) calls entirely, because prepare handles placement. The README notes that the second form is safer in general but requires more changes to your code.
That distinction matters when you are deciding how invasive the migration is. The first form keeps your existing device handling and only swaps the backward pass and the prepare call. The second form assumes you are willing to let the library own placement.
The intended audience is therefore not someone starting a project from scratch. It is someone with a working single-device script who now needs the same script to run on a multi-GPU node, a TPU pod or an MPI cluster without maintaining separate launchers.
How accelerate.prepare and accelerate.backward actually change execution
The mechanism is a wrapper layer, not a rewrite. prepare() takes the model, optimizer and data you pass it. The README says the library handles device placement for you when you omit the .to(device) calls.
accelerator.backward(loss) replaces the plain backward call. The README lists fp8, fp16 and bf16 as supported precisions, and setup.py carries a test_fp8 extra that pulls in torchao, with a comment that Transformer Engine support currently requires pulling the docker image directly rather than installing a package.
The launcher is a separate concern from the wrapper. accelerate config asks questions and writes a config file, and accelerate launch then reads that file to set defaults for the run. The README states the CLI is optional and that python my_script.py or python -m torchrun my_script.py still work. It also says you can pass torchrun arguments directly to accelerate launch, which is how the two-GPU example avoids running accelerate config at all.
Installing accelerate and running a first multi-GPU script
Installation is a standard pip install, and the package name is accelerate. setup.py declares the distribution as name="accelerate" and the README's examples import from accelerate, so the package name is unambiguous. There are optional extras declared in setup.py for deepspeed, rich, sagemaker and a testing bundle, which means the base install does not pull DeepSpeed or the tracker libraries.
pip install accelerateAfter installing, the README's workflow is to configure the environment interactively. The command asks questions and writes a config file that accelerate launch reads automatically.
accelerate configThe README says to answer the questions asked. If you select multi-CPU and answer yes when asked whether accelerate should launch mpirun, the generated config will use MPI for subsequent launches. For a first real run, the README gives the GLUE example from the root of the repository.
accelerate launch examples/nlp_example.pyThe README also shows that you can skip accelerate config entirely by passing torchrun arguments straight through. This is the fastest way to confirm the library works before committing to a config file.
accelerate launch --multi_gpu --num_processes 2 examples/nlp_example.pyWith --multi_gpu and --num_processes 2, expect two processes to start and the script to run distributed across two GPUs. The examples directory also contains config_yaml_templates, which the README calls the configuration zoo and links as a source of ready-made config files.
Where accelerate stops being the right tool
The library deliberately abstracts only the boilerplate. If you want a training loop you do not have to write, accelerate does not provide one: it leaves the rest of your code unchanged. A project that wants a Trainer to own the loop should use one rather than assembling the pieces around accelerate.
The FSDP and DeepSpeed paths are where the abstraction gets thinner. setup.py declares a deepspeed extra, and the Makefile runs tests/deepspeed, tests/fsdp and tests/tp as separate targets from test_core, which reflects that these are distinct code paths with their own failure modes rather than variations of the same run.
Mixed precision is another boundary. FP16 and BF16 are presented as standard options, but the test_fp8 extra in setup.py carries a note that Transformer Engine for now needs to be set up by pulling down the docker image directly.
The MPI path has an external dependency the README is explicit about: Open MPI has to be installed first, and Intel MPI or MVAPICH are listed as alternatives. On a cluster where MPI is not already present, that is work accelerate does not do for you.
accelerate versus PyTorch's own distributed launcher
The honest alternative is torchrun, which is part of PyTorch itself. The README acknowledges this directly: the CLI tool is optional and you can still use python -m torchrun my_script.py. The difference is what each one owns.
torchrun starts processes and sets environment variables. It does not wrap your model, does not give you a device abstraction, and does not coordinate the backward pass for mixed precision. You write the DistributedDataParallel wrapping, the sampler, and the precision context yourself. accelerate wraps those same primitives and exposes them through prepare() and backward().
The trade-off is visibility. With torchrun, every line of distributed setup is in your file and you can debug it directly. With accelerate, the setup lives behind Accelerator() and a generated config file, which is faster to write and harder to inspect when something goes wrong. The README's own framing supports this: it says accelerate abstracts exactly and only the boilerplate, and that the CLI exists so you do not have to remember how to use torch.distributed.run.
There is also a portability argument in accelerate's favor. The README states the same code can run without modification on a local machine for debugging or on a training environment. With torchrun, moving between a single-GPU debug run and a multi-node job usually means editing the launch command and sometimes the script. accelerate config is the mechanism that absorbs that difference.
Maintenance, licence and the cost of upgrading
The repository is not archived and the last push was on 2026-11-02. Releases are frequent and substantive: v1.15.0 on 2026-09-09 covered FSDP2 activation memory and dtensor improvements, v1.14.0 on 2026-06-11 added AMD ROCm support and FSDP2 hardening, and v1.13.0 on 2026-03-04 added Neuron support, removed IPEX and fixed distributed training issues. The IPEX removal in v1.13.0 is the kind of change that can break a build, so pinning a version in production is reasonable.
The two most recent release titles both mention FSDP2, so that path is worth testing first when upgrading. The Makefile splits test_fsdp, test_deepspeed and test_tp from the core suite, and setup.py pins ruff to an exact version for quality checks, which suggests the project tracks tooling closely. The dev version string in setup.py is 1.16.0.dev0, so main is ahead of the latest tagged release.
The licence is Apache-2.0, declared in the LICENSE file and referenced in the README badge. Apache-2.0 permits commercial use and modification and includes a patent grant. It also requires that you preserve the licence and notice files and state significant changes. This is a description of the licence terms, not legal advice; consult your own counsel for your distribution model.
Editorial conclusion
Adopt accelerate if you already own a PyTorch training loop and want FP16, BF16, FP8, multi-GPU, TPU or MPI support without writing a launcher per environment. Do not adopt it if you want a Trainer that owns the loop, the scheduler and the checkpoint format. Before committing, run accelerate config and inspect the generated YAML against your actual cluster, then run accelerate launch examples/nlp_example.py end to end on the target hardware.
Frequently asked questions
How do I install accelerate?
Install it with pip using the package name accelerate. The base install does not include optional dependencies such as DeepSpeed, which setup.py declares as a separate extra.
How do I pip install accelerate?
The distribution is named accelerate in setup.py, so pip install accelerate is the command that matches the package. Extras such as deepspeed, rich and sagemaker are declared separately and are not pulled in by the base install.
How do I install accelerate in Python?
It is a Python package installed through pip, and the README's examples import Accelerator from accelerate. There is no separate installation step beyond the pip install, although the MPI path also requires Open MPI, Intel MPI or MVAPICH on the cluster.
What is accelerate?
It is a HuggingFace library that abstracts the boilerplate for running raw PyTorch training scripts on multi-GPU, TPU and mixed-precision setups. The README describes it as abstracting exactly and only the code related to multi-GPUs, TPU and fp16.
How do I use accelerate with an existing PyTorch training script?
The README's diff adds an Accelerator instance, calls accelerator.prepare(model, optimizer, data), and replaces loss.backward() with accelerator.backward(loss). A second version also removes the manual .to(device) calls because prepare handles placement.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-accelerate)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-accelerate)Was this useful?