huggingface/open-r1: a working guide to the open DeepSeek-R1 reproduction
Fully open reproduction of DeepSeek-R1
At a glance
- What is it?
- Open R1 is a Python repository that rebuilds the DeepSeek-R1 pipeline in public: distillation data, SFT and GRPO training scripts, and an evaluation harness. It is a research codebase for people with multi-GPU nodes, not a packaged library.
- Who is it for?
- Adopt Open R1 if you have an 8xH100 node or equivalent and want to reproduce or extend the R1 distillation and RL pipeline rather than consume a finished model. Do not adopt it if you need a supported inference library, a single-GPU fine-tuning recipe, or a stable API: the README itself says the project is no longer maintained and points to TRL for training, and the training commands assume 8 x H100s (80GB) with batch sizes you must retune elsewhere.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
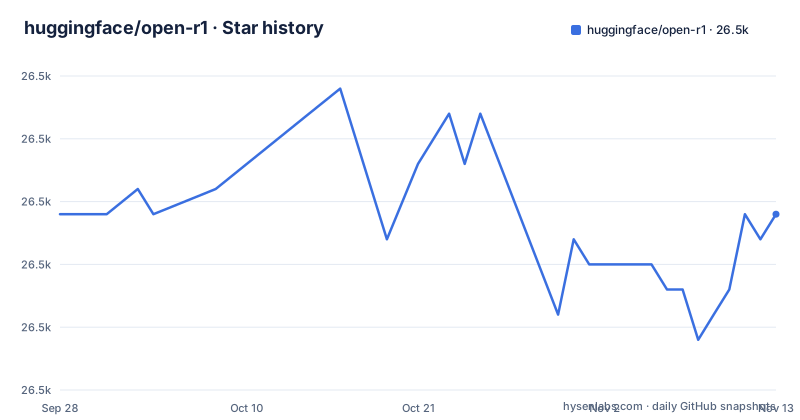
Star history
- huggingface/open-r126,477 ★ · +0
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| huggingface/open-r1 | 26.5k | 26.5k |
0 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Open R1 actually builds, and for whom
DeepSeek-R1 was published with a technical report but without the full training pipeline. Open R1 exists to fill that gap. The README states the goal plainly: "build the missing pieces of the R1 pipeline such that everybody can reproduce and build on top of it." That framing matters, because it tells you what the repository is not. It is not a model release and not a serving stack. It is the set of scripts, configs and datasets that sit between a base checkpoint and a reasoning model.
The intended audience is narrow and specific. The training commands are configured for a node of 8 x H100s with 80GB each, and the README says that for different hardware and topologies you may need to tune the batch size and gradient accumulation steps. Anyone without that class of machine can still read the code and reuse the datasets, but cannot run the published recipes unchanged. The project is aimed at research groups and engineers who want to inspect, modify or extend the R1 recipe, not at application developers who want a reasoning endpoint.
The repository's own plan splits the work into three steps: replicate the R1-Distill models by distilling a corpus from DeepSeek-R1, replicate the pure RL pipeline behind R1-Zero, and then show a path from base model to RL-tuned model through multi-stage training. The news entries in the README mark step 1 as completed as of 2025/05/26, with the Mixture-of-Thoughts dataset and a recipe for OpenR1-Distill-7B.
How the pipeline is laid out: scripts, Makefile, recipes
The architecture is deliberately flat. Almost everything lives in `src/open_r1`, which the README describes as the scripts to train models and generate synthetic data. Three entry points carry the weight: `grpo.py` trains a model with Group Relative Policy Optimization on a given dataset, `sft.py` performs a simple supervised fine-tuning run, and `generate.py` produces synthetic data from a model using Distilabel. A `Makefile` wraps these into runnable commands for each step.
Around those scripts sit directories that do the plumbing. `recipes/` holds the accelerate configs and the YAML training configs, including `recipes/accelerate_configs/zero3.yaml`, referenced in the README's training example. `slurm/` and `scripts/` cover cluster submission and helper work, and `tests/` is split into a fast suite and a `tests/slow/` suite, which the Makefile targets separately.
The data flow is a loop rather than a single pass. Generation produces a corpus, SFT or GRPO consumes it, evaluation scores the result, and the outcome feeds the next round of data generation. The README's evaluation target is where that loop closes: `make evaluate` builds a `MODEL_ARGS` string containing `pretrained`, `dtype=bfloat16`, `max_model_length=32768` and `gpu_memory_utilization=0.8`, then hands it to `lighteval` with a task spec, a chat template, and an output directory under `data/evals/`. For the `lcb` task the target swaps in the `extended|lcb:codegeneration|0|0` spec; for everything else it uses `lighteval|$(TASK)|0|0`. If you run it with `PARALLEL=tensor` it also exports `VLLM_WORKER_MULTIPROC_METHOD=spawn`, a detail that only exists because the tensor-parallel path needs it.
Installing Open R1 and running a first SFT job
The README's installation section opens with a caution: the libraries rely on CUDA 12.4, and if you see segmentation faults you should check the version your system runs with `nvcc --version`. Treat that as a hard prerequisite rather than a note. The environment is created with `uv`, and there is a shortcut, `make install`, that spells out the same steps.
Start by creating the virtual environment. The README uses Python 3.11 and upgrades pip inside it.
uv venv openr1 --python 3.11 && source openr1/bin/activate && uv pip install --upgrade pipNext come vLLM and FlashAttention. The README pins vLLM to 0.8.5.post1 and warns that this also installs PyTorch v2.6.0, which must be kept because the vLLM binaries are compiled for it.
uv pip install vllm==0.8.5.post1
uv pip install setuptools && uv pip install flash-attn --no-build-isolation
Then install the project itself with the extras you need. For most contributors the README recommends the `dev` extra, with Git LFS smudge skipped.
GIT_LFS_SKIP_SMUDGE=1 uv pip install -e ".[dev]"Before training you need credentials for the Hub and for Weights and Biases, and Git LFS present if you intend to push models or datasets.
huggingface-cli login
wandb login
git-lfs --version
With that done, a first real run is the SFT recipe on the distilled corpus. The README gives both a command-line form and a YAML form; the command-line version names `open-r1/Qwen2.5-Math-7B-RoPE-300k` as the base model and `open-r1/Mixture-of-Thoughts` with `--dataset_config all` as the data.
accelerate launch --config_file=recipes/accelerate_configs/zero3.yaml src/open_r1/sft.py \
    --model_name_or_path open-r1/Qwen2.5-Math-7B-RoPE-300k \
    --dataset_name open-r1/Mixture-of-Thoughts \
    --dataset_config all \
    --eos_token '<|im_end|>' \
    --learning_rate 4.0e-5 \
    --num_train_epochs 5 \
    --max_seq_length 32768 \
    --per_device_train_batch_size 2 \
    --gradient_checkpointing \
    --bf16 \
    --use_liger_kernel \
    --output_dir data/OpenR1-Distill-7B
The equivalent YAML route, which the README also shows, is the better starting point if you intend to change more than one or two values. Expect the run to write checkpoints into the `output_dir` you set and to report to W&B, since `wandb login` is part of the setup.
Where Open R1 breaks, and when it is the wrong tool
The most important limitation is the one the project states about itself: the README says the project is no longer maintained and that new issues and PRs won't be reviewed, and it points to TRL for GRPO, SFT and distillation today. This repository publishes no releases, so there are no versioned artifacts to pin against. You track `main`.
Hardware is the second constraint, and it is not negotiable in the published recipes. The training commands are configured for 8 x H100s with 80GB. The README says that scaling the number of GPUs up or down means you should also scale the per-device batch size or the gradient accumulation steps, but it does not provide the tuned values for smaller topologies. On a single consumer GPU, the `--max_seq_length 32768` setting in the SFT example is likely out of reach without retuning.
The dependency chain is the third failure mode, and it is the one most likely to cost you a day. CUDA 12.4, vLLM 0.8.5.post1 and PyTorch 2.6.0 are coupled: the README states that the vLLM binaries are compiled for that PyTorch version and that it is very important to use it. A mismatch shows up as segmentation faults rather than a clean error message, which is why the README tells you to check `nvcc --version` when they appear.
Finally, consider what Open R1 is not for. If you want to call a reasoning model, this repository gives you no serving layer; you would use a released checkpoint instead. If you want a supported fine-tuning library with a stable API, the scripts here are research code that assume you will read and edit them. And if your interest is multimodal training, note that the training scripts the README lists are `sft.py` and `grpo.py`, with `generate.py` for synthetic data.
Open R1 against TRL and the DeepSeek-R1 report
The closest alternative is not another reproduction but the library Open R1 is built on, and the README now says TRL is where the training side of Open-R1 lives on. The setup file pins `trl` to an exact version alongside `accelerate==1.4.0`, `deepspeed==0.16.8`, `datasets>=3.2.0` and `bitsandbytes>=0.43.0`. TRL is the general-purpose trainer collection; Open R1 is the R1-specific assembly on top of it. The difference in approach is scope. TRL gives you trainers you configure for your own task. Open R1 gives you a fixed three-step plan, the datasets that go with it, and the evaluation target that closes the loop, at the cost of being tied to R1's recipe and to the hardware that recipe assumes.
The other reference point is DeepSeek's own tech report, which the README names as the guide for the plan of attack. The report describes what was done; Open R1 is an attempt to make the missing pieces runnable. That distinction is the reason the repository exists at all, and it is also why the code is organized around steps rather than around a stable interface. The three steps are distillation, pure RL for R1-Zero, and multi-stage training from base model to RL-tuned model, and the README marks only the first as completed.
One consequence worth naming: because the project follows a published recipe rather than defining its own, its value rises and falls with how closely the released datasets and configs track that recipe. The news entries trace that progression, from the first training, inference and evaluation pipelines in update #1, through OpenR1-Math-220k and CodeForces-CoTs, to the Mixture-of-Thoughts release that closed step 1.
Maintenance cadence, licence and upgrade cost
The last push to the repository was on 2026-10-26, but the README now states that the project is no longer maintained and that new issues and PRs won't be reviewed; its news section stops at 2025/05/26, when step 1 was marked complete. The repository publishes no releases, so there is no changelog to read and no upgrade path to follow beyond comparing commits on `main`.
That shapes the upgrade cost. Because installation is editable (`uv pip install -e ".[dev]"`) and the dependencies are pinned in the setup file, a routine upgrade means pulling the branch and reinstalling, then re-checking the pinned trio of CUDA 12.4, vLLM 0.8.5.post1 and PyTorch 2.6.0. The `make style` and `make quality` targets run ruff, isort and flake8 at line length 119 with target py310, so contributors are expected to match that formatting before sending changes. The `make test` target runs `pytest -sv --ignore=tests/slow/ tests/`, and `make slow_test` runs the slow suite separately, which tells you the maintainers keep the fast path short and the expensive tests opt-in.
On licensing, the repository is Apache-2.0 and the setup file carries the standard Apache header, adapted from huggingface/transformers. Apache-2.0 permits commercial use and modification and includes an explicit patent grant, with the usual obligations around retaining notices and stating changes. The datasets and models the README links to on the Hugging Face Hub are separate artifacts with their own licence terms. Nothing here is legal advice; if you plan to redistribute a derived model, read the licence on each artifact you used, not just the one on this repository.
Editorial conclusion
Adopt Open R1 if you have an 8xH100 node or equivalent and want to reproduce or extend the R1 distillation and RL pipeline rather than consume a finished model. Do not adopt it if you need a supported inference library, a single-GPU fine-tuning recipe, or a stable API: the README itself says the project is no longer maintained and points to TRL for training, and the training commands assume 8 x H100s (80GB) with batch sizes you must retune elsewhere. Before committing, verify two things on your own machine: that nvcc --version reports CUDA 12.4, since the README warns that segmentation faults come from a mismatch, and that your PyTorch is 2.6.0, because the vLLM 0.8.5.post1 binaries are compiled against it.
Frequently asked questions
What is Open R1?
Open R1 is a fully open reproduction of DeepSeek-R1, which its README now says is no longer maintained, pointing to TRL for GRPO, SFT and distillation. It contains training scripts for SFT and GRPO, a synthetic data generation script built on Distilabel, and a Makefile that wraps each step of the R1 pipeline.
What is Hugging Face?
In this project, Hugging Face is the organisation behind the Open R1 repository and the host for the datasets and models it links to, such as open-r1/Mixture-of-Thoughts and open-r1/OpenR1-Distill-7B. The README also notes that Hugging Face cluster users should add `export UV_LINK_MODE=copy` to their `.bashrc`.
What is DeepSeek?
DeepSeek is the organisation whose R1 technical report Open R1 uses as its guide, and whose R1 model the project distils traces from. The README's plan of attack is to replicate the R1-Distill models, then the pure RL pipeline behind R1-Zero, then multi-stage training from base model to RL-tuned model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-open-r1)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-open-r1)Was this useful?