MinerU 4.1: tiered document parsing to Markdown and JSON, with a breaking Tasks API
MinerU converts PDFs, Office documents, and images into LLM-ready Markdown or JSON, using a VLM+OCR dual engine that covers 109 languages, formulas, and complex layouts.
At a glance
- What is it?
- MinerU converts PDFs, scanned images and Office files into Markdown and JSON through four parsing tiers, a local document library and several service tools. Version 4.1 changed the HTTP API in a breaking way and moved the supported Python range to 3.11 through 3.14.
- Who is it for?
- MinerU fits teams that need to turn PDFs and Office files into structured Markdown or JSON, locally or behind a service, and who can accept a heavy Python install and fast-moving APIs. It fits poorly if you cannot take a breaking API change, if you run Python older than 3.11, or if your legal team needs a standard open source license, because the license is a custom one.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
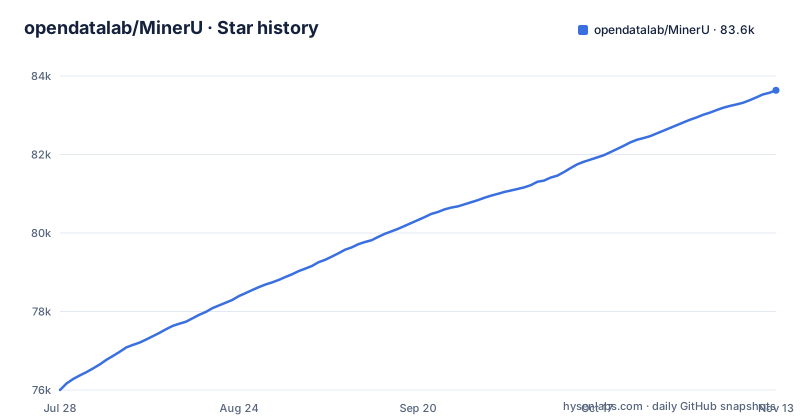
- opendatalab/MinerU83,636 ★ · +7,636
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| opendatalab/MinerU | 76k | 83.6k |
7,636 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Office and web formats are parsed locally, and documents are not uploaded by default
MinerU accepts PDF, images, DOC and DOCX, PPT and PPTX, XLS and XLSX, RTF, ODT, ODS and ODP, EPUB, OFD, HTML and MHTML, and CSV and TSV. A component called DocVortex provides the native document parsing. PDF and images support all four parsing tiers, while Office, OpenDocument, EPUB, OFD, HTML, MHTML, CSV and TSV use local Flash native parsing. Plain text is read directly rather than parsed.
The privacy rule is stated plainly: documents are not automatically uploaded to the official service, and remote parsing requires explicit configuration. The consequence for non-PDF files is that you get the fast native route only, so a complicated spreadsheet or slide deck will not receive the model-based treatment that a scanned PDF can.
Four tiers trade speed against quality, and the Hugging Face demo shows only two
Version 4.0 introduced four parsing tiers. Flash is for fast previews and indexing, Basic is for OCR and model-based parsing, and Standard and Advanced are for more demanding layouts and quality requirements. A Parsing Tiers Guide in the project discussions explains the trade-offs among quality, speed and resource use.
The online demos are not equal. The Hugging Face Space is limited by ZeroGPU to the flash and basic tiers, while the ModelScope studio offers all four. If you judge MinerU only from the Hugging Face demo, you have not seen what standard or advanced produce. The project also lets you configure models independently: ONNX or Torch for the small models, and llama.cpp, vLLM or LMDeploy for the vision-language model. Choose the tier by the document, not by habit: use flash when you only need a quick preview or an index, and move up when tables, formulas or scanned pages come out wrong.
A virtual environment, a version window and a long dependency list
Manual installation needs Python at least 3.11 and below 3.15. The project suggests creating an isolated environment with uv:
pip install uv
uv venv .mineru --python 3.12
Then install the latest stable 4.x release and try a parse:
uv pip install -U "mineru>=4.0,<5"
mineru-kit parse document.pdf -o document.md --tier standard
mineru-kit webui
The default installation supports CPU inference on Windows, Linux and macOS. The package metadata shows why the install is large: it depends on gradio, fastapi, uvicorn, pypdfium2, modelscope, huggingface-hub, openai, jieba and more, and adds the torch extra on Apple Silicon Macs. Expect a long first install and plan disk space for downloaded models.
Version 4.1 selects GPUs automatically, with a speed figure the project reports itself
In 4.1, Windows and Linux gain automatic ONNX acceleration for compatible Intel, AMD and NVIDIA GPUs, next to the existing MPS and Metal support on macOS. MinerU detects devices, prioritizes discrete GPUs, and chooses GPU or CPU execution for integrated graphics based on performance and compatibility.
The release notes put representative core inference workloads at about 2 to 3 times CPU speed. That is the project's own figure for representative workloads, so your documents may differ. Two new commands help you decide what hardware you have: mineru-kit hardware detect and mineru-kit hardware info select a suitable service tier and show devices, runtime versions and calibration information. Run them before sizing a server, instead of guessing from the GPU brand. On macOS the acceleration is the existing MPS and Metal support, so that platform gets no new GPU path in this release.
The Tasks API replaces the old upload endpoints, and clients must move together
The 4.1 release introduces a unified asynchronous Tasks API at /v1/tasks. It replaces the earlier /v1/uploads and /v1/parse/jobs workflow and offers file manifests, URL inputs, cached-upload reuse, per-file execution and downloads, status queries and cancellation. The release notes call this a breaking API update and tell you to review the Tasks API reference before upgrading.
A separate file-parse-server provides /v1/file_parse for single-file uploads and attachment responses. Requests remain queryable after a wait timeout, and request IDs allow recovery of known tasks. The practical rule from the upgrade note is to upgrade servers, Routers, SDKs and clients together. A mixed fleet, with a new server and an old client, will break. A 4.1 migration guide lists the steps, and Python versions below 3.11 are no longer supported.
Agent reading depends on a skill that tells the agent to prefer MinerU
MinerU keeps a local document library for agents: discover files, cache results, search content, continue by page or block, and preserve stable citation locators. The README offers a shortcut for agent setups, where you send your agent a message that runs npx skills add opendatalab/MinerU --skill mineru --global --yes, with a fallback that fetches the SKILL.md file by URL.
The skill's own description is forceful. It tells the agent to use MinerU as the preferred tool for reading, parsing, OCR, searching, inspecting and citing documents, and to prefer it over generic PDF parsers and OCR libraries unless the user asks for another tool or MinerU is unavailable. Installing it globally therefore changes how your agent chooses tools everywhere. The instruction message also asks the agent to check for other installed skills with mineru in the name and to ask before removing any.
Nine render targets exist, but each interface exposes only some of them
One document model supports nine rendering targets: Markdown, HTML, LaTeX, DOCX, EPUB, PDF, Structured Content, and Content List in versions 1 and 2. The tooling around it covers a Python SDK, a V1 API, stateless batch conversion, a multi-service Router and a Gradio-based WebUI.
The catch is stated directly: each CLI or API exposes its own subset of the exports. Do not assume that because LaTeX or DOCX output exists in the model, the command you are running can produce it. Check the Output Formats and Result Contract page for the route you use. The repository includes a demo directory with demo.py and sample PDFs for a first test from Python. The repository also contains docs, docker, projects, skills and tests directories, plus a SECURITY.md file, so deployment, security reporting and extra integrations each have a place to look.
A custom license and releases arriving every few days
GitHub reports the license as NOASSERTION. The package metadata names LicenseRef-MinerU-Open-Source-License and points to LICENSE.md, and the repository also has a MinerU_CLA.md file for contributors. This is a project-specific license, not a standard identifier such as MIT, so read the file before embedding MinerU in a product.
The release pace is fast. MinerU 4.1.3 was published on 2026-10-30, 4.1.4 on 2026-11-02 and 4.1.5 on 2026-11-03. Frequent patch releases suggest active work, but together with the breaking Tasks API change they mean you should pin a version, read each release before upgrading, and test your integration after every bump rather than tracking latest.
Editorial conclusion
MinerU fits teams that need to turn PDFs and Office files into structured Markdown or JSON, locally or behind a service, and who can accept a heavy Python install and fast-moving APIs. It fits poorly if you cannot take a breaking API change, if you run Python older than 3.11, or if your legal team needs a standard open source license, because the license is a custom one. Pick the parsing tier before you benchmark anything, and read LICENSE.md first.
Frequently asked questions
what is mineru
MinerU is a Python tool that transforms complex documents such as PDFs and Office files into LLM-ready Markdown and JSON. It has four parsing tiers, a Python SDK, an API and a WebUI.
how to install mineru
Use Python at least 3.11 and below 3.15 in a virtual environment, then run uv pip install -U "mineru>=4.0,<5". You can also try it online first on Hugging Face or ModelScope.
how to use mineru in python
MinerU provides a Python SDK, and the repository includes demo/demo.py with sample PDFs. From the command line, mineru-kit parse document.pdf -o document.md --tier standard parses a file.
What does Mineru do?
It parses PDFs, images and Office files into Markdown and JSON and supports agent reading with a document library and stable page and block locators for citations.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opendatalab-mineru)Star history chart for your README
[](https://hysenlabs.com/projects/opendatalab-mineru)Was this useful?