LLMFeeder: A Client-Side Webpage-to-Markdown Copier for LLM Context
Browser extension to convert web pages to clean Markdown and copy to clipboard so you can feed it to your favorite LLM model as context with just 1 click!
At a glance
- What is it?
- LLMFeeder is an MIT-licensed Chrome and Firefox extension that runs Readability extraction in the browser and writes Markdown to the clipboard. Its value is the absence of a backend; its limits are the ones any DOM-based extractor inherits.
- Who is it for?
- Adopt LLMFeeder if you paste article text into a chat model several times a day and want the conversion to happen locally, with no server in the path and no account. Skip it if you need scheduled ingestion, headless batch conversion, or extraction from pages that render content only after several seconds of scrolling, since the auto-scroll pass is opt-in rather than automatic.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
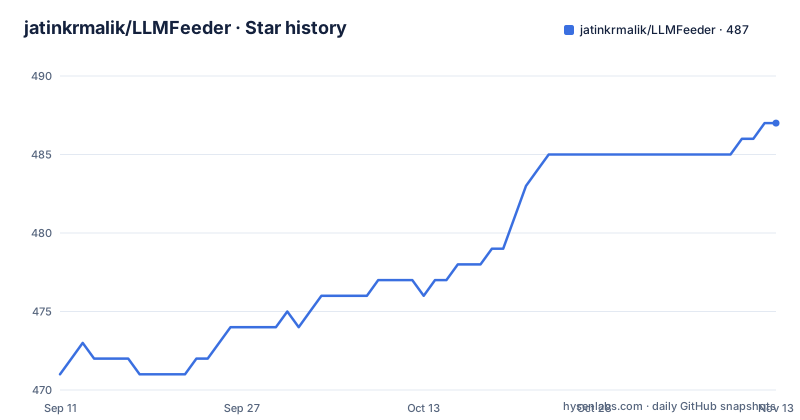
- jatinkrmalik/LLMFeeder487 ★ · +16
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| jatinkrmalik/LLMFeeder | 471 | 487 |
16 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The paste problem LLMFeeder addresses
Copying an article into a chat window usually produces noise: navigation links, cookie banners, footer text, and sidebar promos arrive along with the body. The README frames the extension as a one-click path from a rendered page to clean Markdown, which is the format most chat models handle without complaint. The audience is narrow and specific. It is people who already paste web content into an LLM and have grown tired of trimming it by hand. It is not a scraping framework and not a documentation pipeline. The README describes it as a browser extension available for Chrome and Firefox, with store listings for both, and the repository topics place it among developer tools rather than data engineering projects. That framing matters, because the design choices that follow (clipboard as the primary output, a popup as the primary interface) only make sense for interactive, one-page-at-a-time use.
Readability plus a DOM walk, with no server in the path
The extraction core is the Readability algorithm, which the README names as the mechanism for focusing on main content. Around that, the extension performs its own HTML-to-Markdown conversion, table conversion, and code block handling. The README states that generic <pre> elements become fenced Markdown code blocks with language detection, and that table-to-Markdown conversion was fixed for various HTML table formats in v2.1.0. Images get alt text through what the README calls smart alt text generation with fallbacks. The privacy section is explicit about the data flow: content extraction, Markdown conversion, and clipboard operations all happen inside the browser sandbox, with no remote transmission and no telemetry. The permissions requested are activeTab, clipboardWrite, storage, and scripting. That permission set is consistent with the claim, since none of the four implies network access. Iframe handling changed in v2.2.1: same-origin and srcdoc frames are read through the DOM, while cross-origin frames keep a link or warning instead of page-to-page HTML messaging. That is a deliberate retreat from a more ambitious approach, and the release note presents it as such.
What the popup exposes: scope, links, tokens, metadata
The extension surfaces a set of toggles rather than a configuration file. Content scope can be set to Full Page or Main Content, and the copy button in v2.2.0 gained a split control that overrides the default for a single click without changing the stored setting. Links can be included or stripped, which the README recommends when URLs are not needed because it reduces token usage. Page titles can be included, and metadata formatting uses a template system the README describes as having six variables for citation styles. A token counter estimates counts against GPT-4 and Claude tokenizers with configurable context limits from 4K to 32K. Multi-tab support arrived in v2.1.0: select several tabs with Ctrl/Cmd+Shift, then use Copy All, Download Merged, or Download as ZIP. Keyboard shortcuts are documented as Alt+Shift+M for convert, Alt+Shift+D for download, and Alt+Shift+Z for ZIP. The v2.2.0 release added an opt-in lazy-loading auto-scroll pass intended for chat and AI interfaces such as Gemini, ChatGPT, and Claude, so that long conversations are not truncated at the point where the DOM stops rendering.
Installing from a store versus loading the source
The README lists two installation paths. The first is the browser stores: the Chrome Web Store listing and the Firefox Add-ons listing, both linked from the README badges and the installation section. The second is loading the unpacked source, which the README covers under a separate option. Building from source is a plain JavaScript project with no compiled step implied by the repository's primary language, so check the Installation section of the README on GitHub rather than guessing at a build script. For the store route there is nothing to configure beyond the extension's own options page. The settings that matter in practice are the content scope default, the include-links toggle, and whether auto-scroll is enabled. Debug Mode, added in v2.1.0, is the diagnostic surface to reach for when a specific page converts badly; the README describes it as a built-in logging system for troubleshooting.
Where the approach breaks down
Readability was built for article-shaped pages. On an application UI, a dashboard, or a search results page, the main-content heuristic has nothing to lock onto, and the output will reflect that. The auto-scroll pass exists precisely because chat interfaces do not render their full history up front, and it is opt-in: if you forget to enable it, a long conversation is silently truncated rather than flagged. The iframe change in v2.2.1 is another boundary. Cross-origin frames now yield a link or a warning instead of their contents, so pages that embed the substance you want inside a third-party frame will produce a placeholder. The token counter is described as an estimation against named tokenizers, not as a call to the model's own counting endpoint, so treat the number as a budget hint rather than an exact figure. And the output target is the clipboard. There is no watch folder, no API, and no scheduled job. Anyone who needs to convert a few hundred URLs overnight is using the wrong tool, and the multi-tab ZIP export does not change that, since it still requires tabs to be open and selected by hand.
How it compares to server-side extractors
The obvious alternative is a server-side or CLI extraction pipeline, for example a script that fetches a URL and runs a Readability port in Node before writing Markdown to disk. The difference is not the extraction algorithm, which is the same family of code, but the trust and automation boundary. A server-side tool can run unattended, follow links, and write into a corpus, and it can also see every URL you process. LLMFeeder makes the opposite trade: it only sees pages you have open, it cannot run without you, and the README's privacy section leans on that constraint as the selling point. A second alternative is the browser's own reader mode combined with manual copying, which avoids installing anything but gives you no Markdown structure, no code fences, and no token estimate. The third, for people who want structured extraction at scale, is a dedicated scraping service, which reintroduces the backend that LLMFeeder exists to avoid. None of these is strictly better. The choice is between unattended throughput and a local, inspectable path.
Maintenance, releases, and the MIT licence
The release cadence visible here is uneven rather than weekly. v2.1.0 landed in February 2026, v2.2.0 in July 2026, and v2.2.1 in August 2026, with the last push to the repository in September 2026. The v2.2.0 notes mention a Jest test suite and a GitHub Actions workflow for pull requests, which is the main signal that changes are gated rather than pushed straight to main. Upgrading is the ordinary extension path: the store handles it, and the settings live in browser storage, so a reinstall means reconfiguring scope, links, and metadata templates by hand. The licence is MIT, which permits commercial use, modification, and redistribution provided the copyright notice and permission notice are retained. That is a permissive arrangement, but it is not legal advice, and anyone embedding the extraction code in a product should read the licence text and the Readability dependency's own terms, since the README does not enumerate third-party licences. The extension ships no backend, so there is no server bill and no data processing agreement to negotiate, which is the practical consequence of the MIT plus client-side combination.
Editorial conclusion
Adopt LLMFeeder if you paste article text into a chat model several times a day and want the conversion to happen locally, with no server in the path and no account. Skip it if you need scheduled ingestion, headless batch conversion, or extraction from pages that render content only after several seconds of scrolling, since the auto-scroll pass is opt-in rather than automatic. Before relying on it, open the extension's Debug Mode on three pages you actually cite: a news article, a documentation page with fenced code, and a long chat thread. Compare the token counter's estimate against the model's own count and check whether tables and code fences survive the round trip.
Frequently asked questions
What Chrome extension can I use to convert a webpage to Markdown?
LLMFeeder is published on both the Chrome Web Store and Firefox Add-ons, converts a page to Markdown in one click, and copies it to the clipboard. It uses the Readability algorithm to isolate the main content, can save the result as a Markdown file, and can convert several selected tabs at once into one file or a ZIP.
Is there a CLI tool that can convert HTML to Markdown?
LLMFeeder is not one. The conversion runs inside the browser page, which is what lets it use Readability and read same-origin iframes through the DOM. The repository does have a command line build surface, a Makefile with targets for Chrome, Firefox and source packages that delegate to a shell script, but the visible documentation describes no standalone conversion command.
Does LLMFeeder send the page content anywhere?
Not according to the project, and the claim is meant to be checkable. It operates as a fully client side extension with zero backend dependencies, does all extraction, conversion and clipboard work in the browser sandbox, has no analytics or tracking, and requests four permissions: activeTab, clipboardWrite, storage and scripting. The README asks users to read the source to verify that.
What does the token counter in LLMFeeder do?
It estimates the token count of the converted Markdown in real time using the GPT-4 or Claude tokenizer, with a configurable context limit from 4K to 32K. It is computed locally, which is why the extension ships a tokenizer rather than calling an API to count.
How do I install LLMFeeder without a browser store?
Download the latest release zip and extract it, then in Chrome open chrome://extensions, enable Developer mode, use Load unpacked and pick the extracted extension directory. The Firefox path goes through about:debugging, and the visible text of that step is cut off there. Both store listings are also marked as available.
Why did LLMFeeder change how it reads iframes?
In version 2.2.1 same-origin and srcdoc frames are read through the DOM, while cross-origin frames get a link or warning placeholder instead of page-to-page HTML messaging. The placeholder links are built with DOM APIs and only for explicit http(s) URLs, so the extension stopped exchanging messages with frames it cannot read directly.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jatinkrmalik-llmfeeder)Star history chart for your README
[](https://hysenlabs.com/projects/jatinkrmalik-llmfeeder)Was this useful?