jCodeMunch MCP: Symbol-Level Code Retrieval That Cuts Agent Token Use
Cut AI token costs 95%+ on code exploration. The leading MCP server for precise, symbol-level GitHub code retrieval via tree-sitter AST. Works with Claude Code, Cursor & any MCP client. 313B+ tokens saved.
At a glance
- What is it?
- jCodeMunch MCP indexes a codebase with tree-sitter and serves exact functions, classes, and import graphs to AI agents. It reports 28.3x fewer tokens than a grep-and-read baseline, but its licensing and benchmark caveats need scrutiny.
- Who is it for?
- Adopt jCodeMunch MCP if you run Claude Code, Cursor, or another MCP client on large codebases and want to replace whole-file reads with exact symbol fetches; the benchmark evidence, while self-reported, is methodologically detailed and reproducible. Do not adopt it if you need a permissive open-source license, because the dual-use license with a commercial clause will trip up many organizations.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
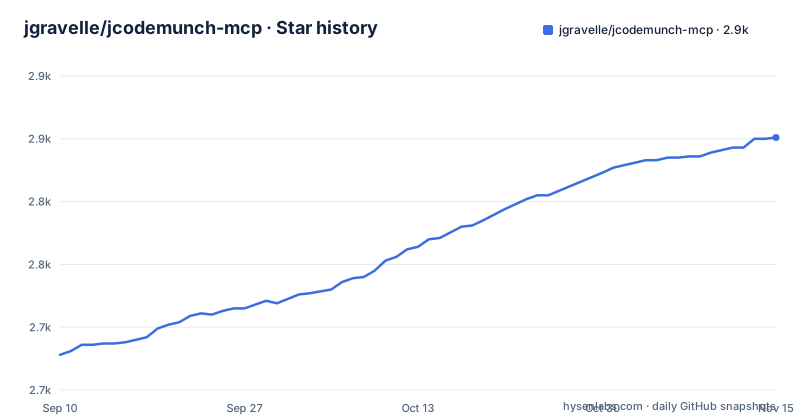
- jgravelle/jcodemunch-mcp2,851 ★ · +173
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| jgravelle/jcodemunch-mcp | 2.7k | 2.9k |
173 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Whole-File Reads Burn the Context Window
AI coding agents explore repositories by opening entire files and scanning thousands of lines to find one function. That is expensive in tokens and slow. jCodeMunch MCP attacks this directly: it parses source code with tree-sitter, stores a structured index of symbols (functions, classes, methods, constants) with byte offsets, and lets an agent fetch only the exact implementation it needs. The intended user is a developer running Claude Code, Cursor, VS Code, Codex CLI, Windsurf, Continue, or any MCP-compatible client against a codebase where context limits are the bottleneck. The README's own language is blunt: it calls the traditional approach a 'token incinerator.' That framing is accurate for large repos where an agent repeatedly reads the same file regions.
Mechanism: Tree-Sitter Index Plus Scoped Context Bundles
The core architecture is visible from the README and the repository layout. First, jCodeMunch indexes a codebase once. It parses source with tree-sitter and stores symbol metadata: signature, kind, qualified name, summary, and byte offsets, alongside raw file content in a local index. Then, on query, it fetches exact implementations rather than re-reading files. The tool set includes search_symbols, get_symbol_source, and structural queries like find_importers, get_blast_radius, get_class_hierarchy, and find_dead_code. The blast radius query answers 'what breaks if I change X?' by tracing import relationships. The find_importers query detects orphaned files, which the README notes native tools cannot answer without scripting. Responses use a compact wire encoding called MUNCH, described in SPEC_MUNCH.md, which trims a median 45.5% more bytes off responses. That encoding choice matters because token counts are not the only cost; byte-level compression reduces latency and memory pressure too.
Installation and Configuration: uvx and MCP Client Setup
Getting it running follows standard MCP server patterns. The README shows one-click install links for VS Code that pass a command and args to the client. The underlying command is uvx jcodemunch-mcp. For any MCP client, you register a server with that command. The repository includes CLIENTS.md, QUICKSTART.md, and a full install section. No API keys are mentioned for the local index, which suggests a local-first design: the index lives on your machine. The PyPI package is jcodemunch-mcp. Release notes mention a CI harness that runs on every change, with publishing as a dispatched workflow. That is a concrete detail: the project has automated checks, but you should still verify the setup against your own client because MCP configuration varies by editor.
Evidence: Benchmarks and Their Caveats
The README presents a reproducible benchmark run on 2026-09-03 against v1.108.316. It used tiktoken cl100k_base across three public repos: expressjs/express, fastapi/fastapi, and gin-gonic/gin. The workflow was search_symbols (top 5) plus get_symbol_source three times per query. Two baselines were compared: a grep-top-3 approach (rg -l, rank by match count, open top 3 whole files) and a read-all ceiling. Against the grep baseline, jCodeMunch used 28.3x fewer tokens across 15 task-runs, with per-query multiples ranging from 7.6x to 81.2x. The README is honest that no single multiple describes every query. The full methodology and pinned commits live in benchmarks/METHODOLOGY.md. There is also an independent A/B test on a Vue 3 + Firebase codebase showing an 80% success rate versus 72% for native tools, and a 15-25% tool-layer savings. These are self-reported figures from the project's own harness, though the A/B test is described as independent. The production counter claims (838B+ tokens saved, 136,000+ installs) are unverifiable from the repository and should be treated as marketing floors, not engineering data.
Limitations and When It Is the Wrong Tool
The most obvious limitation is licensing. The repository license is NOASSERTION on GitHub, and the README describes a 'dual-use' license with a clear commercial clause: 'Free for personal use. Use it to make money, and Uncle J. gets a taste.' That means any commercial deployment requires a paid license, which is a hard stop for many organizations that expect open-source permissiveness. The README also includes a guarantee that if jCodeMunch does not pay for itself, you do not pay, but that is a business promise, not a technical one. Technically, the tool only helps if your agent actually uses MCP structural queries; if your workflow is simple grep-and-read on small files, the indexing overhead may not pay off. The benchmark itself shows a wide range: 7.6x to 81.2x per query, so on trivial lookups the savings are small. Also, the index is local-first, which means you must build and maintain it; the README does not specify incremental update behavior for frequently changing codebases, so you should verify that before adopting it for active development.
Alternative: Native Agent Tools and the Difference
The main alternative is what the benchmark calls 'grep-and-read': using rg to find files and then reading them whole with an agent's native Read tool. That approach works in any editor without extra setup and has no licensing cost. The difference is architectural. Grep-and-read returns whole files, forcing the agent to filter irrelevant lines in the context window. jCodeMunch returns exact symbol bodies with byte offsets, so the agent never sees unrelated code. The README also contrasts with 'read-all', which concatenates every source file, a ceiling nobody pays in practice. Another alternative is to rely on an MCP server that simply wraps file search without AST parsing, but the README argues that such tools cannot answer structural queries like get_blast_radius or find_importers. For a team that already uses native Grep/Read tools and has small files, the alternative is simpler. For a team with large modules and repeated exploration, the AST approach has a clear advantage in token count.
Maintenance and Upgrade Cost
The release cadence is high: versions like v1.108.317, v1.108.316, and v1.108.315 all landed within days of each other. That implies active maintenance and a fast iteration loop. The release notes are terse and sometimes cryptic, for example 'A display preference edited the data it was displaying' and 'A fix for a false positive can install a false negative.' That second note is a genuine warning: fixes can introduce regressions. The CI harness runs on every change, which is good, but the version numbering suggests a rolling release model where you may need to update frequently to get fixes. The README mentions a DOI (10.5281/zenodo.20102349), so there is a citable snapshot for reproducibility. For upgrade cost, the main burden is re-indexing after each update if the index format changes, though the README does not specify that. You should pin a version in your MCP config and test before bumping, given the rapid release pace.
Editorial conclusion
Adopt jCodeMunch MCP if you run Claude Code, Cursor, or another MCP client on large codebases and want to replace whole-file reads with exact symbol fetches; the benchmark evidence, while self-reported, is methodologically detailed and reproducible. Do not adopt it if you need a permissive open-source license, because the dual-use license with a commercial clause will trip up many organizations. Before committing, verify three things: run the pinned benchmark harness on your own repository, read SPEC_MUNCH.md to confirm the wire format fits your security constraints, and check the commercial license terms against your revenue model, since the README states that using it to make money requires a paid license.
Frequently asked questions
How do I install jcodemunch-MCP?
The recommended path is `uv tool install jcodemunch-mcp` followed by `jcodemunch-mcp init`, chosen so nothing is written into system Python and so it works on PEP 668 distros where a bare pip install is refused, with Ubuntu 24.04 and Debian 12 named as examples. One-click install links are also offered for VS Code, VS Code Insiders and Cursor, each carrying uvx and jcodemunch-mcp.
What license is jcodemunch-mcp under?
The license recorded against the repository is NOASSERTION, and the manifest uses a project-specific identifier, LicenseRef-jCodeMunch-Dual-Use-1, with the LICENSE file at the root. The README states only the shape of it: free for personal use, and commercial licenses sold separately. The terms themselves are in the LICENSE file, not in the identifier.
Does the jCodeMunch Docker deployment require a token?
Not by default. The Compose file sets JCODEMUNCH_HOST to 0.0.0.0, publishes port 8901 directly with a comment saying to remove it when Caddy handles everything, and takes JCODEMUNCH_HTTP_TOKEN from the environment with an empty default, while JCODEMUNCH_RATE_LIMIT defaults to 60. Its own quick start passes the token inline on the command line.
Why does jcodemunch-mcp refuse my local sentence-transformers model path?
That is what two of the recent releases are about. v1.108.326 requires a sentence-transformers that does not run a local model's code for the semantic extra, and v1.108.327 refuses a local model path when the installed sentence-transformers would run its code. The titles describe the restriction rather than a bug fix.
How trustworthy is the 28.3x token saving figure for jcodemunch-mcp?
It is one measurement with a stated method: tiktoken cl100k_base, three public repositories pinned to commits, run on 2026-09-03, 15 task-runs in total, against a grep-and-read baseline of the top three files opened whole. The per-repository spread runs from 15.6x to 39.7x, the README calls the read-all comparison a ceiling nobody pays, and a separate 50-iteration A/B on a production codebase reported 80 percent success against 72 percent with tool-layer savings of 15 to 25 percent.
Which languages does jcodemunch-mcp parse, and where do the grammars come from?
Parsing is done with tree-sitter, and the manifest records that the pin exists because the 1.x wheel stopped bundling grammars: get_parser downloads the grammar into a user-level cache on first use. The note says this was verified by walking the language list from an empty cache and ending up with 67 shared libraries, so the first query in a language reaches the network and writes native code into your home directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jgravelle-jcodemunch-mcp)Star history chart for your README
[](https://hysenlabs.com/projects/jgravelle-jcodemunch-mcp)Was this useful?