op7418/Humanizer-zh: a skill file that says out loud it is not a detector
Chinese localization of Humanizer, a Claude Code Skill aimed at removing AI-generated traces from text.
At a glance
- What is it?
- Humanizer-zh is a Claude Code skill for editing Chinese prose, and the deliverable is one markdown file with a readme beside it. What makes it worth reading is the framing it refuses: it is guidance an agent reads and follows, it cannot prove who wrote anything, it does not promise to pass a detector, and one of its four teaching examples deliberately returns the input unchanged.
- Who is it for?
- Use Humanizer-zh if you write Chinese and want a second pass over drafts that flags filler, repetition and templated phrasing, and if you are willing to check the result, because the skill preserves facts, certainty and your register by design and its own example set includes text it leaves alone.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 53 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
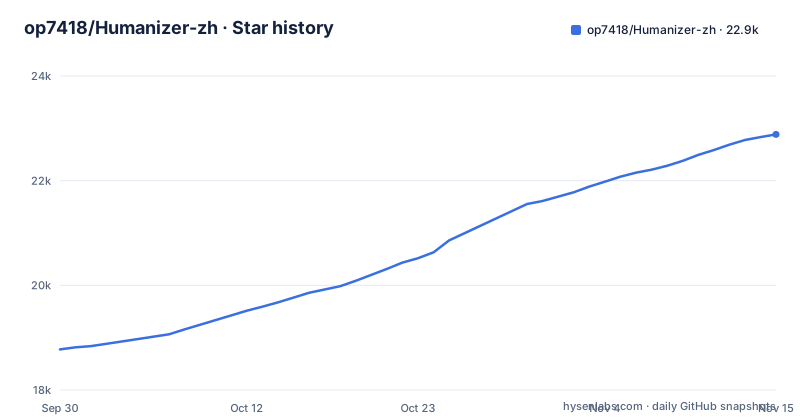
- op7418/Humanizer-zh22,884 ★ · +4,108
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| op7418/Humanizer-zh | 18.8k | 22.9k |
4,108 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The deliverable is one markdown file, installed into a skills directory
The repository has six top level entries and the important one is the skill definition file. Everything else is the readme, a change log, a licence, a gitignore and a tests directory. There is no library to import and no service to run.
Installation is therefore a file placement, and the readme gives three routes. The recommended one is a single command that installs the skill into the right directory automatically:
npx skills add https://github.com/op7418/Humanizer-zh.gitThe second is a clone into a specific path:
git clone https://github.com/op7418/Humanizer-zh.git ~/.claude/skills/humanizer-zhThe third is manual: download the archive or clone locally, then copy the folder into the agent's skills directory, which is given per platform, and the required shape is shown in the readme:
~/.claude/skills/humanizer-zh/
├── SKILL.md       # 技能定义文件(中文版)
└── README.md      # 说明文档
Verification is a restart or a skills reload followed by typing the skill's slash command in a conversation. So an update is a re-clone, and the whole thing is bound to one agent's directory convention.
The readme says it cannot prove authorship and does not promise to beat a detector
Two sentences early in the document do most of the work of framing it. It is editing guidance that an agent reads and follows, not a standalone detection program. It cannot prove who wrote an article, and it does not guarantee passing any AI detector.
That is a refusal of two claims that similar tools are usually sold on, and it is stated by the project itself rather than left for the reader to infer. The four teaching examples reinforce it. The one about a product introduction that lacks data is a case where the rewrite removes the adjectives and the note underneath says the missing evidence can be requested from the author but cannot be produced by polishing. The one about a bug report is a case where the hedge stays a hedge, and the note says the speculation is not turned into a causal conclusion and the cause is not attributed to the community on their behalf.
So the claim being made is narrow and concrete: this improves prose, it does not launder it, and the person using it remains responsible for whether the underlying statements are true.
The fourth example returns the input unchanged
There are four worked examples, and the readme says at the top of them that they are all teaching inputs with no unshown supplementary material.
The first three all change something. A product blurb loses its parallel adjectives. A bug report is split into two sentences so the hedge and the unconfirmed cause are separated. A release note loses its opening sentence about the team's pursuit of innovation while keeping the three real features and the statement that offline editing is planned and not yet tested, with a note explaining that the three features are kept and not deleted or padded to suit the three-part shape.
The fourth changes nothing. The original is a two line instruction to save the file before closing the window because unsaved changes are lost, and the rewrite is the same two lines. The note under it says the skill is not required to produce a change on every invocation.
That example is the most informative one in the document. A tool that always outputs something different is a transformation, and a transformation is something you have to diff. A tool that is allowed to return its input is an editor, and an editor you can point at a paragraph that is already fine.
The priority order puts information ahead of style, and patterns cannot override it
The editing principles section opens with an ordering rather than a list, and that is the design. The constraint priority is: preserve information and degree of certainty, follow the user's scope and register, match the author's voice, and only then handle specific expression problems. A pattern match cannot override those requirements.
The rules that follow each restate the same idea in a form you can check. Do not invent features, data, sources, the identity of people, or first person experience. Preserve negation, conditions, attribution, scope, time and completion status, so that a possibility does not become a certainty and a plan does not become a done thing. Judge three item lists, four character idioms, passive sentences, dashes and conjunctions by the work they do rather than removing them mechanically.
The register rule is the one that matters most for a second pass over someone else's draft. Essays may keep their personality, academic and business writing keeps its formality, and the explicit instruction is not to turn every article into the same colloquial voice. Combined with the permission to return the input unchanged, that is the difference between an editor and a stylistic homogeniser.
File editing has its own preservation list, and a heading is a link target
The principles carry one rule that is about files rather than prose, and it is the rule with the most operational consequence. When editing a file, the default is to preserve code, commands, paths, link targets, YAML, data, headings and anchors. Changing a heading or the structure requires checking the references.
Read that as a statement about failure modes. A markdown heading is not just display text, it is the target of every link to it, so a rewrite that improves a heading title silently breaks inbound links unless somebody checks. A path in a code block is not prose, and a command is not prose, and a YAML key is not prose. A skill that rewrites text without this list will eventually rewrite a command it should have left alone.
There is also a rule about what gets delivered. By default only the final draft is delivered, and the skill is explicitly not asked to show intermediate drafts, a list of which patterns it hit, or a self score. That is a deliberate choice against a common convention: it means the person running it sees the result and nothing else, which is cheaper to review and cheaper to run, at the cost of no visibility into why a change happened.
31 checkpoints in six groups, and the catalogue disclaims being a detection standard
The pattern catalogue is the longest part of the document, and it opens with two framing sentences. It keeps 31 checkpoints, using the lettered classification from an earlier pull request so they can be compared across revisions. And it says directly that this is a checklist of editing problems, not a standard for detecting who wrote something.
The groups are six, and the numbering is stable across the whole list. Group A covers setup in place of statement, with five checks. Group B is formulaic rhythm with six, group C is elevation and borrowed authority with seven, group D is formulaic layout with three, group E is chat and draft residue with four, and group F is a supplementary group of checks specific to Chinese with six.
That last group is the localization. The original project supplied a classification through group E, and this repository adds a Chinese-specific set on top: long attributive clauses, a construction built on a verb phrase, stacked passive sentences, parallel four character idioms, generic background sentences, and formulaic closing lines.
So the taxonomy is not a general theory of writing. It is one English checklist plus six checks that only apply to Chinese, which is exactly the right shape for a localization and also exactly the shape that tells you what it will not catch.
The evidence is eighteen cases, and the readme rules out the two easy metrics
The verification section points at a tests directory that contains eighteen short text cases, one markdown file sample, and a structure check script. It also says that this update included a long form comparison between the old version and the revised one, checking numbers, conditions, attribution, author attitude and file structure.
Then two sentences that remove the easy conclusions. A single limited set of samples cannot represent all models and registers. And a drop in word count, or a model's own score, cannot be used to demonstrate the effect.
That is the whole evidence base, and it is deliberately modest. There is no benchmark, no corpus, and no claim that one exists. What the change log and the tests give you is a way to see what changed in the rules, and the eighteen cases are examples rather than measurements.
The provenance is equally explicit. Five sources are credited: the original project at a pinned tag, which supplied the lettered classification, the voice calibration and the file patterns; a pull request in this repository, which is the structural basis of this revision and the source of the Chinese checkpoints; an earlier pull request cited as a reference for example fidelity, with a note that this revision did not merge that branch; a separate repository cited for concise expression and editing checks; and a published article on the signs of machine generated writing, credited as the observation source of the original project. The repository is MIT licensed.
Editorial conclusion
Use Humanizer-zh if you write Chinese and want a second pass over drafts that flags filler, repetition and templated phrasing, and if you are willing to check the result, because the skill preserves facts, certainty and your register by design and its own example set includes text it leaves alone. Do not use it as evidence of authorship in either direction, since the README says it cannot prove who wrote a text and that its checkpoint list is an editing problem checklist rather than an authorship detection standard. Check three things before you rely on it: the revision you are reading, because the rules and examples were rewritten and ordinary dashes, conjunctions and parallelism are no longer changed automatically; whether your text is a file, since file editing preserves code, commands, paths, link targets and anchors by default and a heading change needs its references checked; and how you judge the result, because the repository's own evidence is eighteen short cases and a structural check script, and it explicitly says that word count and model self scores do not demonstrate the effect. The license is MIT and the last push was 2026-09-23.
Frequently asked questions
Can I trust AI Humanizer?
The repository's own framing is that it is editing guidance read and executed by an agent rather than a standalone detection program, that it cannot prove who wrote an article, and that it does not guarantee passing any AI detector. Its stated purpose is to remove filler, repetition and templated phrasing while preserving facts, the degree of certainty, and the author's voice.
Does Humanize AI get detected?
The repository makes no claim in either direction and says explicitly that it does not guarantee passing any AI detector. Its verification section adds that a single limited set of samples cannot represent all models and registers, and that neither a drop in word count nor a model's own score can demonstrate the effect. The test material is eighteen short cases, one markdown sample and a structure check script.
Is Humanizer considered AI?
The document's subject is the traces machine generated writing leaves in prose, expressed as 31 checkpoints in six lettered groups, including formulaic rhythm, elevation and borrowed authority, formulaic layout, and chat or draft residue, plus a supplementary group of checks specific to Chinese. It states that the catalogue is a checklist of editing problems and not a standard for detecting authorship.
Is it ethical to use AI humanizer?
The repository does not address ethics. What it does is constrain the tool. Its principles forbid inventing features, data, sources, the identity of people or first person experience, require preserving negation, conditions, attribution, scope, time and completion status, and state that a pattern match cannot override preserving information and certainty.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/op7418-humanizer-zh)Star history chart for your README
[](https://hysenlabs.com/projects/op7418-humanizer-zh)Was this useful?