Reader: A URL Prefix That Turns Web Pages into LLM-Ready Markdown
Convert any URL to an LLM-friendly input with a simple prefix https://r.jina.ai/
At a glance
- What is it?
- Jina AI's Reader service converts any URL into clean markdown via a simple prefix, and the open source branch shows how the core pipeline works. This article reviews what it does, how it runs locally, and where its limits lie.
- Who is it for?
- Reader is for developers and teams that need a low-friction way to feed web content into LLM pipelines without building crawlers and parsers. It is not for those who require fine-grained control over rendering, need the full SaaS storage layer, or must avoid sending URLs to a third-party service.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 176 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
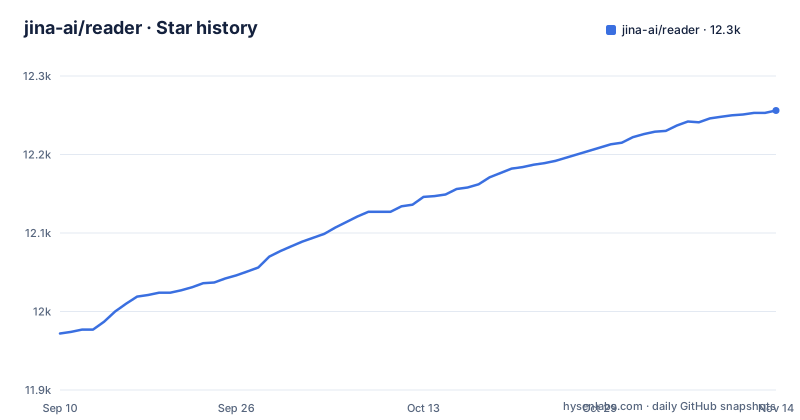
Star history
- jina-ai/reader12,256 ★ · +284
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| jina-ai/reader | 12k | 12.3k |
284 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Reader Solves and Who It Is For
Reader addresses a specific pain: LLMs and RAG pipelines consume text, but the web is full of HTML, JavaScript-heavy pages, and PDFs. The README positions it as a tool that gives LLMs better input by converting any URL to an LLM-friendly format. The core mechanism is a URL prefix: prepend https://r.jina.ai/ to a target URL, and the service returns clean markdown. A second endpoint, https://s.jina.ai/, performs web search and fetches the top five results, applying the same conversion. This is aimed at developers building agents or retrieval systems who would otherwise need to handle browser rendering, blocking, and CSS extraction themselves. The free, hosted API is a core Jina AI product, and the repository is the open source branch of that codebase.
The Two-Endpoint Architecture: Read and Search
Reader has two distinct operations. The read endpoint, r.jina.ai, takes a URL and returns markdown. The search endpoint, s.jina.ai, takes a query and returns markdown from the top five search results. The search behavior is notable: it does not just return titles and snippets like typical search APIs. According to the README, it fetches each result URL and applies the same read pipeline. That means the output includes full page content, not just metadata. For in-site search, you can restrict results by adding a site parameter, as in curl 'https://s.jina.ai/When%20was%20Jina%20AI%20founded%3F?site=jina.ai&site=github.com'. This design collapses two steps (search then fetch) into one request, which is convenient for agents that need full content.
Inside the Conversion Pipeline: Rendering Choices and File Types
The README explains that Reader renders web pages with headless Chrome or fetches them lightweight via curl-impersonate, and it picks between the two intelligently. That means it can handle JavaScript-heavy sites but also has a fast path for static pages. PDFs are parsed with PDF.js and returned as markdown. MS Office documents (Word, Excel, PowerPoint) are converted via LibreOffice and then processed as HTML or PDF. Images are captioned by a vision-language model, giving text-only LLMs hints about what the image contains. This variety matters: the tool is not just for HTML. The open source branch, however, strips out the MongoDB-backed SaaS storage layer, so the local version runs in stateless mode or with optional MinIO/S3 bucket caching via docker compose. That is a real architectural boundary: the hosted service has a storage backend, but the open source code does not.
Getting It Running Locally: Commands and Configuration
The README's 2026-04 update points to a Local development section and says the open source branch runs in stateless mode out of the box, with optional MinIO/S3-compatible bucket caching via docker compose. According to package.json, running it yourself needs Node 22.15 or newer; npm run build then npm start runs build/stand-alone/crawl.js. The README points to cookbooks.md for advanced usage, including PDF and Office uploads via a file body field. For configuring behavior, you use request headers. The most important is x-respond-with, which sets the output format: markdown, html, text, screenshot, pageshot, frontmatter, or markdown+frontmatter. For example, curl -H 'X-Respond-With: frontmatter' 'https://r.jina.ai/https://example.com' returns a YAML front matter block with title, description, and URL. The source of truth for all options is src/dto/crawler-options.ts.
Output Formats and the Frontmatter Option
The default response uses a custom header format with Title and URL Source lines. If you want structured metadata, the frontmatter option replaces that with a standard YAML block. The README gives an example output for example.com that includes title, description, and url fields. This is useful for RAG systems that need to store source metadata alongside content. The markdown+frontmatter option is like frontmatter but covers the full page without readability filtering, and the plain markdown option also returns markdown without going through readability.
Limitations and Failure Modes
The most obvious limitation is that the open source branch is not the full service. The README states that the MongoDB-backed SaaS storage layer is not included. That means the local version cannot rely on persistent caching unless you set up MinIO or S3. In stateless mode, every request is processed fresh. Another constraint is that the hosted service is rate-limited, and the README points to the pricing page for details. Also, the image captioning feature depends on a vision-language model. Finally, because Reader chooses between headless Chrome and curl-impersonate automatically, you can still force an engine with x-engine (browser, curl or auto) and route traffic through your own proxy with x-proxy-url.
Alternatives and How They Differ
The obvious alternative is to build your own pipeline with a headless browser like Puppeteer and a markdown extraction library such as Turndown or Readability. That approach gives you full control over rendering, caching, and parsing, but it requires you to handle anti-bot measures, JavaScript execution, and page-specific quirks yourself. Reader abstracts those away, but at the cost of being a remote service or a stateless local process. Another alternative is using a search API like Bing or Google Custom Search, which returns titles and snippets but not full content. The README contrasts Reader's search with search function-calling in agent and RAG frameworks that often return only title, URL and description: it fetches the top five results and applies r.jina.ai to each, so you get full page content. If you only need search results and not full text, a standard search API is lighter and cheaper. The choice depends on whether you want content or just links.
Maintenance, License, and Upgrade Considerations
The repository is under active development, with updates dated as recently as 2026-04. The 2025-03 refactor removed Firebase dependencies, which suggests the team is willing to make significant architectural changes. That is good for longevity but means the open source branch may lag behind the SaaS code. The README notes that the open source branch was re-synchronized with the SaaS code in 2026-04, but the storage layer is stripped. So if you depend on the open source version, you may not get new SaaS features immediately. The license is Apache-2.0, which permits commercial use, modification, and distribution with attribution. You can fork and extend it, but you should check the license file for exact terms. The maintenance cost is moderate: the codebase is TypeScript and uses Docker, so you need to keep up with upstream changes if you want security fixes. The absence of GitHub releases means you cannot pin to a stable version easily.
Editorial conclusion
Reader is for developers and teams that need a low-friction way to feed web content into LLM pipelines without building crawlers and parsers. It is not for those who require fine-grained control over rendering, need the full SaaS storage layer, or must avoid sending URLs to a third-party service. Before adopting the open source branch, verify that the stateless mode meets your rate and caching needs, and check the live API docs for current header defaults and validation rules. If you need a self-contained solution, compare it against a headless browser plus a markdown extraction library, but expect to handle JavaScript rendering and anti-bot measures yourself.
Frequently asked questions
What is the definition of reader?
In this project a reader is a URL prefix, not an application you launch. Prepending https://r.jina.ai/ to any address returns that page as LLM friendly markdown, which is how the service describes its own read operation and the purpose of the library.
What are the two types of readers?
Two. Read through https://r.jina.ai/ converts a single URL, and Search through https://s.jina.ai/ searches the web, fetches the top 5 results, visits each URL and applies the read prefix to it, so a search returns page bodies instead of titles and descriptions.
What are reader types?
By input rather than by mode, Reader handles web pages rendered with headless Chrome or fetched with curl impersonate, PDFs parsed with PDF.js, Word, Excel and PowerPoint files converted through LibreOffice, and images captioned by a vision language model.
how to use reader
Prepend the prefix to your URL, or percent encode your query and prepend https://s.jina.ai/. The behavior is then tuned per request with headers such as x-respond-with for the output format, x-engine to force browser, curl or auto, x-cache-tolerance for acceptable staleness in seconds, and x-no-cache: true to bypass the 3600 second cache.
how to install reader
For the hosted prefixes there is nothing to install, you call the URL. To run the code yourself you need node >=22.15, build with the integrity check that precedes tsc, and start build/stand-alone/crawl.js, or build the node 24 image where npm ci runs in /app and the container starts the crawl entry point on port 8080.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jina-ai-reader)Star history chart for your README
[](https://hysenlabs.com/projects/jina-ai-reader)Was this useful?