Colibri: Running a 744B MoE Model on a 25GB-RAM Machine with Pure C and Disk Streaming
Run GLM-5.2 (744B MoE) on a 25GB-RAM consumer machine, pure C, zero deps, experts streamed from disk. Tiny engine, immense model.
At a glance
- What is it?
- Colibri is a zero-dependency C inference engine that treats VRAM, RAM, and storage as one hierarchy, letting you run GLM-5.2 (744B MoE) on consumer hardware. It prioritizes semantic fidelity over speed, but the performance claims remain unproven outside the project's own measurements.
- Who is it for?
- Adopt Colibri if you own a 25GB-RAM machine and want to run a 744B MoE model locally without renting cloud GPUs, and if you value semantic fidelity over speed. Do not adopt it if you need guaranteed throughput or production SLAs, as the project explicitly offers no speed guarantees.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
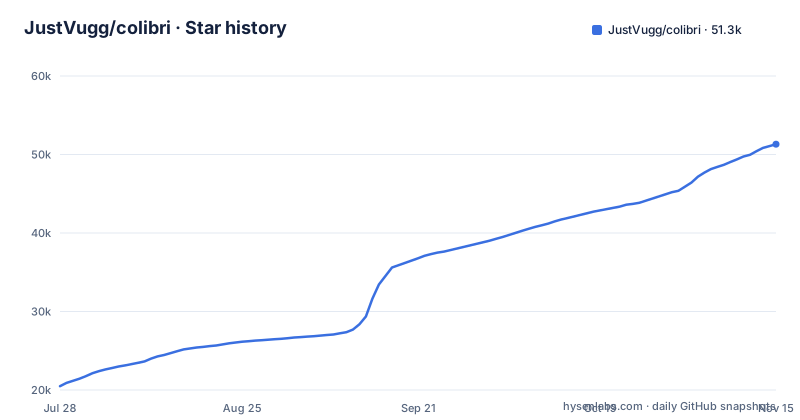
- JustVugg/colibri51,316 ★ · +30,826
| Repository | 2026-07-28 | 2026-11-15 |
|---|---|---|
| JustVugg/colibri | 20.5k | 51.3k |
30,826 Stars in the last 110 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Frontier Model Weights vs. Consumer Memory
A 744B-parameter mixture-of-experts model does not fit in a 25GB-RAM machine. Conventionally, you either rent a cloud instance with enough VRAM or settle for a smaller model. Colibri attacks that constraint directly: it treats storage, RAM, and VRAM as a single inference hierarchy, streaming experts from disk as needed. The README claims you can run GLM-5.2 (744B) on a 25GB-RAM consumer machine, with a resident footprint of 9.9GB after a 32-second startup. That is the core pitch: not renting intelligence behind an API, but holding it locally. The intended user is a developer or researcher who wants frontier-scale model access on hardware they already own, and who is willing to trade speed for that access. The project is explicit that there is no SLA on speed; the guarantee is semantic, not performance.
Mechanism: A Weight JIT with LRU, Pins, and Prefetch
Colibri does not load every expert into memory. Instead, a JIT for weights uses measured routing heat to drive a per-layer LRU cache, a learned pinned hot-store, and one-layer-ahead prefetch. The README states that this wins on repeatable workloads, but also that history can overfit and lookahead can lose on some hosts. So the caching policy is a measurable experiment, not a fixed promise. The engine also batches expert unions, overlaps reads with compute, uses O_DIRECT, and supports weighted dual-SSD striping. These are all attempts to treat I/O as part of the engine rather than pretending storage latency is free. The key design choice is that insufficient fast memory reduces speed but must not quietly redefine the model. The default policy never silently changes model precision or router semantics, and the project claims token-exact forward validation to keep optimizations tied to correctness.
Getting It Running: One Command, Multiple Front Ends
The README sets colibri up with a one-step script (START-HERE.bat on Windows, ./start-here.sh on Linux and macOS), and its example session `./coli chat` reports the version, model size, int4 quantization, and streaming CPU mode. The startup takes 32 seconds and the resident memory is 9.9GB. The setup starts colibri, opens a dashboard in your browser, and prints a browser address plus OpenAI and Anthropic base URLs for other apps. The dashboard displays live token metrics, a per-turn time breakdown, and a VRAM/RAM/disk tier bar. The project is pure C with zero engine dependencies, so the setup builds the engine for your machine when a compiler is present and otherwise downloads a prebuilt CPU/Vulkan engine; the README also links a documentation page for building from source details.
The Honest Limitations: Speed, O_DIRECT, and Overfitting
The most obvious limitation is speed. The speed on your machine is not guaranteed, and the bigger caveat is that the JIT's learned pins can overfit a prompt, and the one-layer-ahead prefetch can lose on some hosts. The README lists these as open hypotheses, not solved problems. O_DIRECT is drive-dependent, so your SSD may not support it, and the dual-SSD striping still needs broader end-to-end community A/Bs. If you have a single SSD or a drive that does not handle O_DIRECT well, the streaming path may degrade. The project also warns that the profitable combination of CPU, CUDA, Metal, NUMA memory, and expert residency depends on the machine, so there is no one-size-fits-all configuration. For a user expecting a plug-and-play experience, these caveats mean you must be prepared to experiment and measure.
The Research Mission: No Microbenchmark Worship
Colibri is not just a tool; it is an open research platform. The README states that nothing is adopted merely because a microbenchmark looks fast; the deciding result is end-to-end inference on real machines. That is a refreshing stance in a field full of cherry-picked numbers. The project maintains a table of open hypotheses, each with evidence and an experiment still needed. For example, routing history can place experts better than plain LRU, but evidence is limited to repeated workloads; a held-out cross-session A/B is needed. Similarly, multiple SSDs can turn independent bandwidth into decode speed, but a cold-cache one-drive vs two-drive GLM-5.2 run is missing. This means the project is explicitly a place to test aggressive systems ideas, and the authors are honest about what is proven and what is not. As a reviewer, I appreciate that the README does not overclaim; it frames every optimization as a hypothesis until a controlled A/B shows otherwise.
Alternatives: How Colibri Differs from llama.cpp and vLLM
The most common alternative for local LLM inference is llama.cpp, which also runs models in C/C++ on consumer hardware. The key difference is that llama.cpp typically loads weights into RAM or VRAM and the README does not compare colibri with it. Colibri's approach is fundamentally different: it treats storage as a first-class tier, with a JIT that predicts which experts to load next. Colibri's niche is the streaming, disk-backed inference for MoE models on low-memory hosts. If you have a single GPU with enough VRAM, llama.cpp may be simpler and faster. If you have a server cluster, vLLM is designed for that. Colibri is for the machine that is not enough for either, but you still want the frontier model.
Licence and Maintenance: Apache-2.0 with Active Releases
Colibri is licensed under Apache-2.0, which permits commercial use, modification, and distribution with attribution, and it does not impose copyleft obligations. The repository shows recent releases: v2.1.0 on 2026-10-31, v2.0.0 on 2026-10-06, and v1.12.1 on 2026-09-24. That is a rapid release cadence, with three versions in about five weeks. The project is not archived, and the default branch is main. The maintenance cost for a user is moderate: you will need to track releases because the project is evolving quickly, and the README notes that experiments can change behavior. The project's emphasis on correctness, such as token-exact forward validation, suggests that breaking changes are possible but should be documented. The licence is permissive, so you can integrate it into proprietary products, but you should verify the exact terms of Apache-2.0 for your use case, as I am not providing legal advice.
Editorial conclusion
Adopt Colibri if you own a 25GB-RAM machine and want to run a 744B MoE model locally without renting cloud GPUs, and if you value semantic fidelity over speed. Do not adopt it if you need guaranteed throughput or production SLAs, as the project explicitly offers no speed guarantees. Before committing, verify the token-exact forward validation on your specific model, test O_DIRECT on your SSD (it is drive-dependent), and run a cold-cache A/B on your storage to see if the streaming path holds up. Also check the latest release notes for any changes to the default precision policy, since the project promises it never silently changes model precision.
Frequently asked questions
how to install colibri ai
The README installs colibri with a one-step setup: after cloning the repository, run ./start-here.sh on Linux or macOS, or START-HERE.bat on Windows. The Python-facing package is colibri-engine, which requires Python 3.10 or newer and registers a console script named coli, so the chat front end can be started as ./coli chat, as in the README example.
how to use colibri
The README example starts a terminal chat with ./coli chat, while the one-step setup starts colibri and opens a browser dashboard, with OpenAI and Anthropic base URLs that other apps can use.
how to setup colibri
Setup is a guided script: after cloning, run ./start-here.sh on Linux or macOS, or START-HERE.bat on Windows. It looks at your RAM, free disk, CPU and GPUs, recommends a model that fits, builds or downloads the engine, downloads the model with resume, and starts colibri. Options such as --list, --model ID, --yes, --dir DIR and --backend vulkan, cuda or cpu go after the script name. A flake.nix and lock file are included for reproducible environments.
how to use colibri app
After the one-step setup, colibri starts and opens its dashboard in your browser at the address it prints (http://127.0.0.1:8000/ in the README example); c/coli status shows whether it runs and c/coli stop stops it.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Brio mode in Colibri: Scoring a closed set instead of generatingHacker News · Sep 21, 2026 · 1 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/justvugg-colibri)Star history chart for your README
[](https://hysenlabs.com/projects/justvugg-colibri)Was this useful?