Booth compiles a CUDA kernel to x86-64 with no GPU in the machine
Open-source CUDA, Triton and HIP compiler targeting multiple GPU and CPU architectures.
At a glance
- What is it?
- A C99 compiler that takes CUDA, HIP and Triton source and emits RDNA binaries, NVIDIA PTX, Tenstorrent Metalium, RV32IM or plain x86-64, built with a single make, by a Makefile that quietly drops -Werror the moment you name clang.
- Who is it for?
- Booth is worth a look if you want one kernel source to target hardware you do not own, since emitting runnable x86-64 or RDNA from a Triton file is the part no other tool in that list does. Two practical warnings.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 20 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
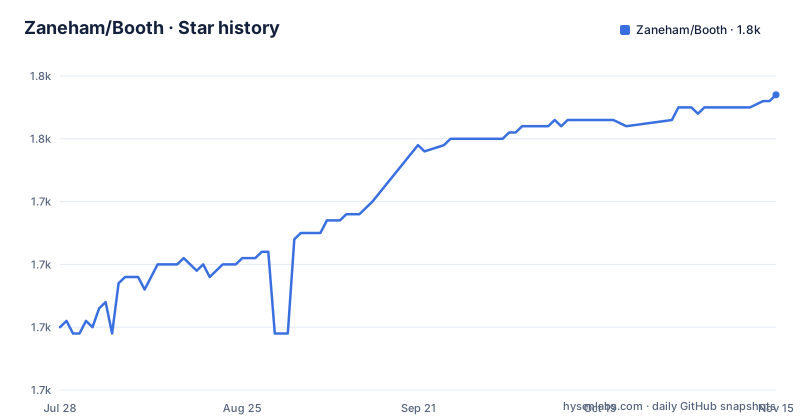
Star history
- Zaneham/Booth1,757 ★ · +37
| Repository | 2026-07-28 | 2026-11-15 |
|---|---|---|
| Zaneham/Booth | 1.7k | 1.8k |
37 Stars in the last 110 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The binary is kath, not booth, and a name collision follows
The compiler is installed as a binary called `kath`, and the README explains both halves of that decision. It is named for Kathleen Booth, to whom the project is dedicated: creator of the first assembly language, co-builder of the computer it first ran on, an early researcher into neural nets, a champion of women in computing, English by birth and Canadian by choice. The name is not `booth` because a `booth` binary already exists in the Linux high availability stack, so anyone installing this should expect both commands on their PATH. Getting a prebuilt copy needs no dependencies and no build step, for Linux, macOS or Windows:
tar xzf booth-*-linux-x86_64.tar.gz
cd booth-*-linux-x86_64
./kath --version
The same naming thread runs through the funding suggestion, which points at the Kate Edger Foundation, named for the first woman in New Zealand to earn a university degree.
Naming clang in CC silently drops -Werror from the build
The Makefile treats warning strictness as something that depends on the compiler rather than on the code, and the switch is easy to trip over. It probes the compiler by running the version command and grepping for clang, and on a hit it sets a variable to nothing at all. On gcc that variable expands to `-Werror -Wstack-usage=4096 -Wno-error=stack-usage= -Wredundant-decls`, so an error is an error and a stack frame over 4096 bytes is capped. On clang the entire set disappears, -Werror included, and the comment above the branch says the tree is not yet proven clean under that compiler, so the flag is dropped until it is. gcc builds, named for Linux and Windows under MinGW, are unchanged. The practical consequence is that two contributors on the same commit can get different verdicts from the same source, and that depends only on which compiler each of them put in CC.
The hardened link flags are marked Linux and ELF only
The compile flags are thorough and portable: a C99 standard, the usual warning set, plus -Wconversion, -Wswitch-enum, -Wwrite-strings, -D_FORTIFY_SOURCE=2, -fstack-protector-strong and -fPIE. Control-flow protection is not hardcoded either, since the Makefile compiles a throwaway program to see whether the compiler accepts the flag and echoes it only if it does. The link side is narrower. A comment marks the hardened options as Linux and ELF only: full relro, immediate binding, and a non-executable stack. Since the project also ships macOS and Windows builds, those two platforms link with `-pie` and `-lm` and nothing beyond that, with no equivalent protections added. LDFLAGS is a single flag for every target, so a binary built on a non-Linux host is not hardened in the way a Linux binary is, and nothing in the build output signals that difference. Probing for the flag also means a toolchain that quietly ignores unknown options omits the protection instead of failing the build.
Fifteen include paths are a map of the backends
One line of the Makefile lists fifteen include directories, and read in order they are a compact index of the project: src, src/fe for frontends, src/ir, src/tdf, src/backend, then one directory per target, src/amdgpu, src/tensix, src/nvidia, src/metal, src/intel, src/triton and src/cpu, and finally src/build, src/exec and runtime/include. The per-target directories line up with what the compiler claims to emit, AMD RDNA 2, 3 and 4 binaries, NVIDIA PTX, Tenstorrent Metalium C++, and native RV32IM or plain x86-64 from the CPU path. The same split shows up in the examples directory, which holds separate launchers for a CPU vector add, a CPU matmul, a saxpy, a Tensix launch named for the Koyeb platform, and a set of sysprint files. The top-level tree keeps a standalone mfrg.s, an assembly file sitting beside the C sources.
47 of ggml-cuda's kernels reach the new SASS backend
The update note at the top of the README is the most concrete evidence of scale in the project, and it is also the most precisely scoped. ggml-cuda, the CUDA half of llama.cpp, now lowers: all 67 of its files reach Booth's intermediate representation, and 47 of its kernels go through a new native SASS backend that writes a cubin the card loads directly. Until that backend existed, targeting NVIDIA meant emitting PTX and letting the driver's JIT handle it. The 47 out of 67 figure is the part worth holding onto, because it means the file coverage is complete while the kernel coverage is not, so a llama.cpp workload can contain a kernel the new path has not been exercised on. The path can be tried directly with the `--nvidia-cubin` flag on the `kath` binary, and the running log of what else changed is kept in CHANGELOG.md.
Both frontends read another compiler's output and neither is needed to build
Building Booth is one command and one prerequisite. `make` is the whole build, and the only requirement is a C99 compiler, gcc or clang or whatever is already installed. Two optional frontends exist, and both are second-hand in an interesting way: each reads what a different compiler produced rather than parsing a language itself. Fortran `do concurrent` kernels go through LFortran, which emits CUDA source that Booth then compiles the rest of the way, and those results are checked against SLATEC values in CI. OCaml kernels are written as plain functions, type-checked by `ocamlc` before Booth reads the type-checked output, which needs OCaml 5.x and dune. The compiled artefacts are produced by commands like these:
# compile a CUDA kernel to an AMD GPU binary
./kath --amdgpu-bin kernel.cu -o kernel.hsaco

# or compile and run it on whatever device you have, in one command
./kath run kernel.cu

# see what your machine can do, then self-test it
./kath doctor
Coverage builds re-invoke make with a flag set that lands after the optimisation level, so the instrumented build wins over the normal one.
The documentation publishes what does not compile yet
A compiler at this stage usually hides its gaps, and this one lists them. The documentation set includes a feature status page described as what compiles today and what does not yet, a hardware page listing the silicon it has been tested on along with the test suite, a usage reference for every backend and flag, a CMake page, a roadmap, and a mainframe page. That last one covers the operational habits the author borrowed from big iron: real crash dumps when a kernel faults, output structured by class, and parameter snapshots taken on entry, under the headings ABEND dumps, SNAP, SYSPRINT and TDF. The examples carry the same idea, with launch_sysprint.c, sysprint_classes.h, sysprint_kernel.cu and launch_saxpy.c sitting next to the CPU launchers. The tested-hardware list and the feature status page are the two files to read before depending on a specific backend, since they say what works and on what rather than what is planned.
Editorial conclusion
Booth is worth a look if you want one kernel source to target hardware you do not own, since emitting runnable x86-64 or RDNA from a Triton file is the part no other tool in that list does. Two practical warnings. Build strictness is not a property of the project but of the compiler you name, because choosing clang empties the variable that carries -Werror and the stack-usage cap, so a clang build passes warnings a gcc build would reject. And the hardened linker flags are marked Linux and ELF only, so the macOS and Windows builds do not get them. The documentation is unusually candid for a compiler at this stage, publishing both what does not compile yet and the exact silicon it has been tested on, and that is where you should start before depending on a backend.
Frequently asked questions
What is the Booth compiler and what can it emit?
An open-source compiler that takes CUDA C, HIP or Triton source, the same files you would hand to nvcc, ROCm or Triton's JIT, and emits AMD RDNA 2, 3 and 4 binaries, NVIDIA PTX, Tenstorrent Metalium C++, native RV32IM, or plain x86-64 that runs on a laptop with no GPU in it.
What is the Booth compiler binary actually called?
kath, not booth. It is named for Kathleen Booth, and the README says it avoided the shorter name because a `booth` binary already exists in the Linux high availability stack, so both may end up on your PATH.
What do I need to build Booth from source?
A C99 compiler, either gcc or clang, and nothing else. The build is a single `make`. LFortran and OCaml 5.x with dune are only needed for their own frontends, because those frontends read the output of another compiler rather than parsing the languages themselves.
How does Booth handle a kernel that faults?
It borrows mainframe habits, producing real crash dumps on a fault, routing structured output by class, and snapshotting parameters on entry. The documentation covers ABEND dumps, SNAP, SYSPRINT and TDF, and the examples include launch_sysprint.c and sysprint_kernel.cu.
Does NVIDIA support in Booth go through PTX and driver JIT?
Not any more. The newest release notes that ggml-cuda now lowers through Booth's intermediate representation, with 47 of its kernels going through a native SASS backend that writes a cubin the card loads directly, replacing the PTX and driver JIT path. It can be tried with the `--nvidia-cubin` flag.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zaneham-booth)Star history chart for your README
[](https://hysenlabs.com/projects/zaneham-booth)Was this useful?