tensai: a pure-Go neural network framework that trades size for reach
A tiny neural-network framework in pure Go with AVX2 SIMD kernels (GOEXPERIMENT=simd)
At a glance
- What is it?
- mattn/tensai is a small, dependency-free ML framework that covers training, inference, and model interchange. Its AVX2 kernels and format support make it worth a look for Go engineers, but its experimental foundations need scrutiny.
- Who is it for?
- Adopt tensai if you want a self-contained Go ML stack for learning, experiments, or small inference jobs, and you can tolerate an experimental SIMD path and a young API. Do not adopt it for production training at scale, for non-amd64 performance, or if you need a stable API across versions.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
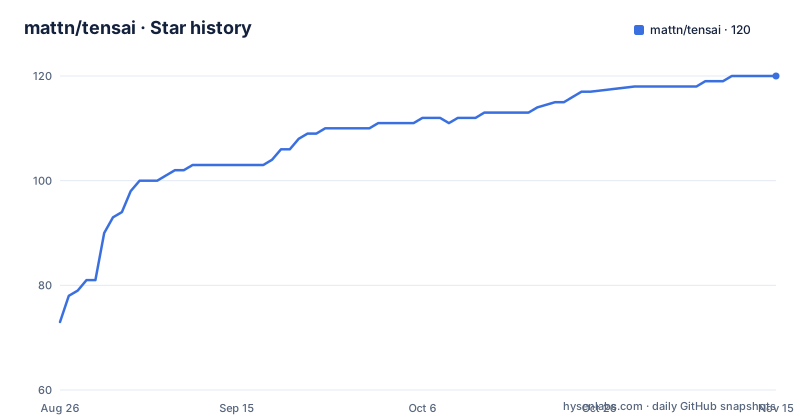
Star history
- mattn/tensai120 ★ · +47
| Repository | 2026-08-26 | 2026-11-15 |
|---|---|---|
| mattn/tensai | 73 | 120 |
47 Stars in the last 81 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What tensai actually is
tensai is a machine-learning framework that fits in a small Go module. It implements forward passes, backpropagation, and optimization without cgo or assembly files. The default build has zero external dependencies. That is rare for an ML project, and it is the first thing to understand about this library. The author, mattn, is known for small Go utilities, and tensai follows that pattern. It is not a TensorFlow clone. It is a toolkit for people who want to train small networks or run inference in Go without dragging in a C runtime. The README says it is for learning and experiments. That is an honest scope, and the design choices reflect it. The core types are float32 matrices and tensors. There is no float64 path, no GPU memory management outside the optional wgpu backend, and no distributed training. If you need those, stop here. If you need a compact, readable ML library that runs anywhere Go runs, keep reading.
The SIMD path: GOEXPERIMENT=simd and AVX2
The performance story hinges on Go's experimental simd package. The README states that AVX2 kernels are written with the simd/archsimd package, still pure Go, no cgo, no assembly. This is unusual. Most SIMD in Go means either cgo or hand-written .s files. tensai instead relies on Go 1.26 and 1.27's experimental simd support, selected via build tags. The vectorized operations cover matmul, ReLU, sigmoid, tanh, softmax, GELU, LayerNorm, and the Adam update. All are 8-lane. On amd64 with GOEXPERIMENT=simd, you get these kernels. Every other build falls back to portable code automatically. That fallback is a safety net, but it also means the performance advantage disappears on ARM, on older amd64 CPUs without AVX2, or if you forget the build flag. The README gives one concrete number: the quantized int8 dot product reaches about 31GB/s of weights on 16 cores. That is a single measurement, not a benchmark suite. Treat it as indicative, not a promise. The experimental nature of the SIMD API is a real risk. Go's simd package may change or be removed. tensai's build tags try to cover both 1.26 and 1.27 APIs, which helps, but it is still a moving target.
Getting it running: build flags and a first model
The README shows a minimal regression example. You create a Sequential model, add a Dense layer with 8 units, a Tanh activation, another Dense with 1 unit, and a Sigmoid. Then you call Compile with 2 input features, MeanSquaredError, and an Adam optimizer at learning rate 0.05. Fit runs 5000 steps, and Predict returns the output. The code is straightforward. To get the SIMD kernels, you build with GOEXPERIMENT=simd on amd64. For the WebGPU backend, you add -tags wgpu, and the only dependency is ebitengine/purego, which is cgo-free. The wgpu-native shared library is dlopen-ed at runtime, so you need that library present on the system. The module path is github.com/mattn/tensai, and the license is MIT. There are no other setup steps. The tokenizer package loads Hugging Face tokenizer.json files, and the encoding packages read and write TFLite, safetensors, GGUF, and ONNX. Each of those is dependency-free, which is a strong claim and a strong constraint. The trade-off is that the implementations are hand-written, so they cover a specific subset of each format. For example, the ONNX exporter writes opset 13 FP32 only. That is enough for many cases, but not all.
The format support is the differentiator
Most small ML frameworks in Go stop at training and inference. tensai goes further. The encoding/tflite package writes .tflite flatbuffers that run on TFLite and go-tflite. The encoding/safetensors package reads the checkpoint format used by many published models, lazily, one tensor at a time, with F16/BF16/F64 converted to float32. The encoding/gguf package reads llama.cpp's model container, including block-quantized types like Q8_0, Q4_0, Q4_1, Q5_0, Q5_1, the K-quants Q2_K through Q6_K, IQ4_NL, and MXFP4. The README claims the GGUF support is verified block-exact against real llama.cpp conversions. That is a concrete, testable claim. The ONNX exporter produces opset 13 FP32 and the README says onnxruntime reproduces Predict to about 1e-7 relative error. These claims give the library real interoperability value. You can train a small model in tensai, export it to TFLite or ONNX, and deploy it elsewhere. Or you can load a GGUF model and run inference. The tokenizer package handles byte-level BPE families and SentencePiece, with encodings matching the reference tokenizers library exactly. This is the most useful part of the project for practical work. It turns tensai from a toy into a bridge between Go and the wider ML ecosystem.
Where it breaks: quantization and the WebGPU gamble
The quantization story is impressive on paper but carries caveats. The int8 path is a full integer dot product with activations dynamically quantized to 7 bits. The int4 path is group-wise with float32 accumulation. The README says int4 halves the weights again, and the difference between a 7B model fitting in RAM or not. That is a concrete motivation, but it is also a trap. Loading a 7B GGUF model into tensai means you need enough RAM, and the inference speed depends on the SIMD kernels being active. Without GOEXPERIMENT=simd, the portable fallback will be slow. The WebGPU backend is experimental. It runs batched MatMul as a WGSL compute shader on Vulkan, Metal, or D3D12. The bindings go through purego, so no cgo, but you still need the wgpu-native shared library. That is a runtime dependency that can break on different systems. The README does not list which GPU vendors are tested. It says AMD, Intel, Apple, NVIDIA, which covers most hardware, but driver issues are common. If you rely on this backend for production, you are betting on an experimental path. The autograd engine is micrograd-style, which means it is simple and readable, but it is not designed for large graphs. The rnn and attention cells are built on it, so they inherit that simplicity. For serious sequence modeling, you would want a more optimized implementation.
Alternatives: what else is out there
The most direct alternative is Gorgonia, a mature Go ML library that has been around for years. Gorgonia uses a computational graph and supports CUDA via cgo. It is heavier, has more dependencies, and its API is more complex. tensai's selling point is the opposite: zero dependencies, a simpler API, and modern format support. Another alternative is to skip Go entirely and use Python with PyTorch or TensorFlow. That is the pragmatic choice for most ML work, but it loses the single-binary deployment that Go offers. A third option is to use a C library like llama.cpp directly via cgo. That gives you performance and broad model support, but you are back to cgo and a C build chain. tensai sits in a niche: pure Go, no cgo, with enough format support to be useful. For a Go engineer who wants to embed a small model in a service without a sidecar process, tensai is a credible option. The trade-off is that you are betting on a project that is young, with a version number at v0.0.12, and an experimental SIMD foundation. Gorgonia has more users and a longer history, but it is not as clean for modern formats. The right choice depends on whether you value dependency-free builds or ecosystem maturity.
Maintenance and upgrade costs
The project is actively maintained, with the latest release v0.0.12 pushed on 2026-08-28, and several releases in the same week. That suggests rapid iteration, which is good for bug fixes but bad for stability. The API is not yet version 1.0, so breaking changes are possible. The README does not mention a migration guide. The dependency on GOEXPERIMENT=simd means you must track Go releases. The build tags support Go 1.26 and 1.27, but when Go 1.28 arrives, you may need to update the tags. The wgpu backend depends on a shared library that is not version-pinned in the README. The license is MIT, which is permissive, but you should read the license file yourself for any legal questions. The serialization format is JSON, which is simple but not compact. For large models, that could be slow. The safetensors and GGUF readers are lazy, which helps with memory, but the writers only produce F32, so you cannot save quantized models directly. That is a real limitation if you want to train and then quantize in place. You would need to export to a format and then use another tool to quantize. The README does not mention a quantization-aware training path. Maintenance cost is low for a small project, but the experimental features add risk. You should pin the version you use and test upgrades carefully.
Editorial conclusion
Adopt tensai if you want a self-contained Go ML stack for learning, experiments, or small inference jobs, and you can tolerate an experimental SIMD path and a young API. Do not adopt it for production training at scale, for non-amd64 performance, or if you need a stable API across versions. Before committing, verify the GOEXPERIMENT=simd build on your Go toolchain, test the wgpu backend on your GPU, and check that the quantized GGUF path meets your accuracy needs.
Frequently asked questions
What does the tensai framework do?
It implements forward passes, backpropagation and optimization in pure Go for learning and experiments. Layers include Embedding, Dense, Conv2D, MaxPool2D, BatchNorm, LayerNorm and Dropout, with MeanSquaredError, SoftmaxCrossEntropy and BinaryCrossEntropy losses and SGD, Adam and AdamW optimizers.
How do I enable SIMD acceleration in tensai?
Build with GOEXPERIMENT=simd, which needs Go 1.26 or 1.27 on amd64, or Go 1.27 on arm64 since that is the first release whose simd/archsimd has an arm64 half. Any other build uses the portable fallbacks automatically and produces identical results.
Does tensai have any external Go dependencies?
The default build has none. The optional wgpu build tag adds exactly one, ebitengine/purego, and it is cgo-free because the wgpu-native shared library is dlopen-ed at runtime. go.mod declares go 1.22 and requires only that package.
How do I run a tensai model on a GPU?
Build with -tags wgpu, which works on Linux, macOS and Windows, and reaches anything wgpu-native supports including Vulkan, Metal and D3D12. UseAccelerator moves products above 4e8 multiply-accumulates onto the device, and tape.UseDevice keeps values, gradients and the Adam update resident there.
Can tensai run a Docker image model or understand audio?
Yes. tensai image runs Qwen-Image-2.1 end to end, and tensai audio runs Qwen2-Audio-7B-Instruct, both in pure Go. The image path quantizes weights as they load, giving 7GB at eight bits and 3.5GB at four, and a 256x256 picture takes under four minutes on a laptop.
What version of tensai should I depend on?
The releases follow the v0.0.x line, currently around v0.0.33. go.mod retracts v0.1.0 and v0.1.1, with a comment saying v0.1.0 was tagged in error before the package split, so those two versions are not usable.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mattn-tensai)Star history chart for your README
[](https://hysenlabs.com/projects/mattn-tensai)Was this useful?