Memmy Agent: a local memory hub shared across Claude Code, Codex and other CLI agents
🍙 A personal AI agent & local memory hub for all AI agents, gives every AI one shared, fully controlled memory and persistent context — all AI remember the same you. Now supports Claude Code, Codex, OpenClaw and Hermes Agent etc.
At a glance
- What is it?
- Memmy is a TypeScript personal AI agent that runs a local memory service on port 18960 and a gateway on 18990, so Claude Code, Codex, Cursor and similar tools read and write one shared context. The design is opinionated about where memory lives and how agents get wired into it.
- Who is it for?
- Adopt Memmy if you already switch between two or more CLI agents on the same codebase and want their context to live in one local store you control, and if you are willing to run two systemd user services to get it. Do not adopt it if you work inside a single agent, if you need the memory layer to be portable to a remote or team-shared backend, or if your environment has no systemd user session, since the documented Linux path depends on one.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
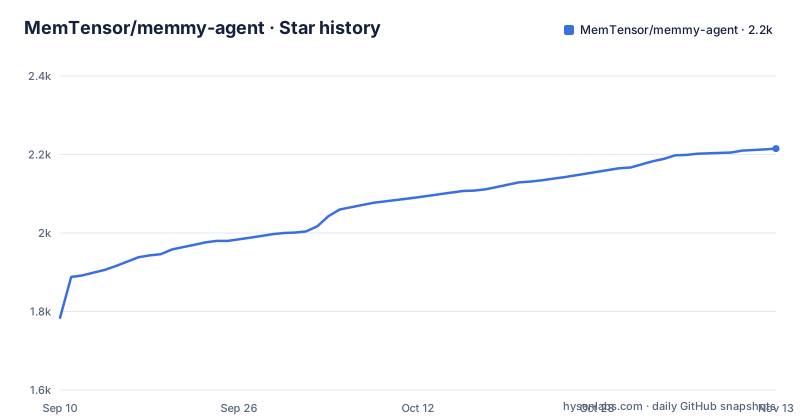
- MemTensor/memmy-agent2,215 ★ · +431
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| MemTensor/memmy-agent | 1.8k | 2.2k |
431 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Memmy targets: context that dies with the tool
Every CLI coding agent keeps its own history. Claude Code has one notion of your project, Codex has another, Cursor a third. Move a task between them and the background has to be retyped. Memmy's README frames this as three verbs shown as cards on the project page: Remember, Relay and Act. Remember means the tool turns your local AI collaboration history into structured memory. Relay means switching tools without losing context, carrying project background, preferences and progress forward. Act means Memmy is itself an agent that can organize information and continue unfinished tasks. The audience is the person who runs more than one agent against the same repository and is tired of re-explaining the same constraints. It is not aimed at a team sharing a cloud knowledge base, and nothing in the README suggests a hosted multi-tenant memory backend. The scope is explicitly personal: the tagline is that every AI remembers the same you.
Two local services, one memory store, and an OpenAI-compatible endpoint
The architecture visible in the README is a pair of localhost services plus clients. The memory service listens on http://127.0.0.1:18960 by default, and the memmy-memory CLI talks to it with commands like init, health, search, add and get. The gateway is a separate process, and memmy serve exposes an OpenAI-compatible API on port 18990. The TUI, the desktop app and third-party agents are all clients of that pair. The integration story is a Memory Skill plus a supported Hook or plugin per agent, installed by memmy-memory init for all detected agents or memmy-memory init --agent <agent> for one. That distinction matters: installing Memmy does not rewrite your Codex or Claude Code configuration. The README states plainly that the installer initializes Memory without changing those tools, and that you opt in per agent. The README lists DeepSeek Harness, OpenClaw, Hermes, Claude Code, Codex, Cursor, WorkBuddy, OpenCode and Pi as connectable. Namespacing is handled through flags on the memory CLI: --source and --user-id select the namespace, while --url, --token and --config point the client at a different service. That is the whole data flow as documented: agents write through the skill or hook, the memory service stores and searches, and any other connected agent can read the same store.
Installing on Linux: the installer owns two systemd user services
The documented Linux path assumes x64 or arm64, Node.js 22 or newer, and an available systemd user session. The install is a single curl piped to bash from scripts/install.sh, followed by a bare memmy. The installer enables the local Memory Service immediately as memmy-memory.service. The first bare memmy invocation opens the model setup wizard when needed, then enables memmy-gateway.service, waits for it to become ready, and enters the TUI. Both units are systemd --user services bound to localhost and survive the TUI or terminal exiting. They restart on later logins, but the installer does not enable linger, so they do not come back after a reboot until you log in. You can check them with systemctl --user status memmy-memory.service and systemctl --user status memmy-gateway.service. One detail worth reading twice: before starting or reconnecting to the Gateway, memmy refreshes a private ~/.memmy/systemd/gateway.env file in mode 0600 with configuration-referenced environment variables, common Provider credentials, and the terminal PATH. If those values change, the next bare memmy restarts the user service with the new environment. Credentials therefore live in a file on disk, not only in your shell. The README also notes that only the installer launcher activates this service management, so a source-built Linux CLI keeps its existing behavior.
Configuration, BYOK and the commands you actually type
The minimal bring-your-own-key configuration sits at ~/.memmy/config.yaml and is short enough to quote in full from the README: an agents.defaults block with model, provider and timezone, and a providers block where openai.apiKey reads ${OPENAI_API_KEY}. The timezone field is a string like "+08:00", so it is an offset, not an IANA zone name. memmy onboard configures models, providers, gateway, memory and tools interactively, and memmy onboard --defaults initializes the config file and workspace with defaults. memmy status reports the configuration, model and provider. memmy agent --message "..." runs a single-turn task, and a bare memmy enters the TUI. The memory side has its own CLI: memmy-memory init, health, search "...", add "..." and get <id>. From source, the sequence is git clone, cp .env.example .env, npm install, npm run build, then bash scripts/dev-start.sh. Treat the dev script's full behavior as unverified. The same applies to the desktop app: the README points to the official site and GitHub Releases and describes a first scan and a first meeting report, but the concrete GUI steps live in the Getting Started guide rather than the README.
Where Memmy gets in the way
The strongest constraint is the platform assumption. The CLI installation instructions name Linux with systemd, and the service management described is systemd --user specific. If you develop on a Mac and want the memory service running as a background daemon, you are outside the documented path. The second constraint is the credential file. Writing provider keys and PATH into ~/.memmy/systemd/gateway.env is convenient and the mode is restrictive, but it duplicates secrets that may already live in a keychain or a shell profile, and it gives you a second place to rotate them. The third is the opt-in integration model. Because the installer does not touch your agents, a fresh install gives you a memory service and a gateway that no agent is using until you run memmy-memory init, and a skill or hook that an upstream agent changes can break the connection without Memmy noticing. The fourth is the trial credit model: the README says registration grants Agent task trial tokens and that you switch to BYOK when they run out, so the default experience involves an account and an external service even though the memory store itself is local. The README does not describe what data, if any, leaves the machine during that trial.
The alternative: per-agent memory files versus a shared service
The obvious alternative is what most people do today, which is each agent's own project memory: CLAUDE.md and similar instruction files for Claude Code, AGENTS.md or equivalent for Codex, and editor rules for Cursor. The difference is architectural, not cosmetic. Those files are plain text committed next to the code, read at session start, and edited by hand. They are portable, diffable, reviewable in a pull request, and shared with your team for free. They also do not accumulate: nothing writes back to them automatically, and a fact learned in one agent's session does not appear in another's. Memmy inverts both properties. Memory is written and searched through a service over HTTP, which means it can grow without anyone editing a file, and every connected agent sees the same store. The cost is that the memory is now a running process with a port, a config file and a credential file, and it is not something a teammate gets by cloning the repository. If your team already reviews agent instructions in version control, that workflow does not survive the move to a local service. Memmy and the file-based approach can coexist, but they will diverge, and the README does not describe any export from the memory store back into a committed file.
Maintenance, release cadence and what MIT means here
The release history shows v1.1.2 on 2026-09-04, v1.1.3 on 2026-09-08 and v1.1.4 on 2026-09-09, with the last push to main on the same day as v1.1.4. That is a fast patch cadence, and it tells you the project is moving, but it also means the surface you integrate against can shift between minor versions. The integration points are the ones to watch: the memory service HTTP API on 18960, the OpenAI-compatible endpoint on 18990, the config schema in ~/.memmy/config.yaml, and the skill or hook installed per agent. A change to any of those is what turns an upgrade into work. The project is MIT licensed, which in practice means you can read, modify and redistribute the source, including in commercial settings, provided the licence text and copyright notice travel with it. That is a statement about the repository's licence file, not legal advice, and it says nothing about the hosted service behind the trial credits or the memmy.bot documentation site, which are separate from the code. If you need a guarantee that the memory format stays stable, the licence gives you the right to fork and maintain it yourself, which is the only guarantee an MIT project can offer.
Editorial conclusion
Adopt Memmy if you already switch between two or more CLI agents on the same codebase and want their context to live in one local store you control, and if you are willing to run two systemd user services to get it. Do not adopt it if you work inside a single agent, if you need the memory layer to be portable to a remote or team-shared backend, or if your environment has no systemd user session, since the documented Linux path depends on one. Before installing, verify three things: that your Node.js is 22 or newer, that you are comfortable with the installer writing a private ~/.memmy/systemd/gateway.env in mode 0600 containing provider credentials and your PATH, and that you have read the Getting Started guide at memmy.bot/docs for the desktop app, because the README covers the CLI path far more completely than the GUI one.
Frequently asked questions
What is memmy?
Memmy is a local memory hub that gives several coding agents one shared memory and persistent context. It ships as a desktop app, a CLI with a TUI backed by two systemd user services, a standalone memory CLI that talks to the local memory service on port 18960, and a source build.
How does AI agent memory work?
This repository implements it as a local service an agent calls rather than as model state. The memory CLI exposes init, health, search, add and get against a service on 127.0.0.1:18960, and a memory skill plus a supported hook or plugin can be installed per agent so that agent reads and writes the same store.
Which coding agents can Memmy connect to?
The page names DeepSeek Harness, OpenClaw, Hermes, Claude Code, Codex, Cursor, WorkBuddy, OpenCode and Pi, and says they all work. The agent modification is opt-in: the installer initialises Memory without changing any agent, and installing the memory skill and hook happens only when you run the memory init command for all detected agents or for one named agent.
Where does Memmy store its configuration?
The minimal bring-your-own-key configuration lives at ~/.memmy/config.yaml and can be initialised with defaults by the onboard command. Before the gateway starts, the CLI also refreshes a private file at ~/.memmy/systemd/gateway.env with mode 0600 containing referenced environment variables, provider credentials and the terminal PATH.
Does Memmy need an account to use it?
The desktop app is the recommended path and the page says signing up grants Agent task trial tokens, with the balance shown in the app, after which you switch to bring-your-own-key mode and use your own model API. The CLI, the memory CLI and the source build are documented without an account requirement.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/memtensor-memmy-agent)Star history chart for your README
[](https://hysenlabs.com/projects/memtensor-memmy-agent)Was this useful?