FLAML trades a full AutoML pipeline for a tuning call you can wrap around your own function
A fast library for AutoML and tuning. Join our Discord: https://discord.gg/Cppx2vSPVP.
At a glance
- What is it?
- FLAML is a lightweight Python library from Microsoft that does two separable jobs: task-oriented AutoML with a scikit-learn shaped estimator, and generic tuning of an arbitrary Python function under a time budget. The tuning half is the part most teams never discover.
- Who is it for?
- Adopt FLAML when your bottleneck is search cost, or when you have one expensive callable to tune and can live with a single NumPy base dependency. Do not adopt it if your interpreter sits outside the supported range.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
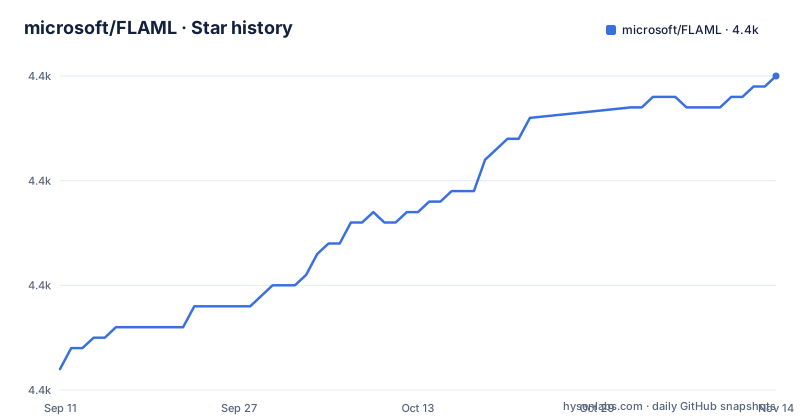
- microsoft/FLAML4,420 ★ · +28
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| microsoft/FLAML | 4.4k | 4.4k |
28 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two entry points that share one search engine
FLAML presents itself as AutoML, and its most quoted entry point is the AutoML class. Read the quickstart further and a second entry point appears, the tune module, applied to an evaluation_function with a config and a low_cost_partial_config.
That distinction decides who finds FLAML useful. If your problem is a table plus a target column, AutoML with a classification task fits. If your problem is a simulation, a prompt template, a threshold schedule or a rendering layout that costs money to evaluate, the tune path fits and the AutoML framing gets in the way. The README's own summary makes this split explicit, listing inference hyperparameters for foundation models, MLOps and LMOps configurations, pipelines, mathematical and statistical models, algorithms, computing experiments and software configurations as tuning targets.
The audience, then, is not only data scientists hunting an accuracy number. It is engineers who have one expensive callable and need its parameters chosen before a deadline.
A scikit-learn shape with no hidden preprocessing
The quickstart is three lines, and that brevity is the design:
from flaml import AutoML

automl = AutoML()
automl.fit(X_train, y_train, task="classification")
The library is also deliberately thin at install time. pyproject.toml lists exactly one hard dependency, NumPy>=1.17, and the default pip install flaml pulls in nothing else. Everything with real weight sits behind extras, so the cost of trying the library is close to the cost of a NumPy install.
Extras decide what you can actually search over
The optional dependency groups in pyproject.toml map directly onto what the search can touch. The automl extra brings in lightgbm, xgboost, scipy, pandas and scikit-learn. The notebook extra adds jupyter. A spark extra pins pyspark, joblibspark and holds joblib at or below 1.3.2 while keeping pandas below 3.0.
Those pins are where installation surprises live. The spark group deliberately caps joblib and pandas, so a Spark user arriving with newer versions of either will see pip resolve backwards. The test group is stranger still: it marks thop as available only when the platform is not Windows on ARM64, and switches numpy to a different constraint on Python 3.13.
Install the group you need:
pip install "flaml[automl]"Estimator lists are a hard boundary on the search space
Passing a single-entry estimator list narrows the search to one learner, and FLAML frames this as a mode rather than a filter: use it as a fast hyperparameter tuning tool for XGBoost, LightGBM, Random Forest or a customised learner. With a single-entry list, model selection is restricted to that family and FLAML tunes within it. A list with multiple entries still allows selection among the listed families.
For most production work that is the right division. A default full sweep spends its budget comparing learner families, and on a narrow dataset with noisy signal that comparison often wastes the budget on a model you will not ship. Naming one family buys more configurations per learner.
The reverse is the failure mode. If you pick a family whose default configuration cannot represent your problem at all, no amount of search recovers it, and the result looks like a tuning failure rather than a modelling error. Check what the learner expects before blaming the search.
Time budget beats iteration count, and that is the contract
The tuning example hands the scheduler an hour and stops:
tune.run(
    evaluation_function, config={...}, low_cost_partial_config={...}, time_budget_s=3600
)
Heterogeneous cost is the part with real teeth. When one trial takes a second and another takes twenty minutes, a fixed iteration count spends almost all its wall clock on the expensive tail. A time budget keeps the schedule tied to the clock.
The partial config argument is the companion knob.
The constraint cuts the other way too. Budget-based search has no notion of a correct iteration count, so the same code can evaluate a different set or number of trials as machine load and trial durations vary, and may return a different answer. Record the budget and the machine with any result you intend to compare.
Zero-shot wrappers borrow an existing training API
The flaml.default module ships drop-in replacements for familiar estimators, and the comment in the example says it plainly: use LGBMRegressor the same way as you use lightgbm.LGBMRegressor.
from flaml.default import LGBMRegressor

estimator = LGBMRegressor()
estimator.fit(X_train, y_train)
Nothing in your training script changes. That is the entire appeal for teams that already have a working LightGBM pipeline and no appetite for a rewrite.
It is also the narrowest surface in the library. Zero-shot adaptation means the search space is whatever FLAML already knows how to set for that estimator, not the space you would define yourself. If you want to guide it, you have left zero-shot mode and gone back to writing a search space by hand.
One detail changes for anyone arriving from older documentation: the autogen module is gone, and the README points users at the standalone AutoGen repository instead. Code that imported autogen through FLAML breaks on upgrade rather than degrading.
Where Optuna and AutoGluon draw the line differently
AutoGluon builds a full modelling stack for tabular data, handling ensembling and its own preprocessing, and returns a fitted predictor rather than a search trajectory. If you want the shortest path from a DataFrame to a stacked predictor, AutoGluon removes more work from you. If you need to control every preprocessing step or drop into the middle of the loop, the smaller surface is the point.
Against Optuna the difference is narrower and more interesting. FLAML's tune.run owns the schedule, takes a wall clock budget as a first class argument, and asks for an evaluation_function rather than a set of parameter distributions. The trade is real either way: Optuna gives you fine grained control over the search algorithm, FLAML gives you a budget without requiring you to implement the accounting.
Python 3.14 falls outside the supported range
The README states that the latest version requires Python >= 3.10 and < 3.14, and that while other Python versions may work for core components, full model support is not guaranteed. pyproject.toml sets the same lower bound and lists classifiers only through 3.13. On 3.14 you can install and run parts of it, and you are outside the tested set.
The one argument worth making about upkeep: the repository's last push was on 2026-11-02. The licence is MIT and setup.py is a bare call into setuptools, so vendoring and forking stay cheap.
Editorial conclusion
Adopt FLAML when your bottleneck is search cost, or when you have one expensive callable to tune and can live with a single NumPy base dependency. Do not adopt it if your interpreter sits outside the supported range. Before anything else, check that the estimator you want actually appears in the search space, and that your own evaluation function returns a cost FLAML can minimise, since a badly chosen family or a badly scaled metric will read as a tuning failure rather than a modelling error.
Frequently asked questions
What is FLAML?
FLAML is a lightweight Python library from Microsoft for automating machine learning and tuning. It offers a scikit-learn styled AutoML estimator and a generic tuning entry point for user-defined functions, with NumPy as its only required dependency.
How do I install FLAML for AutoML?
The base install is a plain pip install of flaml, which pulls in only NumPy. Model search needs the automl extra, which brings in lightgbm, xgboost, scipy, pandas and scikit-learn.
Does FLAML still ship the autogen module?
No. The README states that AutoGen has moved to a dedicated repository and that FLAML no longer includes the autogen module, so imports of autogen through FLAML will fail after upgrading.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-flaml)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-flaml)Was this useful?