SynapseML: Distributed Machine Learning That Stays Inside Your Spark Pipeline
Simple and Distributed Machine Learning
At a glance
- What is it?
- SynapseML brings text analytics, vision, anomaly detection, and more into Apache Spark as composable estimators. It is a practical choice for teams already on Spark, but its Microsoft-centric features and version-specific artifacts require careful setup.
- Who is it for?
- Adopt SynapseML if your team already runs Apache Spark and needs distributed, composable ML for text, vision, or anomaly detection without leaving the SparkML API. Skip it if you are not on Spark, need a pure Python ML stack, or want to avoid Microsoft-specific services like Cognitive Services.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
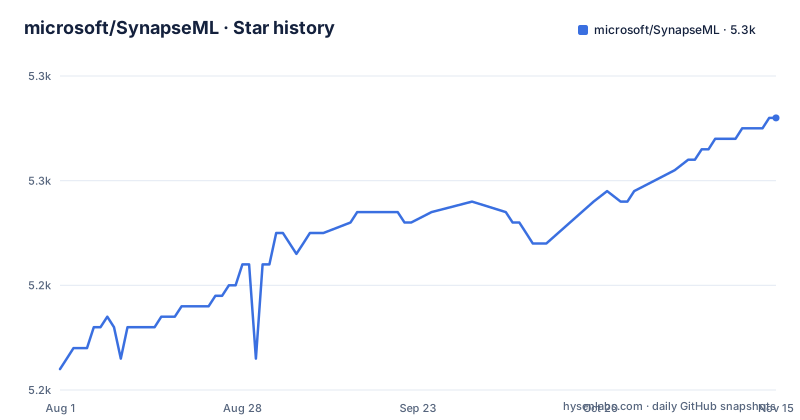
Star history
- microsoft/SynapseML5,256 ★ · +24
| Repository | 2026-08-01 | 2026-11-15 |
|---|---|---|
| microsoft/SynapseML | 5.2k | 5.3k |
24 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem SynapseML Solves
SynapseML provides distributed APIs for tasks like text analytics, computer vision, and anomaly detection, all expressed in the same SparkML style. The intended user is a data engineer or data scientist who already lives inside Spark notebooks and wants to add these capabilities without building custom wrappers or moving data to a separate system. The README's promise is simple: 'simple, composable, and distributed APIs.' That is a direct answer to the friction of gluing external ML libraries into Spark pipelines.
How It Works: Composability on the SparkML API
SynapseML is built on Apache Spark and shares the API of SparkML/MLLib. That means models appear as transformers and estimators that fit into existing Pipeline objects. The library abstracts over databases, file systems, and cloud data stores, so a pipeline written locally can run on a cluster without rewriting data access. The key architectural move is to expose distributed implementations of algorithms like LightGBM and Vowpal Wabbit as Spark estimators. For example, the README highlights 'LightGBM on Spark' and 'Vowpal Wabbit on Spark' as features. Spark Serving is another piece: it lets you serve any Spark computation as a web service with sub-millisecond latency, according to the README. That turns a batch pipeline into a serving endpoint without a separate serving framework.
Getting It Running: Installation Paths and Version Matching
The README lists many installation routes: Microsoft Fabric, Synapse Analytics, Databricks, Python standalone, Spark Submit, SBT, Apache Livy and HDInsight, Docker, and R. The important detail is the version matrix. SynapseML publishes runtime-specific JVM artifacts: Spark 3.5 uses Scala 2.12, while Spark 4.0 and 4.1 use Scala 2.13. You must pick the Maven coordinate that matches your Spark and Scala versions. For Python users, the README has a Python Standalone section. For SBT, you would add the library dependency. What is clear is that the installation is not a single pip install for all cases. The Binder link points to a live notebook environment, which is a low-friction way to try the library without configuring a cluster. If you are on Databricks or Fabric, the README has a dedicated setup section for each.
Where It Falls Short: Version Fragmentation and Microsoft Ties
The most obvious limitation is the split artifact for Spark 3.5 versus Spark 4.0/4.1. That is a real operational burden. If your cluster is on Spark 3.5 and your colleague uses Spark 4.0, you cannot share the same jar. The README explicitly warns you to check the installation matrix before selecting a Maven coordinate. A second limitation is the heavy integration with Microsoft services. The 'Cognitive Services for Big Data' feature is specifically about leveraging Microsoft Cognitive Services at scale. If your organization does not use Azure or Microsoft's AI services, that feature is useless. The README also mentions a support email ([email protected]), which suggests a Microsoft-backed support path, but that is not the same as a neutral open-source community. For teams that want a vendor-neutral ML stack, that is a consideration.
The Alternative: Plain SparkML plus External Libraries
The most direct alternative is to stay with SparkML and add specialized libraries yourself. For gradient boosting, you could use XGBoost's Spark integration, which is also a Spark estimator but is not part of SynapseML. For text analytics, you could use Spark's built-in tokenizers and TF-IDF, or bring in a library like Spark NLP. The difference in approach is that SynapseML pre-packages these algorithms and Microsoft services into one consistent API, so you do not have to reconcile different library versions and APIs. But the cost is that you inherit SynapseML's release cycle and its Microsoft-centric features. The alternative gives you more control over each component, at the price of integration work. If you only need one algorithm, say LightGBM, you might be better off using the dedicated integration rather than adopting the whole library.
Maintenance and Upgrade Cost
The release history shows a steady cadence: v1.0.14 in September 2025, v1.1.0 in November 2025, and v1.1.3 in April 2026. That is roughly one release every few months, which is active maintenance. The README links to a build pipeline and a code coverage badge, indicating a CI process. The upgrade cost is tied to the Spark version matrix. When you upgrade Spark, you may need a different SynapseML artifact, and that could break your pipeline if you forget to update the Maven coordinate. The library is MIT licensed, which is permissive and does not impose copyleft obligations. That means you can embed it in commercial products without releasing your own code, but you should still review the license text for any patent or attribution clauses, which is standard advice for any MIT project. The documentation links to both Scala and PySpark API docs for version 1.1.3, so at least the docs are versioned.
Who Should Adopt It and What to Verify First
SynapseML is a good fit for teams that are already on Spark and want to add distributed ML features without learning a new framework. The composability with SparkML pipelines is a genuine advantage. Teams that are not on Spark, or that need a lightweight Python-only solution, should look elsewhere. Before adoption, verify three things. First, confirm your Spark and Scala versions and pick the matching SynapseML artifact. Second, test the library on your specific cluster provider, because the README gives different installation paths for Databricks, Fabric, and HDInsight, and those may have quirks. Third, check whether the features you need, like Cognitive Services, are available in your cloud environment. The library is MIT licensed, which is low risk, but the Microsoft-centric features may lock you into Azure. In short, adopt it if you want distributed ML inside Spark and you accept the version matrix. Skip it if you want a vendor-neutral stack or a non-Spark solution.
Editorial conclusion
Adopt SynapseML if your team already runs Apache Spark and needs distributed, composable ML for text, vision, or anomaly detection without leaving the SparkML API. Skip it if you are not on Spark, need a pure Python ML stack, or want to avoid Microsoft-specific services like Cognitive Services. Before adopting, verify the exact Spark and Scala version match: Spark 3.5 uses Scala 2.12, while Spark 4.0 and 4.1 use Scala 2.13, and choose the corresponding Maven coordinate. Also check that your cluster provider (Databricks, Fabric, HDInsight) supports the library version you plan to deploy, since installation paths differ per platform.
Frequently asked questions
What is Synapse ML?
SynapseML, previously known as MMLSpark, is an open-source library that simplifies creating massively scalable machine learning pipelines on Apache Spark, covering text analytics, vision, anomaly detection and deep learning.
What is Microsoft Synapse used for?
For machine learning pipelines, SynapseML provides distributed APIs for text analytics, vision, anomaly detection and related tasks, and Synapse Analytics is one of the named platforms with its own setup section. Support questions go to the support mail address or Gitter.
Which Scala version should I use with SynapseML?
It depends on your Spark major version. Spark 3.5 uses Scala 2.12, while Spark 4.0 and 4.1 use Scala 2.13, and the README says to consult the installation matrix before picking a Maven coordinate.
How do I install SynapseML?
The install route depends on the platform: Microsoft Fabric, Synapse Analytics, Databricks, Python Standalone, Spark Submit, SBT, Apache Livy with HDInsight, Docker, R, or building from source. Each has its own section, and the root build is Scala based through build.sbt.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-synapseml)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-synapseml)Was this useful?