Mirage Persistent Kernel: Fusing Multi-GPU LLM Inference into One Kernel Launch
Mirage Persistent Kernel: Compiling LLMs into a MegaKernel. Quickstart Mirage allows you to compile LLMs from the Hugging Face model zoo into a megakernel using just a few dozen lines of Python-mainly to define the kernel s inputs and outputs.
At a glance
- What is it?
- Mirage Persistent Kernel (MPK) compiles Hugging Face LLMs into a single fused GPU kernel, cutting inference latency by 1.2x to 6.7x. This review covers its API, execution model, and the trade-offs you should weigh before adopting it.
- Who is it for?
- Adopt MPK if you run multi-GPU LLM inference on NVIDIA hardware, need low latency, and can tolerate a source-only build and a kernel API that requires manual tensor and grid configuration. Skip it if you need a stable, pip-installable package, support for non-NVIDIA GPUs, or a high-level interface that hides scheduling details.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Cuda, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
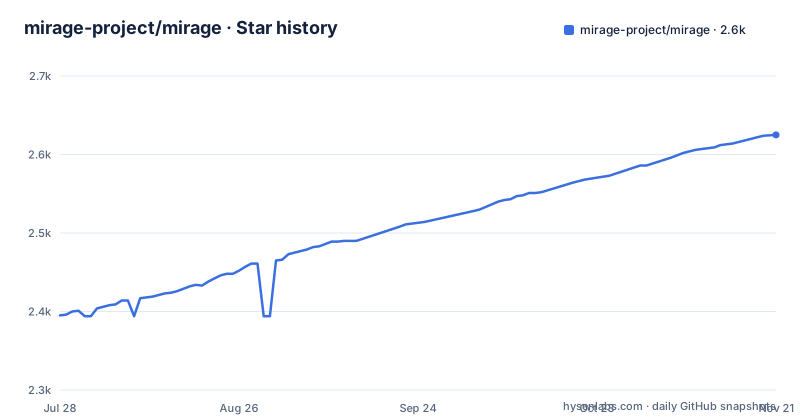
Star history
- mirage-project/mirage2,625 ★ · +230
| Repository | 2026-07-28 | 2026-11-21 |
|---|---|---|
| mirage-project/mirage | 2.4k | 2.6k |
230 Stars in the last 116 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Kernel Launch Overhead in Multi-GPU LLM Inference
LLM inference on multiple GPUs typically launches hundreds or thousands of small kernels, one for each operation like attention, normalization, and linear layers. Each launch carries overhead, and inter-GPU communication adds synchronization points. Mirage Persistent Kernel (MPK) attacks this by compiling the entire inference computation into a single megakernel: one fused GPU kernel that performs all necessary computation and communication within a single launch. The README claims a 1.2x to 6.7x reduction in inference latency. The target user is an engineer who needs low-latency serving for large models, has access to multiple GPUs, and is willing to trade compile-time and manual tuning for runtime speed.
How MPK Works: Persistent Kernels and Schedulers
MPK is a compiler and runtime system. The core idea is a persistent kernel: a kernel that stays resident on the GPU across the entire inference loop, avoiding the cost of repeated launches. The runtime uses a task graph where each fused operation is a task. The PersistentKernel API takes parameters like num_workers, num_local_schedulers, and num_remote_schedulers. These must sum to the number of physical SMs: the README states that num_workers plus (num_local_schedulers + num_remote_schedulers) / 4 must match the SM count. This constraint is unusual and requires you to know your GPU's SM count. The kernel also requires two meta tensors: step, an integer array tracking the decoding step, and tokens, a tensor of shape [num_requests, seq_length] that stores prompts and generated tokens. The runtime increments step after each decoding iteration. This design suggests MPK is tightly coupled to autoregressive decoding, not arbitrary inference workloads.
Getting Started: Installation and the Qwen3 Demo
Installation is from source only, as of the latest README update. The commands are: git clone --recursive --branch mpk https://www.github.com/mirage-project/mirage, then cd mirage, then pip install -e . -v, and finally export MIRAGE_HOME=$(pwd). The README notes that binary wheels are in progress but not yet available. To test, you run a demo script for Qwen3-8B: python demo/qwen3/demo.py runs with native Triton and FlashInfer kernels, while python demo/qwen3/demo.py --use-mirage compiles and executes the megakernel. Adding --profiling visualizes the execution timeline. The demo script is the only example provided, so you must adapt it for other models. The compilation step, mpk.compile(), is explicit, and execution is a simple call to mpk(). This is a low-level API: you define tensors, attach PyTorch tensors, and specify grid_dim and block_dim for each fused layer.
The API: Defining Tensors and Fused Layers
The API is Python but feels like CUDA. You instantiate a PersistentKernel with world_size and mpi_rank for multi-GPU setup. You attach existing PyTorch tensors with mpk.attach_input(torch_tensor=..., name=...). You allocate new tensors with mpk.new_tensor(dims=..., dtype=mi.bfloat16, name=..., io_category='cuda_tensor' or 'nvshmem_tensor'). The nvshmem_tensor category is required for remote GPU access, such as during all-reduce. Then you chain fused operations. The README shows rmsnorm_linear_layer, which fuses RMSNorm and a Linear layer. You must specify grid_dim and block_dim for each operation, which control the number of thread blocks and threads per block. The README suggests that the total number of thread blocks should be a multiple of the number of workers to avoid outliers. This is a manual tuning knob that a higher-level framework would hide.
Limitations and Wrong-Tool Cases
MPK is not a drop-in replacement for your inference stack. The most obvious limitation is the source-only build. The README explicitly says binary wheels are not yet available, so you must compile from source, which can be a barrier in production environments. The SM count constraint is another limitation: if your GPU has an SM count that does not satisfy the worker/scheduler formula, you cannot use the default configuration. The API is also narrow: it provides fused operations like rmsnorm_linear_layer, but the README does not list a full set of operations. If your model uses an operation not covered, you may need to write custom CUDA or extend the framework. Finally, MPK is designed for multi-GPU inference; for single-GPU models, the overhead of managing remote schedulers and nvshmem tensors may be unnecessary, and the latency gains are likely smaller.
Alternative: Native Triton and FlashInfer Kernels
The demo script itself provides the alternative: running the same model with native Triton and FlashInfer kernels instead of MPK. The command python demo/qwen3/demo.py without --use-mirage uses these standard kernels. The difference in approach is that Triton and FlashInfer launch multiple kernels, one per operation, and rely on the framework's runtime to schedule them. MPK instead compiles the entire graph into a single persistent kernel. This is a fundamental design trade-off: MPK reduces launch overhead but requires a compilation step and manual scheduling parameters. For workloads where the kernel launch overhead is not the bottleneck, the alternative may be simpler and more portable. The README's latency claim of 1.2x to 6.7x is relative to this baseline, but the exact conditions are not specified.
Maintenance, License, and Upgrade Path
The project is under active development, with the default branch named mpk and a recent release tagged osdi26-ae-v1, which is the artifact for the OSDI 2026 paper. The last push was in June 2026, indicating ongoing work. The license is Apache-2.0, which permits commercial use, modification, and distribution, but you should review the full license text for any patent or trademark clauses. The upgrade path is not documented in the README; there is a roadmap linked in the repository issues, but no specific upgrade instructions. Given the pre-release nature, expect breaking changes between versions. The README mentions that binary wheels are being worked on, so future releases may simplify installation, but as of now, you must build from source and track the mpk branch.
Editorial conclusion
Adopt MPK if you run multi-GPU LLM inference on NVIDIA hardware, need low latency, and can tolerate a source-only build and a kernel API that requires manual tensor and grid configuration. Skip it if you need a stable, pip-installable package, support for non-NVIDIA GPUs, or a high-level interface that hides scheduling details. Before adopting, verify that your model architecture matches the fused operations MPK provides (e.g., rmsnorm_linear_layer), that your GPU's SM count can satisfy the worker/scheduler constraint, and that you are comfortable with the mpk branch's pre-release status. The project is actively developed, but the lack of binary wheels as of mid-2025 means you must build from source, so test the demo on your exact hardware first.
Frequently asked questions
What is the Mirage Persistent Kernel?
A compiler and runtime that transforms LLM inference into a single megakernel, a fused GPU kernel doing all the computation and communication in one launch. The page states a latency reduction range of 1.2 to 6.7 times.
How do I install Mirage MPK?
From source only: a recursive clone of the mpk branch, an editable pip install, and MIRAGE_HOME pointing at the checkout. No binary wheels are offered, and the note about working on them is dated 19 June 2025.
How do I run the Qwen3 demo with Mirage?
Run demo/qwen3/demo.py for native Triton and FlashInfer kernels, add --use-mirage to compile and execute the megakernel instead, and add --profiling to visualise the execution timeline of each task.
What meta tensors does a Mirage megakernel require?
Two: step, an integer the engine increments after each decoding iteration, and tokens, of shape num_requests by seq_length, holding prompts and generated tokens.
What does io_category control when allocating a Mirage tensor?
It must be cuda_tensor for memory local to one GPU, or nvshmem_tensor for remote access, which the page says is needed for operations such as all-reduce across devices.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mirage-project-mirage)Star history chart for your README
[](https://hysenlabs.com/projects/mirage-project-mirage)Was this useful?