cuDF ships as five packages, and the -cu12 or -cu13 suffix is where installs go wrong
cuDF - GPU DataFrame Library. cudf.pandas With a Python file containing pandas code: Use cudf.pandas by invoking python with -m cudf.pandas If running the pandas code in an interactive Jupyter environment, call %load_ext cudf.pandas before importing pandas.
At a glance
- What is it?
- cuDF is NVIDIA's Apache-2.0 GPU DataFrame library, part of the CUDA-X suite, and it is not one package but five, layered over a CUDA C++ core with Arrow compliant structures. Three Python surfaces sit on that core: cudf mirroring the pandas API, cudf.pandas accelerating existing pandas code, and cudf-polars running Polars lazily on the GPU, each with its own activation path.
- Who is it for?
- Reach for cuDF when your tabular work already fits the pandas or Polars API and the data fits in GPU memory. Before installing, confirm the CUDA major version on the machine, because the pip wheel suffix must match it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
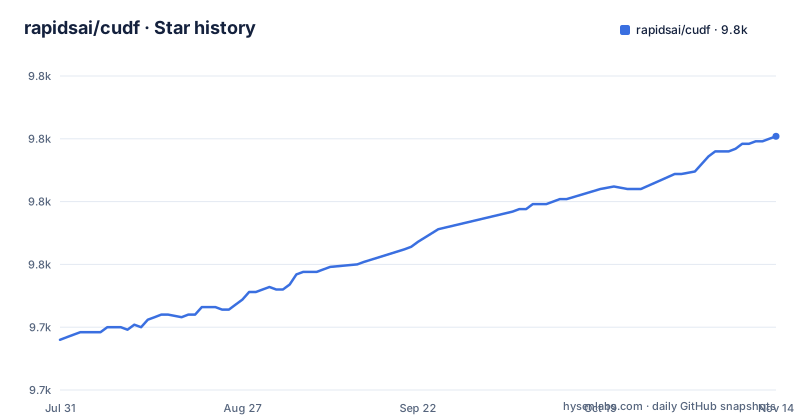
Star history
- rapidsai/cudf9,801 ★ · +81
| Repository | 2026-07-31 | 2026-11-14 |
|---|---|---|
| rapidsai/cudf | 9.7k | 9.8k |
81 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The -cu12 and -cu13 suffixes encode your CUDA major version
The pip path has a hard requirement that is easy to miss. A stable release of each cuDF library is on PyPI, and you must match the major version number of your installed CUDA version with a `-cu##` suffix. That applies to all five packages separately:
# CUDA 13
pip install libcudf-cu13
pip install pylibcudf-cu13
pip install cudf-cu13
pip install cudf-polars-cu13
pip install dask-cudf-cu13
There is a second block with the same five lines using `-cu12` for CUDA 12. The README lists the five libraries as separate pip installs. Know the driver and CUDA version first, using the system requirements page, and install all five from one block.
Nightly builds live on their own index, one package at a time
Two channels exist for each package and they are not interchangeable. On pip, the stable releases come from PyPI while the development version comes from a separate index, included with the `-i` flag pointing at:
-i https://pypi.anaconda.org/rapidsai-wheels-nightly/simple/On conda the same split is expressed as a channel name, `-c rapidsai` for stable and `-c rapidsai-nightly` for the development version, with the five installs written out individually:
conda install -c rapidsai libcudf
conda install -c rapidsai pylibcudf
conda install -c rapidsai cudf
conda install -c rapidsai cudf-polars
conda install -c rapidsai dask-cudf
The consequence is that a nightly is opt-in per command rather than a mode you switch on.
Three Python surfaces sit on one CUDA C++ core
cuDF is not a single library. libcudf is a CUDA C++ library with Apache Arrow compliant data structures and fundamental algorithms for tabular data. pylibcudf provides Cython bindings for libcudf. cudf is the Python library that mirrors the pandas API, and it also carries cudf.pandas, described as a zero code change accelerator for existing pandas code. cudf-polars is a separate Python library giving Polars a GPU engine, and dask-cudf is a GPU backend for Dask DataFrames.
The consequence is that the API you write against and the work that ends up on the GPU are decoupled. cudf.pandas is described as a zero-code-change accelerator for existing pandas code, and the README says to turn it on explicitly with python -m cudf.pandas or %load_ext cudf.pandas.
cudf.pandas has two activation paths and both are silent when skipped
There are two ways to turn the accelerator on, and both must happen before the code runs. For a Python file full of pandas code, you invoke the interpreter with the module:
$ python -m cudf.pandas script.pyIn an interactive Jupyter environment you instead load the extension before importing pandas:
In [1]: %load_ext cudf.pandas

In [2]: import pandas as pd

In [3]: df = pd.read_parquet("data.parquet")

In [4]: df.dropna().groupby(["A", "B"]).mean()
The ordering is the whole point. The README says to call %load_ext cudf.pandas before importing pandas, so keep that order.
Polars runs on the GPU only where collect says so
The Polars route is not a proxy layer. You build a lazy query with Polars and ask for the GPU engine at the one point where work actually happens:
import polars as pl

lf = pl.scan_parquet("data.parquet")
lf.drop_nulls().group_by(["A", "B"]).mean().collect(engine="gpu")
The direct cuDF equivalent reads the file and aggregates in one line:
import cudf

df = cudf.read_parquet("data.parquet")
df.dropna().groupby(["A", "B"]).mean()
The consequence of the engine parameter being attached to collect is scope: any code path that reaches the sink without that argument runs on the CPU, including intermediate collects inside a helper function you did not write. Code written for cudf and code written for cudf-polars also look similar and are not interchangeable, since one is a DataFrame library and the other is a lazy plan plus an engine choice.
Calendar versioning and a pinned dependency file
The release tags follow the calendar. The three most recent are v26.10.02 dated 20 October 2026, v26.10.01 dated 20 October 2026, and v26.10.00 dated 8 October 2026, and the last push to the main branch landed on 2 November 2026. Several releases in one month with a version that changes with the date is a fast cadence.
The repository carries VERSION and RAPIDS_BRANCH as files at the root, alongside dependencies.yaml and a conda/ directory, so the dependency set is declared in the tree. Building from source means a CMake path, with cpp/, cmake/, build.sh and a contribution guide section on setting up the build environment. The consequence for a reader on a dated release is that a pin is incomplete unless you also pin the CUDA suffix, since the wheel name carries information the version string does not.
Type checking is enforced in two packages and waived elsewhere
pyproject.toml is unusually specific about where rigor applies. mypy runs with ignore_missing_imports true but ignore_errors false, so missing stubs are tolerated while real type errors are not, and the Cython layer under cudf/_lib/ along with the test trees are excluded. Two overrides raise the bar: cudf.core.column.* and cudf_polars.* must define untyped-def-free signatures. A third override makes follow_imports normal for polars specifically, with a comment explaining that polars types are otherwise skipped and assumed to be Any, which is a deliberate refusal to let the GPU engine be untyped.
Formatting and spelling are enforced the same way, with ruff at line length 79 targeting py312, codespell with an explicit skip list and an ignore-regex for short words and typename parameters, plus pre-commit configuration and clang-format for the C++ side. The consequence for anyone reading the repository as a user is that the enforcement tells you where the risk sits: the column layer and the Polars integration are the parts kept honest, while the compiled layer is trusted to behave.
Editorial conclusion
Reach for cuDF when your tabular work already fits the pandas or Polars API and the data fits in GPU memory. Before installing, confirm the CUDA major version on the machine, because the pip wheel suffix must match it. Then pick one Python surface and follow its activation steps from the README.
Frequently asked questions
How does cuDF work?
It is layered on libcudf, a CUDA C++ library with Apache Arrow compliant data structures, reached from Python through pylibcudf Cython bindings and the cudf library that mirrors the pandas API, with cudf.pandas accelerating existing pandas code.
How do I install cuDF with pip?
Install each library from PyPI with a suffix matching your CUDA major version, for example pip install libcudf-cu13, pylibcudf-cu13, cudf-cu13, cudf-polars-cu13, and dask-cudf-cu13 for CUDA 13.
What is the difference between cudf and cudf.pandas?
cudf is a DataFrame library mirroring the pandas API, while cudf.pandas is a zero code change accelerator that runs existing pandas code through the GPU layer.
Does cuDF support Polars and Dask?
Yes, through two separate libraries: cudf-polars provides a GPU engine for Polars, used by passing collect with engine="gpu" on a lazy query, and dask-cudf provides a GPU backend for Dask DataFrames.
Which projects use cuDF?
Named users include the cuDF plugin for Apache Spark, Velox-cuDF for executing Velox plans on the GPU, and Sirius, a GPU-native SQL engine providing extensions for libraries like DuckDB.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rapidsai-cudf)Star history chart for your README
[](https://hysenlabs.com/projects/rapidsai-cudf)Was this useful?