MLC LLM: A Compiler-Based Route to Running LLMs Anywhere
Universal LLM Deployment Engine with ML Compilation
At a glance
- What is it?
- MLC LLM uses machine learning compilation, not just runtime optimization, to deploy large language models across GPUs, CPUs, browsers, and mobile. This review examines its architecture, setup path, and the trade-offs of its universal approach.
- Who is it for?
- MLC LLM suits teams that need one LLM deployment path across diverse hardware, from AMD GPUs to browsers and phones, and are willing to learn a compilation workflow. It is the wrong choice for those who want a plug-and-play runtime with minimal configuration or who only target NVIDIA CUDA, where mature alternatives like vLLM or TensorRT-LLM may offer simpler paths.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 14 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
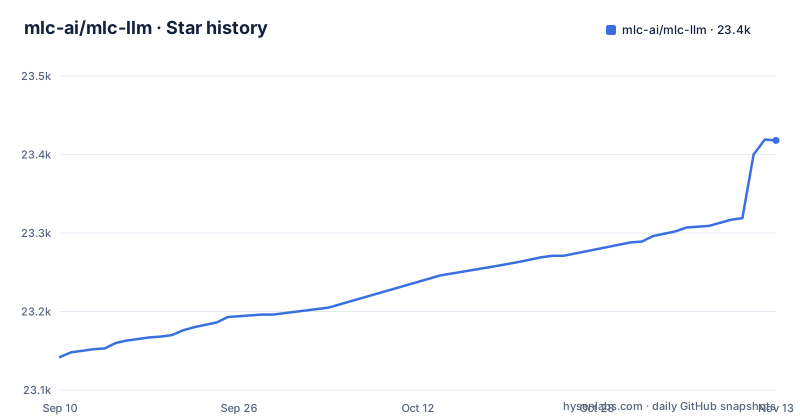
- mlc-ai/mlc-llm23,418 ★ · +276
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| mlc-ai/mlc-llm | 23.1k | 23.4k |
276 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: LLM Deployment Is a Porting Problem, Not Just a Runtime Problem
Most LLM serving tools assume a fixed hardware environment: CUDA for NVIDIA, ROCm for AMD, and so on. If you need the same model on a Mac, an Android phone, and a browser, you typically maintain separate stacks with different optimizations and APIs. MLC LLM attacks this differently. It treats deployment as a compilation problem. The project describes itself as a machine learning compiler and high-performance deployment engine. The core idea is that you compile the model once for each target platform, producing code that runs natively on that platform's GPU or CPU. This contrasts with interpreters that dispatch operations at runtime. The intended audience is engineers who need broad platform coverage without rewriting inference logic per device. The README lists support for AMD, NVIDIA, Apple, and Intel GPUs across Linux, Windows, macOS, browsers, iOS, and Android. That breadth is the project's reason for existing.
MLCEngine: One Engine, Many Front Ends
The compilation output runs on MLCEngine, which the README calls a unified high-performance LLM inference engine. MLC LLM compiles code and runs it on this engine. What makes it unified is that the same engine backs every interface: a REST server, Python bindings, JavaScript, iOS, and Android. The REST server exposes an OpenAI-compatible API, which means existing clients written for OpenAI's API can point at MLC LLM with minimal changes. The JavaScript and mobile bindings are not just remote clients. They run the engine locally on the device, using WebGPU in the browser or Metal on Apple hardware. This is a meaningful architectural choice. You get one codebase for inference logic, but the actual kernel code is generated per target. The trade-off is that you must compile for each platform, which adds a build step that a pure runtime approach avoids.
How Compilation Works: TVM, TensorIR, and Auto-Tuning
The README lists the underlying techniques in a references block, starting with TensorIR: An Abstraction for Automatic Tensorized Program Optimization, and the Python package depends on apache-tvm-ffi. The README does not detail how long compilation takes or whether pre-compiled models are available, so expect a learning curve if you compile from scratch.
Getting Started: Installation and Quick Start
The README points to the documentation for installation and quick start, but it does not list exact commands. The Python package defined in pyproject.toml is named mlc_llm and requires Python 3.9 or newer. Its declared dependencies include torch, transformers, fastapi, uvicorn and openai, and the repository carries a CMakeLists.txt and a .gitmodules file.
Platform Coverage: The Matrix Is the Selling Point, and the Risk
The compatibility table in the README is the most concrete claim. It lists Vulkan and ROCm for AMD on Linux and Windows, Vulkan and CUDA for NVIDIA, Metal for Apple GPUs, and Vulkan for Intel. On macOS, AMD dGPUs get Metal, and Intel iGPUs get Metal. Browsers get WebGPU and WASM across all vendors. iOS and iPadOS use Metal on A-series GPUs. Android uses OpenCL on Adreno and Mali GPUs. This is broad, but it is also a matrix of backend APIs, not specific GPU models. Vulkan support does not guarantee every AMD GPU works well. Metal on Intel iGPUs may be slow for large models. The matrix omits CPUs entirely, which is odd for a universal engine. The README does not mention x86 CPU inference, only GPU and browser targets. If you need CPU-only deployment, MLC LLM may not be the right tool, or at least it is not advertised. Also, the matrix does not specify which model architectures are supported. Compilation is model-specific, so a model not in the supported list may require extra work.
A Real Alternative: vLLM for CUDA-Only Simplicity
If your deployment is confined to NVIDIA GPUs, vLLM is a direct alternative. vLLM uses a runtime approach with PagedAttention and continuous batching, optimized for high throughput on CUDA. It does not compile models. It loads a model and runs it with pre-built kernels. The difference in approach is fundamental: vLLM optimizes for a single hardware class with runtime scheduling, while MLC LLM compiles for many backends. For a team that only has NVIDIA GPUs, vLLM avoids a compilation step. MLC LLM's advantage only appears when you need the same model on a MacBook or a phone. If you need that breadth, vLLM cannot help. If you do not, the extra complexity of compilation is a cost with no benefit. The trade-off is clear: universal portability versus specialized performance and simplicity.
Maintenance and Licensing: What the Repo Tells Us
The project is licensed under Apache-2.0, which is permissive and allows commercial use with attribution. The README cites academic papers, indicating a research-driven project. The last push to the repository was in October 2026, and the project is not archived. However, the most recent release listed is v0.1.dev0 from April 2023. That is a development version, and the gap between the release date and the last push suggests that the project may distribute via nightly builds or documentation, not tagged releases. This is a maintenance risk. A project with no stable release in over three years may have breaking changes between commits. For production use, you would need to pin a specific commit or build your own wheel. The Apache-2.0 license gives you freedom to fork and maintain internally, but that is work you must budget for. The README mentions a Discord for community support, which is informal compared to a commercial support contract.
Editorial conclusion
MLC LLM suits teams that need one LLM deployment path across diverse hardware, from AMD GPUs to browsers and phones, and are willing to learn a compilation workflow. It is the wrong choice for those who want a plug-and-play runtime with minimal configuration or who only target NVIDIA CUDA, where mature alternatives like vLLM or TensorRT-LLM may offer simpler paths. Before adopting, verify that the models you need are supported and that your target platform appears in the compatibility matrix, since no guarantee of coverage exists for every model or every GPU variant.
Frequently asked questions
What is MLC LLM?
It is a machine learning compiler and high-performance deployment engine for large language models, with an OpenAI-compatible API provided by MLCEngine across REST, Python, JavaScript, iOS and Android. The README does not expand the acronym itself, and the package name on the index is mlc_llm.
How do you install MLC LLM?
The README contains no install command and links to the documentation's Installation, Quick start and Introduction pages instead. The Python package is named mlc_llm, requires Python 3.9 or newer, and depends on torch, transformers, fastapi, uvicorn and the openai client among others.
How does MLC LLM compare to vLLM?
The repository names no alternative and makes no comparison, and publishes no benchmark. What it states about itself is that it compiles and runs code on MLCEngine across AMD, NVIDIA, Apple and Intel GPUs plus WebGPU and Android, with an OpenAI-compatible API.
How does MLC LLM compare to Ollama?
Nothing in the repository compares the two. The README describes MLC LLM as a compiler and deployment engine whose API is OpenAI-compatible across a REST server, Python, JavaScript, iOS and Android, and it offers no figures for either project.
What are the alternatives to MLC LLM?
The repository does not name any. The architectural alternative is a runtime that loads weights and serves an OpenAI-compatible endpoint with no compile step, which is the part of the design that MLC LLM's compiler changes: the cost moves into per-target compilation, CMake and submodule initialisation.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mlc-ai-mlc-llm)Star history chart for your README
[](https://hysenlabs.com/projects/mlc-ai-mlc-llm)Was this useful?