Manifest: an OpenAI-compatible LLM gateway with routing, fallbacks and dollar tracking
Connect Your Agents And Harnesses With Any Provider 🦚
At a glance
- What is it?
- Manifest (repository mnfst/llm-gateway) puts API keys, provider subscriptions and local models behind one OpenAI-compatible endpoint, with fallback routing and per-request cost logs. The interesting part is the operational plumbing, not the model calls.
- Who is it for?
- Adopt Manifest if you already run agents and harnesses against more than one provider and want a single OpenAI-compatible endpoint plus per-request cost records and fallback behaviour you control. Skip it if you need horizontal scaling out of the box, because the volume-backed deployment templates are documented as single-instance and expect S3-compatible storage before you scale.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
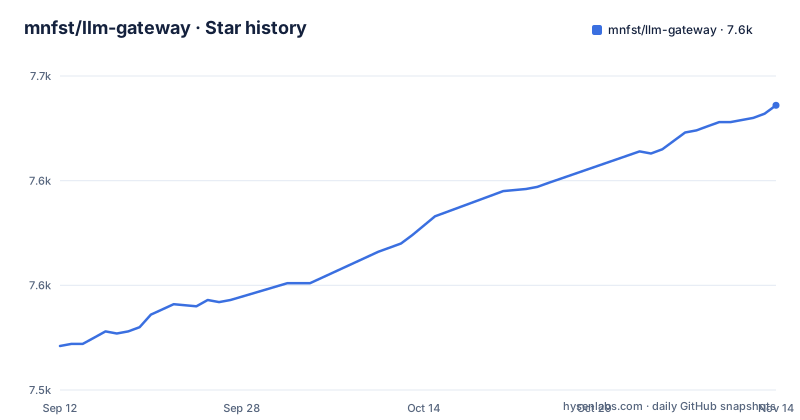
- mnfst/llm-gateway7,636 ★ · +115
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| mnfst/llm-gateway | 7.5k | 7.6k |
115 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Manifest targets: provider sprawl inside agent code
An agent or harness that talks to several providers accumulates glue. One client for an API key, another for a subscription plan, a third for a local model, plus retry logic when a provider returns an error and a spreadsheet somewhere that is supposed to explain the monthly bill. Manifest's README frames the project as an open-source LLM gateway that connects API keys, subscriptions and local models to one OpenAI-compatible endpoint, with each query routed to the right model. The stated goal is avoiding single-provider lock-in. That framing tells you who this is for: teams running agents in production who want provider choice to be a configuration concern rather than a code change. It is less obviously aimed at a single-developer script that calls one model and never retries.
Routing, fallback and logging: the mechanism the README describes
Four capabilities are listed in the README. Custom routing across API keys, subscriptions, local models and custom providers. Full body logs for both success and error messages. Dollar tracking with notifications and limits. Fallback to different models when a query fails, described as self-healing bad requests. The data flow implied by that list is a request arriving at an OpenAI-compatible surface, being matched to a provider and credential according to routing rules, forwarded, and then recorded with its full body and its cost whether it succeeds or fails. The full-body logging point deserves attention because it is the least glamorous and the most consequential: capturing error bodies means the gateway holds the text of failed requests, which is exactly the material you need to debug a malformed payload and exactly the material you should think twice about retaining. Check the documentation for the routing rule syntax and the granularity of matching (per model, per header, per key) before committing.
Running it: Docker one-liner, port 2099, first account becomes admin
The quickest self-hosted path is a single command from the README: bash <(curl -sSL https://raw.githubusercontent.com/mnfst/llm-gateway/main/docker/install.sh). It pulls the Docker image published as manifestdotbuild/manifest. The service then listens on http://localhost:2099, and the README states that the first account you create becomes the admin. That last detail is a real operational constraint rather than a footnote: on a host reachable from anywhere, whoever signs up first holds the admin role, so the window between starting the container and creating your account is a window you should close. There is also a cloud version at app.manifest.build for people who do not want to run the container. The repository ships a dedicated self-hosting guide at docker/DOCKER_README.md; if you need configuration details before deploying, that file is the first thing to read.
Deployment templates and the single-instance boundary
Manifest publishes one-click deployment paths for Railway, Render, DigitalOcean, AWS and GCP, with per-platform tutorials under deploy/. The README describes what each provisions: Railway includes Manifest plus PostgreSQL and S3-compatible storage for request recordings; Render pairs Manifest with PostgreSQL and a persistent recording disk; DigitalOcean uses App Platform with PostgreSQL and expects you to supply a private Space for recordings; AWS uses CloudFormation to provision ECS, RDS and a private recording bucket; GCP uses DeployStack to provision Cloud Run, Cloud SQL and Cloud Storage. The README states that every deployment path now uses durable request-recording storage, and then draws a line that matters more than the list: volume-backed templates are single-instance, and you should move to S3-compatible storage before scaling horizontally. So the zero-effort deployments and horizontal scale are in tension by design. If your traffic requires more than one instance, the recording backend is the component that decides whether that is possible, not the gateway process itself.
Where Manifest is the wrong tool
Two cases stand out. First, if you genuinely use one provider and one key, a gateway adds a network hop, a database, a recording store and an admin surface in exchange for routing you will not use. The install script is short, but the deployment templates provision PostgreSQL and object storage, which is a real footprint. Second, if your organisation prohibits retaining prompt and response bodies, the full body logging feature described in the README is a liability rather than a feature, and you would need to confirm whether it can be disabled or scoped before adopting.
Compared with calling the provider SDK directly
The honest alternative is not another gateway. It is the provider SDK plus your own retry wrapper. That approach keeps one dependency, no extra process, and no place where prompt bodies accumulate. What it does not give you is a uniform OpenAI-compatible surface across providers, which is the specific thing Manifest sells: point an existing harness at a different base URL and it keeps working while the credential behind that URL changes. It also does not give you the cost ledger or the fallback-on-failure behaviour without you writing both. The trade is legibility against control. With the SDK you can read the retry logic because you wrote it. With a gateway you get the behaviour for free and inherit its routing semantics, its storage requirements and its admin model. Neither is wrong; the deciding question is whether provider switching happens often enough in your setup to justify a component whose internals you did not write.
Licence, maintenance and what version numbers tell you
Manifest is MIT licensed, which permits commercial use and modification with the usual requirement to preserve the licence notice; this is a description of the licence text, not legal advice, and your counsel should review anything you redistribute. Maintenance signals are active: the repository is not archived, the last push is dated 2026-11-02, and releases are frequent, with [email protected], 6.28.10 and 6.28.11 landing between 2026-10-16 and 2026-10-29. A version line at 6.x with patch releases arriving about weekly implies steady change, which cuts both ways. You get fixes quickly. You also inherit upgrade work. The practical cost is that a self-hosted instance is a moving target: the Docker image tag, the database schema behind PostgreSQL, and the recording storage layout all move together, so pinning a version and reading the release notes before bumping is cheaper than tracking latest. Note also that the repository name is mnfst/llm-gateway while the product, the releases and the deployment templates are all named manifest, so expect to see both names in issues, docs and image tags.
Editorial conclusion
Adopt Manifest if you already run agents and harnesses against more than one provider and want a single OpenAI-compatible endpoint plus per-request cost records and fallback behaviour you control. Skip it if you need horizontal scaling out of the box, because the volume-backed deployment templates are documented as single-instance and expect S3-compatible storage before you scale. Verify first: that your provider mix is representable in the routing configuration, that your chosen deployment path provisions durable recording storage, and that the admin account created on first sign-up is the one you want holding admin rights.
Frequently asked questions
What is an LLM gateway?
In this project's terms it is a service that sits between your application and several model providers, exposing one OpenAI-compatible endpoint. You give it API keys, subscription logins or local models, and it routes each query to the right one, so the application does not change when the model behind it does.
How do I use an LLM gateway like manifest?
Point an existing OpenAI-compatible client at the gateway and either name a model explicitly or send the automatic routing value so the gateway picks. For a self-hosted instance, run the container install command, open http://localhost:2099, and create the first account, which becomes the administrator.
What is manifest?
It is the self-hosted gateway described in the readme: an open-source LLM gateway for agents and applications that connects API keys, subscriptions and local models to one OpenAI-compatible endpoint. Its package metadata also describes it as open-source observability for AI agents, covering cost, token, message and performance tracking.
How does an LLM gateway differ from a hosted model router?
What the readme claims is provider independence: more than three hundred models through thirty-five built-in provider connections, eighteen subscription flows, any custom compatible endpoint, automatic model selection, and fallback to another model when a query fails.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mnfst-llm-gateway)Star history chart for your README
[](https://hysenlabs.com/projects/mnfst-llm-gateway)Was this useful?