llm-foundry: four script trees and a 132B contradiction
LLM training code for Databricks foundation models
At a glance
- What is it?
- llm-foundry is MosaicML's Python code for training, finetuning, evaluating and deploying LLMs for Databricks foundation models, split between a library directory and four runnable workload trees. Its README advertises a 125M to 70B training range while the same file announces a 132B model.
- Who is it for?
- Adopt llm-foundry if you already run Composer and want the MPT and DBRX training paths sitting next to the throughput and latency scripts. Skip it if you want a stable packaged install, since the Dockerfile demands a base image and a branch name supplied from outside, and the MPT table answers the commercial question that model sizes cannot.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- No. The owners have archived the repository on GitHub, so it is read-only and no longer receives changes.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
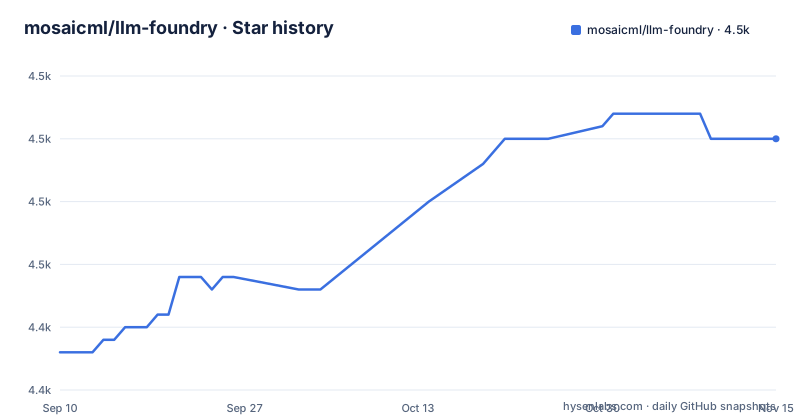
Star history
- mosaicml/llm-foundry4,460 ★ · +17
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| mosaicml/llm-foundry | 4.4k | 4.5k |
17 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
scripts/ splits the workloads into four runnable subtrees
llm-foundry keeps its library and its runnable work apart. Source for models, datasets, callbacks and utilities sits in `llmfoundry/`, while everything you execute sits under `scripts/`. Four subtrees divide that second half: `data_prep/` converts text from its original sources into StreamingDataset format, `train/` trains or finetunes HuggingFace and MPT models from 125M to 70B parameters, `inference/` converts models to HuggingFace or ONNX format and generates responses, and `eval/` runs academic or custom in-context-learning tasks.
Two of the four own a benchmarking directory, and the split says what each one measures. Training throughput and MFU profiling live in `train/benchmarking`; inference latency and throughput profiling live in `inference/benchmarking`. A single run settles neither number, which is why measurement code ships beside the workload instead of in a separate tool.
A fifth directory, `mcli/`, launches any of these through MCLI and the MosaicML platform, so one script can be driven locally or from the hosted platform. Longer documentation sits in `TUTORIAL.md`, which the README calls a deeper dive with example workflows and FAQs.
The Dockerfile clones a branch and then deletes the clone
The Dockerfile holds an installation sequence, and it targets a build image rather than a laptop. The base image arrives as `ARG BASE_IMAGE` with no default value, the branch as `ARG BRANCH_NAME`, and dependency extras ride in `ARG DEP_GROUPS`.
ARG KEEP_FOUNDRY=false

ENV TORCH_CUDA_ARCH_LIST="8.0 8.6 8.7 8.9 9.0"
The clone lands at `/llm-foundry`, which is why the install path begins with `./llm-foundry`.
RUN git clone -b $BRANCH_NAME https://github.com/mosaicml/llm-foundry.git
RUN pip install --no-cache-dir "./llm-foundry${DEP_GROUPS}"
Afterwards the checkout is discarded unless you ask otherwise:
RUN if [ "$KEEP_FOUNDRY" != "true" ]; then \
      pip uninstall -y llm-foundry && \
      rm -rf /llm-foundry; \
    fi
Set `KEEP_FOUNDRY` to true and both the package and its source stay in the image. Leave it at the default false and the package is uninstalled and /llm-foundry removed, leaving only the cached requirements. One detail matters for hardware planning: `TORCH_CUDA_ARCH_LIST` is frozen at 8.0, 8.6, 8.7, 8.9 and 9.0, so a card outside that list gets no kernel compiled for it. A cache trick sits above the clone, where setup.py is fetched on its own and then deleted so a change to that one file invalidates the layer.
Makefile tests ride Composer's launcher on port 26000
Every target in the Makefile is a wrapper around pytest, and the distributed pair borrows Composer's launcher instead of starting a process group itself.
test:
WORLD_SIZE=1 LOCAL_WORLD_SIZE=1 $(PYTHON) -m $(PYTEST) $(EXTRA_ARGS)test-dist:
$(PYTHON) -m composer.cli.launcher -n $(WORLD_SIZE) --master_port $(MASTER_PORT) $(EXTRA_LAUNCHER_ARGS) -m $(PYTEST) $(EXTRA_ARGS)Each knob is a ?= default at the top of the file: `WORLD_SIZE` is 1, `MASTER_PORT` is 26000, `PYTHON` is python3, `PYTEST` is pytest and `PYRIGHT` is pyright, with the two EXTRA variables starting empty. GPU runs are the same commands plus a `-m gpu` marker, so CPU against GPU is one flag.
Two consequences for a fresh checkout: port 26000 must be free before a distributed run, and nothing here installs Composer, so `test-dist` reaches pytest only when Composer is importable already. The `PYRIGHT` comment says pyright must be installed separately, with `node install -g pyright` offered as an example.
The 125M to 70B training range excludes DBRX itself
Read `train/` and then read the DBRX section, and the two claims do not agree. The training subtree is described as training or finetuning HuggingFace and MPT models from 125M to 70B parameters. DBRX, announced in the same file, has 132B total parameters and 36B active, so the flagship model sits well outside the range its own training entry point claims.
Architecture explains the gap rather than closing it. DBRX uses a Mixture-of-Experts design and was trained with optimized versions of Composer, LLM Foundry and MegaBlocks, so the MoE route runs on three projects rather than two. Two checkpoints are published, DBRX Base and DBRX Instruct, both at a context length of 32768.
Terms differ as well, and that is the detail with commercial teeth. Repository code sits under Apache-2.0, while the DBRX weights and their code carry the Databricks Open Source License with a separate acceptable use policy the README says reaches researchers and commercial entities. Reading the model terms before shipping DBRX is a separate step, and skipping it is the expensive mistake.
The version file is executed during packaging, not on import
`setup.py` cannot ask the library for its version, because the library is not installed at build time. It opens `_version.py` from the `llmfoundry` package directory that `_PACKAGE_DIR` names, runs that file through the Python exec built-in, and reads `__version__` out of the namespace which results. A comment in the file states the reason. Any code in the version file therefore executes during packaging.
The second trick is the long description sent to the package index. `setup.py` reads README.md, walks the text for `SETUPTOOLS_LONG_DESCRIPTION_HIDE_BEGIN` and `SETUPTOOLS_LONG_DESCRIPTION_HIDE_END`, asserts the pair is balanced, and splices out everything between them. The logo block at the top of the README sits inside one such pair, which is why the index page does not open with the logo.
That assertion is the part worth keeping. An unmatched marker raises instead of producing a mangled description, so a careless README edit surfaces as a packaging failure.
Ruff ignores missing docstrings but selects D404
The lint configuration in `pyproject.toml` takes an unusual position on documentation. The D rule family is selected with pydocstyle under the `google` convention, yet D100 through D105 and D107 sit in the ignore list, switching off the checks for a missing module, class, method, function or package docstring. D400, D401 and D415 are ignored too, so a first line that is not an imperative or lacks a closing period passes.
What survives is D404, pulled in through `extend-select`, which rejects a docstring opening with the word This. So the project is relaxed about whether a docstring exists and strict about how it starts. Coverage sits beside it with `parallel`, `branch` and `relative_files` enabled and `include` narrowed to `llmfoundry/*`, so code outside that package is not measured.
Formatting adds two more numbers: isort runs at `line_length` 80 with `multi_line_output` 0, and both `include_trailing_comma` and `split_on_trailing_comma` are true. Against that, the classifiers in `setup.py` include Python 3 and Python 3.10 while `target-version` is `py39`.
Every MPT chat checkpoint is marked non-commercial
The MPT table carries a column the model names cannot give you, and it splits the family along a line unrelated to size. MPT-30B, MPT-30B-Instruct, MPT-7b-8k, MPT-7B, MPT-7B-Instruct and MPT-7B-StoryWriter are all marked yes for commercial use. MPT-30B-Chat, MPT-7b-8k-Chat and MPT-7B-Chat are marked no.
So the 30B instruct checkpoint is usable and its 30B chat sibling is not, and the same split repeats at 7B. Context length varies independently of that permission: 8192 for the 30B family and the 8k models, 2048 for the plain 7B family, 65536 for StoryWriter.
The models themselves are GPT-style, with Flash Attention for efficiency, ALiBi for context length extrapolation and stability work against loss spikes. For local prompting the README points at `scripts/inference/README.md` and the `hf_generate.py` and `hf_chat.py` scripts.
Pyright errors on dead code and tolerates thin stubs
Type checking in the same file runs on the opposite priorities. `reportUnusedImport`, `reportUnusedVariable`, `reportIncompatibleVariableOverride`, `reportDuplicateImport`, `reportWildcardImportFromLibrary` and `reportUndefinedVariable` are errors, joined by `reportUnnecessaryCast`, `reportInvalidTypeVarUse` and `reportPropertyTypeMismatch`. Missing type information is not on that list: `reportMissingTypeStubs`, `reportIncompatibleMethodOverride`, `reportPrivateImportUsage` and `reportUnnecessaryIsInstance` are set to none, `reportUnusedClass` and `reportUnusedFunction` drop to warning, and `strictParameterNoneValue` is true.
Taken together that is a house style worth copying: dead code and shadowed names fail, thin annotations do not. Packaging is pinned from above rather than below, since `requires = ["setuptools < 81.0.0"]` sets a ceiling on the build tool, and the `exclude` list keeps `build/**` and `docs/**` out of linting.
Repository age is the other fact to weigh. The last push landed on 2026-03-25 while the tags stop at v0.22.0 from 2025-07-29, with v0.21.0 dated 2025-05-31 and v0.20.0 dated 2025-04-29 behind it, so a packaged install runs several months older than the code on the main branch.
Editorial conclusion
Adopt llm-foundry if you already run Composer and want the MPT and DBRX training paths sitting next to the throughput and latency scripts. Skip it if you want a stable packaged install, since the Dockerfile demands a base image and a branch name supplied from outside, and the MPT table answers the commercial question that model sizes cannot. Verify first which terms cover the checkpoint you intend to ship, because the DBRX weights do not travel under the repository terms, then read `scripts/inference/README.md` before writing any local inference wrapper.
Frequently asked questions
What is llm-foundry?
llm-foundry is the MosaicML repository holding code for training, finetuning, evaluating and deploying LLMs, built on Composer and the MosaicML platform. Source code for models, datasets, callbacks and utilities sits in `llmfoundry/`, and the runnable workloads sit under `scripts/`. The repository code is Apache-2.0.
What is the primary role of llm-foundry within the enterprise?
It covers the whole workload lifecycle for teams building on Databricks foundation models. `data_prep/` converts text data into StreamingDataset format, `train/` trains or finetunes HuggingFace and MPT models from 125M to 70B parameters, `inference/` converts models to HuggingFace or ONNX format and generates responses, and `eval/` evaluates LLMs on academic or custom in-context-learning tasks. Training and inference each have a benchmarking directory of their own.
Which GPU architectures does the llm-foundry Dockerfile build for?
The Dockerfile sets TORCH_CUDA_ARCH_LIST to 8.0, 8.6, 8.7, 8.9 and 9.0, and it takes its base from an `ARG BASE_IMAGE` line with no default value. Both are decided at build time rather than in a published image.
How do I run llm-foundry tests across more than one process?
The Makefile test-dist target runs `composer.cli.launcher` with `-n $(WORLD_SIZE)` and `--master_port $(MASTER_PORT)`, then hands control to pytest through the default PYTHON of python3. The GPU variants add the `-m gpu` marker, and port 26000 has to be free. The Makefile installs nothing, so Composer must already be importable.
Can I ship DBRX weights under the llm-foundry Apache-2.0 licence?
No. The repository code is Apache-2.0, but the DBRX model weights and code are licensed for researchers and commercial entities under the Databricks Open Source License with its own acceptable use policy. DBRX Base and DBRX Instruct, both at a context length of 32768, sit under the databricks organisation on the Hugging Face hub.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mosaicml-llm-foundry)Star history chart for your README
[](https://hysenlabs.com/projects/mosaicml-llm-foundry)Was this useful?