code2prompt: Turning a Whole Codebase into One LLM-Ready File
A CLI tool to convert your codebase into a single LLM prompt with source tree, prompt templating, and token counting.
At a glance
- What is it?
- code2prompt is a Rust CLI that packs a repository into a single prompt with a source tree, Handlebars templating, and token estimates. This review covers its mechanisms, installation paths, limitations, and where it fits in an AI-assisted workflow.
- Who is it for?
- Adopt code2prompt if you routinely feed large codebases to ChatGPT, Claude, or agentic pipelines and need a repeatable, scriptable way to assemble context with token awareness. Skip it if your needs are trivial and you prefer a GUI or an editor-native solution, or if your project relies on files that the smart readers do not handle.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
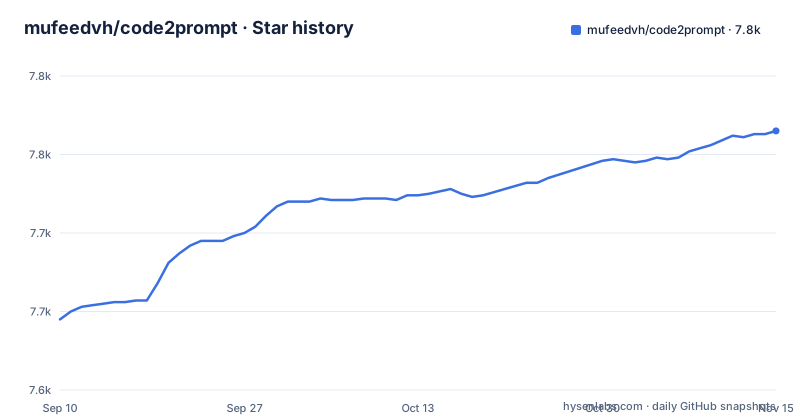
- mufeedvh/code2prompt7,765 ★ · +120
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| mufeedvh/code2prompt | 7.6k | 7.8k |
120 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: context assembly is manual and error-prone
Copying files into a chat window works for a few small files, but real projects have directories, nested modules, and configuration scattered across dozens of paths. Developers waste time deciding which files matter, then paste them in an order that loses the project's structure. code2prompt addresses this by generating a single text prompt that includes a source tree and the file contents, formatted for an LLM. The tool is aimed at anyone who prepares context manually for ChatGPT or Claude, but the README also points at AI agents and Python-based automation, so the audience extends to people building RAG pipelines or local agent tools. The core value is not magic; it is consistency. One command replaces a fragile copy-paste ritual with a deterministic output that includes the repository map.
How the pipeline works: traversal, templating, and token estimation
The README's feature list and ecosystem table describe three stages. First, the tool traverses the file tree while respecting .gitignore rules, which prevents build artifacts and dependency directories from polluting the prompt. Second, it applies a Handlebars template to structure the output, so you can control the header, the source tree format, and how each file is wrapped. Third, it estimates token usage using parallel per-file counts and an estimated template overhead. The tool also includes smart file readers that simplify formats like CSV, notebooks, and JSONL, converting them into a more LLM-friendly representation. Git integration can add diffs, logs, and branch comparisons, which is useful when you want the model to review changes rather than the entire codebase.
Installation and first run: three paths to the same binary
You can install code2prompt through Cargo with cargo install code2prompt, through Homebrew with brew install code2prompt, or as a Python SDK via pip install code2prompt-rs. The Cargo install supports an optional wayland feature for clipboard integration on Wayland systems, which you activate with cargo install --features wayland code2prompt. The basic usage is minimal: running code2prompt. from a directory prints the generated prompt to stdout, and adding -c copies it to the clipboard. To save to a file, use code2prompt path/to/project --output-file prompt.txt. The README also shows npx skills add commands for the agent skill and a source build, but these commands show the intended workflow: point at a directory, get a prompt, and then paste it into your model of choice. The Python SDK is not just a wrapper; it is described as fast bindings to the Rust core, so automation scripts can call the same logic without spawning a subprocess.
The TUI and the agent skill: two different entry points
Beyond the plain CLI, code2prompt offers an interactive TUI for configuring and generating prompts, which suits users who prefer a visual review before output. The README also promotes an agent skill that can be installed with npx skills add mufeedvh/code2prompt. That skill is designed to teach a coding agent to use code2prompt for repository navigation and scoped context gathering. It includes a map template that uses an optional entity-map feature to produce a compact map of functions and classes, with a directory map fallback for standard builds. The installer may clone the repository temporarily to retrieve the skill files, but it does not install the whole repository. This is a clever way to reduce an agent's exploration round trips: the agent sees a map first, then reads only the relevant source and tests together. The trade-off is that the skill adds another layer of setup, and the entity-map feature is optional, so a standard build will not have the richer map.
Token counting: a fast estimate, not a precise measurement
The feature list says the tool provides token estimates using parallel per-file token counts and estimated template overhead, including optional line numbers. The critical detail is that the full rendered prompt is not re-tokenized. That means the estimate is an approximation, and it deliberately excludes the JSON output envelope. For users who need to stay under a hard context limit, this could be a problem: the actual prompt might be larger than the estimate, especially if the template adds significant prose or if line numbers inflate the count. The parallel counting is a performance choice, but accuracy is sacrificed for speed. If you are working close to a model's context window, you should verify the final token count with the model's own tokenizer after generation. The README does not provide a formula for the overhead estimate, so you cannot predict the margin of error in advance.
Where it falls short: filtering and format limitations
The tool respects .gitignore, which is good for standard projects, but it can be the wrong behavior when you need to include a file that is ignored, such as a local configuration template. The README mentions include and exclude glob patterns, but it does not show the exact flags, so you will need to consult the documentation to override ignore rules. Another limitation is the smart file readers: they simplify certain formats like CSV and notebooks, but not every file type is covered. If your project contains a proprietary binary format or a highly nested JSON that the reader does not handle well, the generated prompt may lose fidelity. The tool is also a command-line utility at heart; while the TUI exists, it is not a full IDE integration. For developers who work inside an editor and want inline context selection, a tool like Aider or a dedicated Copilot extension may be more natural.
A real alternative: repomix and the difference in approach
A close alternative is repomix, another open-source tool that packs a repository into a single file for LLM consumption. The key difference is that repomix focuses on producing a packed file that you can feed to a model, with its own set of filters and output formats, while code2prompt emphasizes a templating system and a Rust core that also ships as a Python SDK and an MCP server. Repomix is written in TypeScript and runs on Node.js, which makes it easier to embed in JavaScript-based tooling, whereas code2prompt's Rust core offers a compiled binary and Python bindings. If you already live in a Node ecosystem or need a quick npx invocation, repomix might fit better. If you want a low-resource Rust binary and the ability to call the same logic from Python, code2prompt has the edge. Both tools solve the same problem, but they differ in language ecosystem and integration depth.
Maintenance and licensing: MIT with an active pulse
The project is licensed under MIT, which is permissive and allows commercial use, modification, and redistribution with attribution. The repository is not archived, and the last push was in October 2026, with the latest release v4.2.0 from December 2025. That suggests an actively maintained project, and the release history moves from v3.0.2 in April 2025 through v4.0.2 in September 2025 to v4.2.0 in December 2025. That cadence implies breaking changes may occur between versions, so you should pin your dependency or check the changelog before upgrading. The Python SDK on PyPI is named code2prompt-rs. The documentation lives on a dedicated website, code2prompt.dev, which is where the TUI and MCP server are documented in detail.
Editorial conclusion
Adopt code2prompt if you routinely feed large codebases to ChatGPT, Claude, or agentic pipelines and need a repeatable, scriptable way to assemble context with token awareness. Skip it if your needs are trivial and you prefer a GUI or an editor-native solution, or if your project relies on files that the smart readers do not handle. Before committing, verify that the token estimation approach (which does not re-tokenize the full rendered prompt) matches your budgeting needs, and confirm that the Handlebars template syntax and .gitignore handling behave as you expect on your specific repository layout. The project is actively maintained with recent releases, so check the changelog between versions for breaking changes in template variables or CLI flags.
Frequently asked questions
How do you use code2prompt?
Point it at a directory: code2prompt . prints the prompt to stdout, and code2prompt path/to/project --output-file prompt.txt writes it to a file. Add -c to copy the result to the clipboard instead, and use glob patterns with .gitignore respected to narrow what goes in.
Does code2prompt count tokens exactly?
No. It estimates prompt size using parallel per-file token counts and estimated template overhead, including optional line numbers. The full rendered prompt is not re-tokenized, and the estimate excludes the JSON output envelope.
What does code2prompt do with .gitignore and git history?
The core library traverses the tree while respecting .gitignore rules, and file selection also takes glob patterns for explicit includes and excludes. Git metadata can be added to the prompt, including diffs, logs and branch comparisons.
Can I call code2prompt from Python?
Yes, through the code2prompt-rs package on PyPI, which provides bindings to the Rust core for agents, automation and RAG pipelines. The binding is built from crates/code2prompt-python with pyo3 using the extension-module feature and the abi3-py311 ABI, and it is not one of the workspace default members.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mufeedvh-code2prompt)Star history chart for your README
[](https://hysenlabs.com/projects/mufeedvh-code2prompt)Was this useful?