Open Brain (OB1): a database-backed memory layer that any AI client can read over MCP
Open Brain — The infrastructure layer for your thinking. One database, one AI gateway, one chat channel — any AI plugs in. No middleware, no SaaS.
At a glance
- What is it?
- OB1 is a self-hosted personal memory system: one database with vector search, one AI gateway, and a chat capture channel, exposed to AI tools through MCP. It is a build-it-yourself stack, not a notes app, and the repository is a collection of setup docs, recipes, schemas and skill packs rather than a packaged product.
- Who is it for?
- Adopt OB1 if you are comfortable running your own database with vector search, AI gateway and MCP server, and want your Claude, ChatGPT or Cursor sessions to read and write the same memory store through MCP. Do not adopt it if you want a signed installer or a hosted account: the repository has no published GitHub releases, the licence is NOASSERTION, and the README's own path is a roughly 45 minute guided build.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
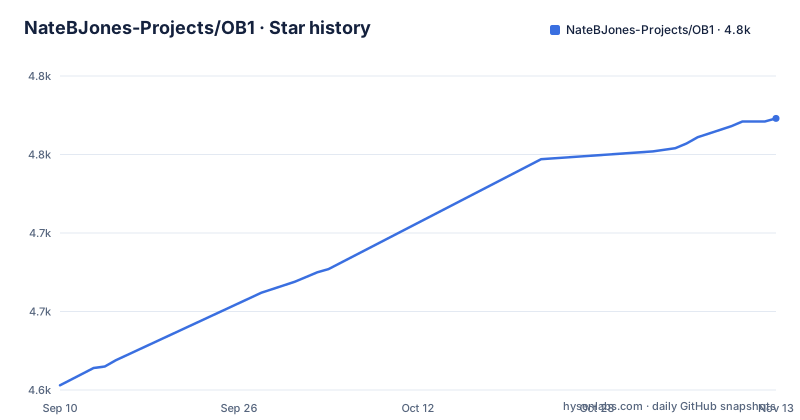
- NateBJones-Projects/OB14,773 ★ · +170
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| NateBJones-Projects/OB1 | 4.6k | 4.8k |
170 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem OB1 targets: memory that does not belong to any one AI vendor
Every AI tool you use keeps its own picture of you. Claude has one, ChatGPT has another, Cursor has a third, and none of them can read the others. The README states the goal directly: one database, one AI gateway, one chat channel, with any AI plugging in, and explicitly rejects middleware chains such as Zapier. The intended user is someone who has already accumulated notes, links and half-formed ideas across several tools and wants a single store that all of them query. The repository description calls it the infrastructure layer for your thinking. That framing matters: OB1 is not competing with a notes app on editing experience. It is competing with the absence of a shared memory backend. The README is blunt about this, saying the project is not a notes app but a database with vector search and an open protocol. If you want a polished editor, this is the wrong shape of tool. If you want a database that your coding agent and your chat assistant both read from, it is aimed at you.
What actually sits in the repository: schemas, recipes, skills and extensions
The recent contributions table is the clearest view of the project's structure, and it does not look like a conventional application. Merged work lands in directories such as schemas/thought-work-claims, schemas/wiki-pages, recipes/content-fingerprint-dedup, recipes/provenance-chains, recipes/thought-enrichment, recipes/readwise-import, recipes/google-activity-import, integrations/entity-extraction-worker, integrations/update-thought-mcp, integrations/kubernetes-deployment, skills/deleting-thoughts and extensions/household-knowledge. That layout tells you what OB1 is: a core data model (thoughts, edges, wiki pages, work claims) plus a set of independent integrations and recipes that each add a capability. There is no single binary and no published GitHub release. The README instead offers a learning path of numbered extensions, starting with a household knowledge base and a home maintenance tracker, each labelled Beginner and described as teaching new concepts through something you will actually use. So the project is closer to a reference architecture with runnable parts than to a product. That has a real consequence: two people who say they run OB1 may have installed quite different subsets of it.
The data model: thoughts, vector search, fingerprints and provenance edges
The recurring noun in the repository is the thought. Recipes add behaviour around it rather than replacing it. The content-fingerprint-dedup recipe adds a write-time fingerprint trigger, and a separate pull request fixes the Readwise importer against the content_fingerprint unique index, which implies deduplication is enforced in the database at insert time rather than in application code. The thought-enrichment recipe has fixes for UUID id pagination in backfills and for double-encoded metadata writes, which suggests enrichment runs as a batch job over existing rows and stores extra fields in a metadata column. The authorship-edges recipe adds speaker attribution and self-author edges, so the model supports typed relationships between thoughts, not just rows in a table. The provenance-chains recipe adds a capture_derived_thought MCP tool, meaning derived content records where it came from. The entity-extraction-worker integration is a separate service that calls an LLM, and one merged fix is titled to report the real cause when all LLM providers fail, so it is designed to fall through multiple providers. Vector search is named in the README as a core property; treat the specific extension and index configuration as something to confirm in the setup guide before you size your database.
How it reaches your AI tools: MCP over HTTP, and the POST-only constraint
The connection layer is MCP. The README says any AI you use can plug in, and the repository contains MCP servers such as integrations/update-thought-mcp and the ob-graph recipe, plus tool names like capture_derived_thought. Two merged fixes describe the operational reality of that choice. One rejects non-POST MCP requests with 405 to prevent a GET handshake hang, filed under integrations/kubernetes-deployment. Another fixes an ob-graph MCP GET route that caused an SSE reconnect storm. Read together, these say the MCP endpoints are HTTP services that expect POST, and that before these fixes a GET request could cause a handshake hang or an SSE reconnect storm; the kubernetes-deployment fix now rejects non-POST requests with 405. The fixes exist, which means the maintainers treat POST-only as intended behaviour rather than a bug to paper over. The practical implication is that the gateway between your AI client and the database is a small HTTP surface you have to keep alive, and that its failure mode is noisy rather than silent.
Getting it running: the documented path and the moving parts it touches
The README gives a numbered start. The Setup Guide at docs/01-getting-started.md is described as building the full system (database, AI gateway, Slack capture, MCP server) in about 45 minutes, with no coding experience needed, and there is a video walkthrough of roughly 27 minutes. For people who would rather have an AI coding tool do the work, docs/04-ai-assisted-setup.md is the alternative route: point Cursor or Claude Code at the repository and follow the same system through a different workflow. docs/02-companion-prompts.md supplies five prompts for migrating memories, discovering use cases and building a capture habit. The FAQ at docs/03-faq.md is where the README sends you when you hit a wall. Beyond that, the recipes reference environment loading (one merged change adds dotenv loading to the repo-learning-coach recipe) and model identifiers (another fixes a default model because a dated id returned 404 on OpenRouter). So the honest summary is: the entry point is documented and time-boxed, but the concrete commands live in the linked docs, not in the README, and you should read those before assuming a one-command install. The 45 minute figure is the project's own estimate, not a measurement.
Where OB1 is the wrong tool, and what it is not
Two boundaries are visible. First, the repository has no published GitHub releases and the licence is NOASSERTION, which on GitHub means the repository has a licence file the detector could not classify. For a system that holds a persistent record of your thinking, that is the first thing to resolve, because it determines what you may do with the code and what obligations follow. This is not legal advice; read the licence file yourself. Second, the support model is unusual. Help is routed to a Substack, a Discord, and three vendor-specific assistants (a Claude Skill, a ChatGPT Custom GPT and a Gemini GEM) that are described as knowing the system. That is a community and prompt-pack model, not a support contract. If your organisation needs a vendor to page at 2am, OB1 does not offer that. There is also a scope boundary the README sets itself: it is not a notes app, so evaluating it on editor quality misses the point, and the extension path starts with beginner projects like a household knowledge base, which means the payoff arrives after you build a few of them. And because the repository is a set of recipes and schemas contributed by different people, quality varies by directory: the contributions list shows two separate fixes in thought-enrichment, which is normal for young code but worth knowing before you depend on a specific recipe.
The real alternative: a general automation platform, and how the approach differs
The README names its opposite directly: no middleware, no SaaS chains, no Zapier. That is the honest comparison. A tool like Zapier or Make connects your AI tools by moving messages between them on triggers: a new note in one app fires an action that writes a row somewhere else. The data lives in whichever SaaS endpoint the automation targets, the schema is whatever that endpoint exposes, and the memory is only as consistent as the automations you maintain. OB1 inverts that. The database is the centre, vector search is a property of the store rather than a feature of one app, and MCP is the protocol every client speaks to reach it. Nothing is copied between vendors because there is only one copy. The trade is real: you own the database, the gateway, the MCP server and the Slack capture path, and you fix them when they break. The repository's own contribution history is the evidence of that cost, with fixes for pagination, double-encoded writes, SSE reconnect storms and reporting the real cause when all LLM providers fail all landing as separate pull requests. If you would rather pay a subscription than run migrations, the automation-platform approach is the better fit, and OB1 is not trying to win that comparison.
Maintenance cost and who should commit
Upgrade cost here is not a version bump. It is the set of recipes and integrations you chose, each of which is its own small service or SQL object with its own failure modes. The merged fixes give a fair sample of what maintenance looks like in practice: a unique index that an importer must respect, a backfill that must paginate UUIDs correctly, a metadata column that can be written double-encoded, an MCP route that must reject GET, and an entity-extraction worker that must report the real cause when every LLM provider fails. None of these are exotic, and all of them are yours once you deploy. The project is also explicitly a learning path, with extensions ordered by difficulty and each one teaching a concept, so the intended experience is incremental building rather than install-and-forget. That suits an individual who wants their own memory layer and is willing to read docs/01-getting-started.md, then docs/03-faq.md when something breaks. It suits a small team with someone who owns the deployment. It does not suit anyone who needs a hosted account, a support contract, or a licence they can classify without opening the file. Verify the licence, verify that your MCP client uses POST, and start with the Setup Guide before you commit your real notes to it.
Editorial conclusion
Adopt OB1 if you are comfortable running your own database with vector search, AI gateway and MCP server, and want your Claude, ChatGPT or Cursor sessions to read and write the same memory store through MCP. Do not adopt it if you want a signed installer or a hosted account: the repository has no published GitHub releases, the licence is NOASSERTION, and the README's own path is a roughly 45 minute guided build. Before committing, verify the licence file in the repository root, confirm the MCP server's POST-only behaviour against your client, and read docs/03-faq.md for the failure modes other builders have already hit.
Frequently asked questions
What is open brain AI?
Open Brain is a self hosted memory infrastructure project by Nate B. Jones, described as a database with vector search and an open protocol rather than a notes app. It is built as one database, one AI gateway and one chat channel, with any AI tool able to plug in, and the README states no middleware and no SaaS chains as explicit design goals.
How do I set up Open Brain?
The setup guide builds the full system, including a database, an AI gateway, Slack capture and an MCP server, in about 45 minutes with no coding experience needed, and a video walkthrough of roughly 27 minutes is linked beside it. An alternative path points Cursor, Claude Code or another coding tool at the repository instead, and companion prompts are provided for migrating memories and building the capture habit.
Where do I get help with Open Brain?
The README points at a FAQ covering common questions and gotchas, plus three purpose-built assistants that know the system: a Claude Skill, a ChatGPT Custom GPT and a Gemini GEM. It says to use whichever matches the AI tool you already use. The contribution table also shows shippd skill packs inside the project itself, including updating-thoughts and deleting-thoughts under skills/deleting-thoughts.
Does Open Brain have versioned releases?
No. The repository has no GitHub releases, so there is no tagged version to pin. The default branch is main and the last push to the repository is dated 2026-11-02. The README's contribution table is stamped as last updated on 2026-08-30 and states it refreshes daily from GitHub.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/natebjones-projects-ob1)Star history chart for your README
[](https://hysenlabs.com/projects/natebjones-projects-ob1)Was this useful?