imglab: a browser-based image annotation tool for dlib, Pascal VOC and COCO exports
To speedup and simplify image labeling/ annotation process with multiple supported formats.
At a glance
- What is it?
- imglab is a browser-based annotation tool that lists dlib, Pascal VOC and COCO among its supported formats. Its README asks for maintainers; evaluate export fidelity, privacy and ongoing support against your own workflow.
- Who is it for?
- imglab can be useful for browser-based landmark and shape annotation. The README lists dlib XML, dlib pts, Pascal VOC and COCO support, but check which annotations each export preserves with representative data and your own loader.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 96 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 19, 2026, and from our analysis. They are not legal advice.
Star history
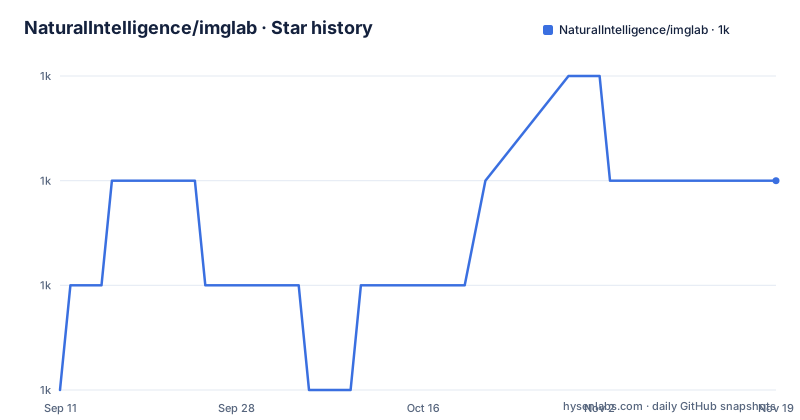
- NaturalIntelligence/imglab1,023 ★ · +2
| Repository | 2026-09-11 | 2026-11-19 |
|---|---|---|
| NaturalIntelligence/imglab | 1k | 1k |
2 Stars in the last 69 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What imglab is for and who ends up using it
imglab targets a narrow, well-defined job: turning a folder of images into labeled data that an object detector or landmark model can consume. The README describes it as "a web based tool to label images for objects that can be used to train dlib or other object detectors." The emphasis on dlib is not incidental. One of the listed features is that dlib users can "easily adjust the order of parts / landmarks / featurepoints," which matters because dlib's XML format encodes landmark positions as an ordered sequence. Reordering parts after the fact is a real workflow need for anyone building a shape predictor, and most general-purpose annotation tools treat landmark ordering as an afterthought.
The audience is therefore small teams and individuals preparing datasets for dlib-style training, plus anyone who needs Pascal VOC or COCO output without standing up a labeling server. The README also carries a first-timers-only badge and a request for maintainers, which tells you the project is positioned as a community effort rather than a product with a support path. That framing is useful context: the feature set is shaped by what contributors needed, not by an enterprise roadmap.
The mechanism: a static browser app with client-side autosave
The README states the tool is platform independent, runs directly from the browser, and has no prerequisites, with minimal CPU and memory requirements. The stated stack is jQuery, Bootstrap, Riot.js and SVG.js. That combination explains the architecture: Riot.js provides the component layer for the labeling UI, SVG.js draws and manipulates annotation shapes in the browser, and Bootstrap handles layout. There is no mention of a backend service, a database, or an account system.
The README says annotations are autosaved in browser cache and export saves to disk. It also documents plugins, including Face++; browser operation alone does not establish that every feature keeps images local. Check the specific plugin and network behavior before using sensitive data. The project file is described as small enough to share over email, and it uses the Nimn data format. That is a meaningful design choice: the intermediate representation is a compact serialization, and the four export targets (dlib XML, dlib pts, Pascal VOC, COCO) are conversions from it. Tensorflow export is listed as in plan, not implemented.
Because everything runs in the browser, the practical ceiling is the browser tab. Large image sets, high-resolution images, and long annotation sessions all live in the same memory space as the SVG rendering layer. The README does not state a tested image count or resolution limit, so that boundary is something you would have to find yourself.
Annotation primitives: points, rectangles, polygons, and what is missing
The README lists feature points and shapes (circles, rectangles, polygons) as supported, and states that "other shapes like ellipses, lines, curves will be added in the future if there is demand." That sentence is the clearest statement of scope in the whole document. If your labeling task requires ellipses or freehand curves, imglab does not currently produce them, and the README makes the addition conditional on demand rather than scheduled.
The quality-of-life features are where the tool earns its place. Any annotation shape can be dragged or resized. Any shape or landmark point can be selected and deleted. Landmark points can be reordered by dragging their label up and down rather than by creating them in a particular sequence. Image opacity can be lowered to make annotation shapes and points stand out, and tracking lines plus mouse coordinates are shown for precise placement. Hotkeys cover switching between images, tools, and labeling data.
Two features deserve separate mention. Auto-suggestion is demonstrated in a GIF, and plugins are demonstrated with Face++ (also tagged as faceplusplus and facepp in the repository topics). The README does not document the auto-suggestion algorithm or the plugin API in the text provided, so anyone planning to rely on either should read /docs/guide.md before assuming how they behave.
Getting it running: import, install, and the documented entry points
The README's usage section is short and points outward. It links to /docs/guide.md/#import for importing images and to /docs/guide.md/#offline-installation for local installation. No install commands, package names, or config keys appear in the README text itself, so I cannot give you a verified command line here. What the README does establish is that no prerequisites are required and the tool runs from the browser, which means the fastest path is the homepage at solothought.com/imglab/ rather than a local build.
The documented feature entry points are all anchors in the same guide: /docs/guide.md/#auto-suggestion, /docs/guide.md/#plugins, /docs/guide.md/#different-shapes, /docs/guide.md/#keyboard-shortcuts, and /docs/guide.md/#zooming-inout. A demo video is linked at youtu.be/Y-bJo_ylHTw. The repository also ships a Features Documentation at /docs/features.md. The README also links contribution guidance and other project resources. Its note that the legacy version was removed means older tutorials may describe a different version.
The maintainer question is the real risk, not the feature list
The README opens with a blockquote: "This project needs maintainers." Later it repeats the ask under a "Looking for inters/contributors" heading and states the only condition for becoming a maintainer is being polite to user feedback. That is an unusually candid signal. It means the project's direction depends on who shows up, and features like Tensorflow export sit in a plan state rather than a backlog with owners.
A second limitation is structural. Because annotations are autosaved in browser cache and exported manually to disk, clearing site data or switching browsers can lose work that was never exported. The README presents autosave as a convenience and export as the durable step, which is accurate, but it puts the burden of remembering to export on the annotator. For a single person labeling a few hundred images, that is fine. For a team of annotators working in parallel, there is no described mechanism for merging project files, resolving conflicts, or tracking who labeled what.
A third limitation is the shape vocabulary already noted: no ellipses, lines, or curves. And there is no mention of segmentation masks anywhere in the README.
How it differs from LabelImg and CVAT
LabelImg is a desktop image annotation tool, while imglab runs in a browser and lists landmark ordering among its features. CVAT offers a broader task and team workflow. Compare current releases against your required shapes, export formats, deployment and review process; do not assume that the same annotation types survive every format conversion.
Licence, maintenance cost, and what to check before adopting
imglab is MIT licensed, which permits commercial use, modification, and redistribution provided the copyright notice and permission notice are retained. That is a permissive licence with no copyleft obligation on your own code. It says nothing about whether the project will still work with your browser in two years, and the README's maintainer request is the relevant signal there. If you fork it, the MIT terms let you do so, and the README explicitly invites contributors.
The maintenance cost of adopting imglab is mostly the cost of verifying exports. The tool converts from its internal Nimn representation to four target formats, and format converters are where silent errors live: a swapped coordinate pair or a dropped landmark index produces a dataset that trains but trains badly. The README does not describe a validation step for exported files. So the concrete thing to verify first is round-trip fidelity: annotate one image with a known landmark order, export to dlib XML, and parse it with the same loader your training script uses. Repeat for dlib pts, Pascal VOC, and COCO. Parsing successfully is only a first check: also compare coordinates, labels, landmark order and the shapes preserved by each format against the original annotations.
Editorial conclusion
imglab can be useful for browser-based landmark and shape annotation. The README lists dlib XML, dlib pts, Pascal VOC and COCO support, but check which annotations each export preserves with representative data and your own loader. Export and back up work regularly, and review network behavior and plugin privacy before using sensitive images.
Frequently asked questions
What is imglab used for?
It labels images for training dlib or other object detectors. You draw shapes and feature points in the browser, arrange landmark order by dragging labels, and export the result. Sessions autosave into browser cache, and export is what writes to disk.
Does imglab need to be installed?
No. It runs directly from the browser, is platform independent, has no prerequisites and asks for minimal CPU and memory. An offline installation guide exists at docs/guide.md under the offline-installation section if you would rather serve the files yourself.
Which formats can imglab export?
dlib XML, dlib pts, Pascal VOC and COCO, with Tensorflow marked as in plan and no other format named. Project files use the Nimn data format and are deliberately small enough to send over mail. Shapes are limited to circles, rectangles and polygons.
What is imglab built with?
jQuery, Bootstrap, Riot.js for components and SVG.js for drawing, with HTML as the primary language of the repository. The root holds index.html, css/, js/, img/, tags/, fonts/, imglab-fonts/ and dataformaters/, plus a package-lock.json with no package.json beside it.
Is imglab still looking for contributors?
The README asks for maintainers and collaborators, with the single condition of being polite to user feedback, and notes the legacy version was removed after most users moved to the new one. The last commit on the default branch master is dated 2026-08-18 and there are no GitHub releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/naturalintelligence-imglab)Star history chart for your README
[](https://hysenlabs.com/projects/naturalintelligence-imglab)Was this useful?