cuda-oxide excludes its own directory from the workspace, and its two pipeline descriptions disagree on the number of stages
cuda-oxide is a Rust-to-CUDA compiler that lets you write (SIMT) GPU kernels in safe(ish), idiomatic Rust. It compiles standard Rust code directly to PTX — no DSLs, no foreign language bindings, just Rust.
At a glance
- What is it?
- cuda-oxide is an Apache-licensed compiler backend that lets GPU kernels be written in Rust and compiled to PTX, with host and device code in one file. Its root workspace covers four host-side crates and explicitly excludes the two nested ones, including the directory named after the project, its quickstart imports a crate the listing does not contain, and its setup section names four different compiler versions.
- Who is it for?
- Use cuda-oxide if you want to write GPU kernels in Rust with no domain-specific language and no foreign-language bindings, and if you are prepared for an alpha-stage toolchain that the README says will break its API. The single-source design is the thing worth having: host and device code in one file, one build command, and device-side abstractions for indexing, shared memory, atomics and barriers.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
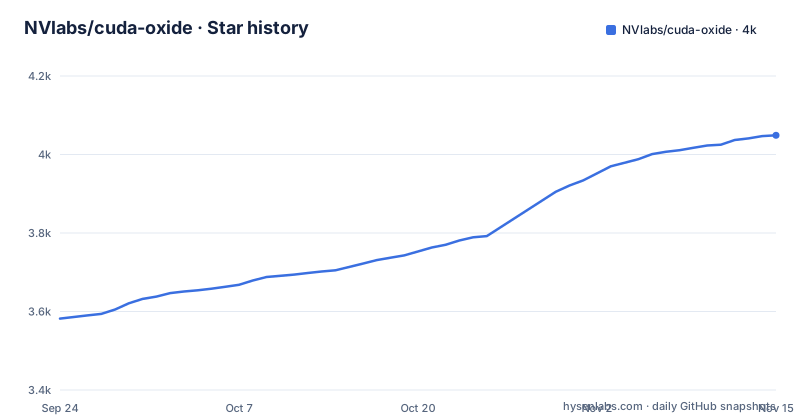
- NVlabs/cuda-oxide4,049 ★ · +467
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| NVlabs/cuda-oxide | 3.6k | 4k |
467 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The directory named after the project is excluded from its own workspace
The root manifest has four members, and an exclusion list, and the exclusion list contains the directory this repository is named after.
The four members are the host-side crates: the bindings, a core crate, a derive macro crate for that core, and an async crate. The comment above them explains that they are the stable host-side crates shared by two components, and that their metadata and dependencies stay in each crate so the root workspace does not impose the project's nightly toolchain or edition on them.
The two excluded entries are the nested workspaces. A comment says why: without the exclusion, the build tool would treat the crates underneath as part of this workspace, and the shared edition field those crates use would then resolve against a manifest that has no shared package table.
So the repository is a wrapper around two independent builds, one of which lives in a directory named after the project itself. Nothing about that is wrong, and splitting the stable host code from the nightly compiler code is a sound reason. But it means the four crates you can depend on from a registry are not the crates that compile kernels, and a reader who counts directories against manifest entries will find one more directory than members and one fewer member than directory.
The quickstart imports a crate the root listing does not contain
The first code example begins with three imports, and two of them name crates that are not in the repository listing.
The listing has four crate directories whose names match the manifest members, plus the two excluded nested workspaces. There is no directory for the device-side crate the example imports from, and none for the runtime the manifest's exclusion comment names when it explains what would break without the exclusion.
So the example pulls in a device crate and a host context crate, and neither appears at the top level. Both are presumably inside one of the nested workspaces, which means they are members of a different build than the one the root manifest describes.
That is a consequence of the arrangement above rather than a mistake in the example, and it is exactly the kind of thing that costs an afternoon. The README describes a single project that you clone and build with one command; the manifest describes a wrapper around two builds; and the example imports from a third naming scheme.
The example itself is also worth noting for what it demonstrates. It defines a generic kernel that applies any function to each element, and the comment explains that the function can be a closure with captures because the compiler monomorphises it to a concrete type. So the example is not a special case bolted onto the design: generic kernels taking closures are the design.
Two pipeline descriptions, six stages and five, and they disagree
The introduction describes the compilation pipeline once, and a subcommand's own comment describes it again, and the two do not match.
The introduction says the pipeline is rust-native, built on a third-party MLIR-like intermediate representation framework written in Rust, and gives the chain in five steps: source to the compiler's own intermediate form, to that framework's representation, to the LLVM representation, to the target.
The pipeline subcommand's comment gives six steps: the compiler's intermediate form, a dialect-specific pass, a register-promotion pass, the LLVM dialect, the LLVM representation, and the target. It never mentions the third-party framework by name.
Both are plausibly true at different altitudes: the framework may have several internal passes that the summary collapses into one arrow, and the summary may hide the pass names that the command prints. But a reader comparing them has to guess which is the actual list, and the command whose whole purpose is to show the pipeline is the one that omits the framework the project built its pipeline around.
The subcommand is otherwise the most complete description of the toolchain in the file: it also prints the generated target code for a named example, and a separate subcommand removes project-local outputs and generated artefacts.
Four compiler versions appear in one setup section
The setup section names a Clang version, an LLVM version, two more LLVM versions in a discovery list, and then a floor below which the project does not work.
The requirements ask for one Clang release and its development headers, explaining they are needed by the binding generator when building the host bindings crate. The optional LLVM section gives the matching release number, offers the upstream helper script as a fallback when the distribution does not package it, and tells you to verify target support by grepping the compiler's version output.
Then the discovery rule: the pipeline prefers the compiler shipped inside the Rust toolchain and otherwise auto-discovers three binaries on the search path, newest first, and you can pin one with an environment variable. The example of pinning uses the oldest of those three.
And a callout says the project emits several instruction-set intrinsics that the compiler from two releases earlier and before cannot handle, so anything below that is not an option.
Meanwhile the alternative shell provided by the package manager lists yet another version as its compiler.
So the file contains four numbers where one would do, and a user who installs the newest will get a different binary than a user who copies the pinning example.
The package-manager instructions point at a repository with a different name
There are four installation routes, and three of them name this repository. The fourth does not.
The first says the subcommand works out of the box inside the repository through a workspace alias. The second installs it from a git address under the organisation that owns this repository, using the pinned nightly toolchain by name. The third is the Rust toolchain itself, installed from the same pin.
The fourth is the reproducible-shell route, and its bootstrap line references a repository under a different organisation and with a different name, pointing at a subdirectory of it.
So a user who wants the reproducible environment, which is the route the file recommends as the alternative to installing anything by hand, ends up fetching a repository that is not this one.
That can be entirely deliberate. Keeping the Nix definition next to the other language bindings makes sense if the same shell is meant to serve more than one project, and the subdirectory reference suggests it does. But the file never says so, and the one sentence that introduces the route talks about a shell for this project rather than about a flake living elsewhere.
The shell itself is described well, including a hook that finds the host drivers on two different operating systems, which is the part a user on either one would otherwise have to discover.
The last subcommand's description stops mid-word
There is a block of eight subcommand examples, and the eighth has no working description.
The first seven are complete, each with a comment above it saying what it does: run an example, print the generated target code for a named example, show the pipeline, remove local outputs and generated artefacts, run correctness checks with a named checker, debug with a graphical front end, and run the language's own test suite through the backend.
The eighth comment begins by saying it compiles a crate's device code to a binary artefact of a named format, and then stops two characters into the phrase describing how long it takes.
So the block ends with a half-line, and the reader has a format name, a target and no time. For a subcommand whose whole distinction is speed, that is the one you most wanted the number for.
Two of those commands, each naming the example it runs on:
# Build and print the generated PTX
cargo oxide inspect vecadd
The block is otherwise the most useful part of the quick start, because those eight commands are the entire user-facing surface: build, inspect, trace, clean, verify, debug, test, and one more. Each one names the example it operates on, so the commands are copy-pasteable as written, which is more than most compiler backends manage.
Unsafe by default for a raw launch, safe behind an attribute
The prose under the first example explains the safety model, and it is unusually blunt about where the hole is.
The launch configuration type is described as intentionally raw data. Launching a kernel through it is an unsafe operation, and the caller has to prove that the dimensions and resources it supplies match what the kernel expects.
Then the alternative: kernels that carry a launch-contract attribute get a checked prepared-launch type instead, reached through the safe generated method.
So there are two launch paths, one safe and one not, and the difference is an attribute on the kernel. A project could have made the checked path the only path. It did not, and the reason is implied rather than stated: the raw path is what you need when the launch shape is genuinely dynamic, and a contract cannot be checked against dimensions nobody knows at compile time.
The rest of the model follows the same shape. The example is a generic kernel over any function, and the comment says closures with captures work because the compiler monomorphises them. The module attribute embeds the generated device artefact into the host binary and generates a typed launch method. And the asynchronous path hides the stream parameter, returns a lazy operation type, and defers execution until you synchronise or await.
The manifest names a component the readme never mentions
One word appears in the root manifest that appears nowhere in the readme.
The comment above the four members describes them as the stable host-side crates shared by two components. The second component is not named in the introduction, which instead describes the project's own kernels and its own host runtime.
The two nested workspaces make the shape clearer: one is the compiler backend named after this project, and the other is a separate repository the readme mentions once, as the place the shared host runtime is published from so that another project can depend on it.
So the root workspace holds code that two consumers share, one of which lives elsewhere. That is a reasonable factoring, and it means the manifest's comment is describing an arrangement that a reader of the readme has no way to infer.
Two other root entries point the same way. There is a dependency-policy configuration file and a submodules file, and neither is mentioned in the readme, so the toolchain has both a pinned toolchain file and external sources it depends on.
Editorial conclusion
Use cuda-oxide if you want to write GPU kernels in Rust with no domain-specific language and no foreign-language bindings, and if you are prepared for an alpha-stage toolchain that the README says will break its API. The single-source design is the thing worth having: host and device code in one file, one build command, and device-side abstractions for indexing, shared memory, atomics and barriers. Three things to check before you commit. What the build actually contains, because the root manifest covers four host-side crates and excludes the two nested workspaces, so the crate your kernel lives in is not a member of the workspace you cloned. Which compiler version you have, because four different majors appear in one setup section and the file states that the intrinsics it emits are not handled by the oldest of them. And how you launch a kernel, because the launch configuration type is deliberately raw data and launching through it is an unsafe operation unless the kernel carries a contract attribute.
Frequently asked questions
what is cuda oxide
It is a custom compiler backend for the Rust compiler that lets GPU kernels be written in pure Rust and compiled to CUDA PTX, with no domain-specific language and no foreign-language bindings. Host and device code live in the same file and are built with one command, functions marked with a kernel attribute are compiled to target code, and device-side abstractions cover type-safe indexing, shared memory, scoped atomics, barriers and warp-level operations. The README states it is at alpha stage, under active development, and expects bugs, incomplete features and API breakage.
What does cuda-oxide require in order to build?
A pinned nightly Rust toolchain with three named components installed and pinned in a toolchain file, the CUDA toolkit at a stated minimum including its random-number headers, Clang plus its development headers because a binding generator needs them for the host bindings crate, and Linux, tested on one distribution. A driver requirement is stated as well, because the shared bindings crate loads the driver library at run time. Every install route in the file is a Linux route.
Is launching a kernel from cuda-oxide safe?
Not through the plain path. The launch configuration type is described as intentionally raw data, so launching with it is unsafe and the caller must prove that the dimensions and resources match the kernel. Kernels that carry a launch-contract attribute instead get a checked prepared-launch type through the safe generated method, so the attribute is what decides which of the two paths you get.
Which compiler version does cuda-oxide need?
The file names four. The requirements ask for one Clang release and the optional install section gives the matching LLVM release, the reproducible shell provides a newer one, and the pipeline auto-discovers three binaries newest-first with an environment variable to pin one, the pinning example naming the oldest of the three. A callout also says the project emits intrinsics that the compiler from two releases earlier cannot handle, so anything below that floor will not work.
How does the cuda-oxide compilation pipeline work?
Two descriptions in the same file do not match. The introduction gives five stages ending in the target, passing through the compiler's own intermediate form and an MLIR-like framework written in Rust before the LLVM representation. The pipeline subcommand's own comment gives six stages, inserting a dialect-specific pass and a register-promotion pass and the LLVM dialect, and never naming that framework.
Does cuda-oxide support Windows?
The stated requirement is Linux, tested on one distribution, and every installation route in the file is a Linux route: a git install with a pinned nightly toolchain, a reproducible shell with a driver-discovery hook, a manual toolchain install, and a manual toolkit setup. The README does not discuss other operating systems at all.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-cuda-oxide)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-cuda-oxide)Was this useful?