KDA's setup instructions clone a different repository than the one you read
Kernel Design Agents (KDA) is a agent-centric workflow to write high-performance CUDA Kernels.
At a glance
- What is it?
- An agent-centric workflow for using coding agents to research, implement, verify and iterate on performance-sensitive CUDA kernels, shipped as documentation, prompt templates and pinned submodules rather than as a library. The quick start clones another repository, the licence section names two licences and points both at one file, and the community wishlist is a pull request to a branch rather than an issue.
- Who is it for?
- Kernel Design Agents is a workflow description rather than a tool, and the valuable part is how much of its discipline is written down: a task contract with a validation command and promotion criteria agreed before any code, small iterations verified each time, and artefacts that let another engineer see what was tried and why a candidate won. Two things to check before adopting it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 26 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
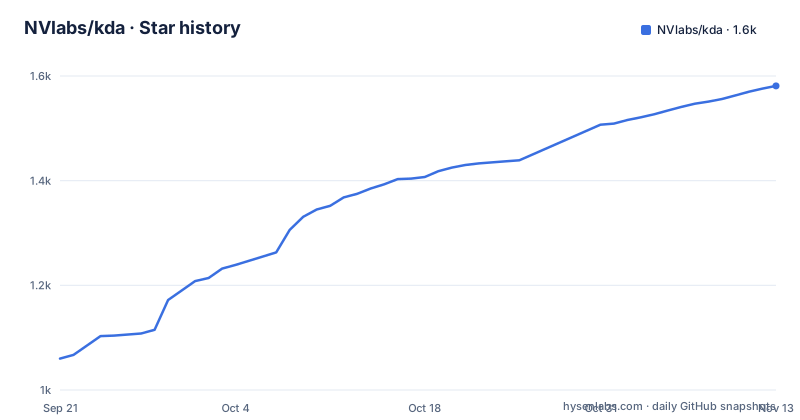
Star history
- NVlabs/kda1,581 ★ · +521
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| NVlabs/kda | 1.1k | 1.6k |
521 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The quick start clones a repository that is not this one
The getting started block tells you to install the agent workflow dependencies, and the command it gives you is:
git clone --recurse-submodules https://github.com/mit-han-lab/kernel-design-agents.git
cd kernel-design-agents

# link skills
mkdir -p ~/.claude/skills
ln -s "$(pwd)/skills/ncu-report-skill" ~/.claude/skills/ncu-report-skill
ln -s "$(pwd)/skills/KernelWiki" ~/.claude/skills/KernelWiki

# or clone the independently licensed ncu skill directly
mkdir -p ~/.claude/skills && cd ~/.claude/skills
git clone https://github.com/mit-han-lab/ncu-report-skill.git
The repository being cloned is mit-han-lab/kernel-design-agents, not the one you are reading, which lives under NVlabs. Two lines further down the text says to use KernelWiki from this repository's pinned submodule, which points back at the document's own repository. Both repositories carry a skills directory and a .gitmodules, so the path resolves either way, but a reader who follows the commands literally ends up somewhere other than where the documentation around them lives.
Two licences, one LICENSE file, and no name in the metadata
The licence section splits first-party content in two: documentation, prompts, skills-style content and assets under the Creative Commons Attribution 4.0 International License, and first-party source code under the Apache License 2.0. Both sentences link to the same file, the one named LICENSE at the root. A single file cannot be both, so one of the two statements is describing something the file does not contain, and a reader has no way to tell which. The project metadata names no licence at all, which is consistent with the file being hard to classify rather than with the repository being unlicensed. On top of that, the submodules are explicitly excluded: the text states they are not covered by the first-party licence and points to THIRD_PARTY_NOTICES.md and a directory of verbatim upstream licence files instead.
The KernelWiki submodule is a sanitized copy, not the upstream commit
The submodule table is the most careful document in the repository, and it contains a detail worth reading twice. KernelWiki is pinned not to a raw upstream commit but to something based on one, with the note that the revision reflects repository-maintained release sanitization recorded by the gitlink. The licence cell spells out the consequence: MIT for the original material, embedded artifacts retaining their own upstream terms, and restricted CuTe DSL artifacts omitted entirely. A few lines earlier the getting started section says the same thing in prose, warning that a direct upstream checkout may contain artifact snapshots governed by additional terms which are omitted from this distribution. So cloning upstream yourself gets you different content from what the submodule gives you, by design.
The wishlist is a pull request to a branch, and only two GPU families qualify
Community kernel requests do not go through issues. The instructions say to submit a request directly as a pull request to the `wishlist` branch, with a reproducible definition, representative workloads and a best-known baseline implementation, and to state plainly that no issue is required. Details live in a path built from the requester's GitHub username and the kernel name, and the wishlist pull request template supplies a short description. Merging records the request while optimisation progress and result links stay on the original pull request. The scope is narrow and stated in the same paragraph: the community wishlist supports NVIDIA B200 and B300 GPUs only. Three long-lived branches are implied throughout, with `main` holding the pull request template and issue chooser settings and `pages` holding the website source.
Implementation work is supposed to happen somewhere else
The repository holds documentation, prompts, agent instructions, licences and submodules, with no source directory at the top level and no primary language recorded. The recommended layout makes the intent explicit: use this repository as reference material, then do the implementation work elsewhere, in a task workspace with a docs directory for the draft and the plan, runs, outputs, a profile directory, a benchmark.csv and a candidates.jsonl. The file list is explicitly allowed to change by domain, and the one rule attached to it is that the agent must record enough context for another engineer to understand what was tried, what passed validation and why the final candidate was selected. Everything else, including evaluators, datasets and profiling tools, is left to the downstream task, and the workflow is described as intentionally independent of any single benchmark harness or hardware target. That independence is real at the workflow level and narrow at the community level, since the wishlist that feeds it accepts B200 and B300 requests only.
Eight steps, and the promotion criteria are agreed before the code
The minimal flow is eight numbered steps and the ordering is the point. Create a separate implementation workspace for the target task, then define the task contract: objective, constraints, a validation command and promotion criteria. Only after that do you start an agent session, hand it the generic starter prompt `prompts/basic-flow.md` filled in with task details, and ask it to write a short plan draft to `docs/draft.md` in the workspace. The draft becomes an executable plan, manually or with a planning tool such as Humanize, and then implementation proceeds in small iterations with verification after each meaningful change. The last step is bookkeeping: candidates, benchmark or evaluation results, profiling evidence and the final promotion decisions.
The performance evidence and the planning tool both live elsewhere
Two dependencies point outside this repository. The first is evidence: the introduction says that if you want to know about solutions ranking first to third on tracks at the MLSys Kernel Contest, performance evaluation and reproduction live in a separate repository, mit-han-lab/mlsys2026-flashinfer-contest. So the rankings are not demonstrated here, only linked. The second is tooling: converting a plan draft into an executable plan can use Humanize, installed by adding a third-party marketplace from a different organisation with two commands. Both are reasonable choices for a research prototype, and both mean a workflow that looks self-contained is not. Worth knowing before you decide the workflow is turnkey.
Editorial conclusion
Kernel Design Agents is a workflow description rather than a tool, and the valuable part is how much of its discipline is written down: a task contract with a validation command and promotion criteria agreed before any code, small iterations verified each time, and artefacts that let another engineer see what was tried and why a candidate won. Two things to check before adopting it. The setup path clones a different repository than the one hosting the document, so read the submodule table before typing anything, and note that KernelWiki is a sanitized version of upstream rather than the upstream commit itself. On licensing, first-party content is described as CC-BY-4.0 with source as Apache 2.0, both pointing at one file, while the submodules sit outside that entirely, so establish which terms apply to whatever you actually ship.
Frequently asked questions
What is NVlabs/kda?
Kernel Design Agents, an agent-centric workflow for using coding agents to research, implement, verify and iterate on performance-sensitive CUDA kernel tasks. The repository documents an early research prototype and holds documentation, prompt templates, repository-facing agent instructions and pinned submodules rather than a library you install.
How do I set up the KDA agent workflow?
The documented steps clone mit-han-lab/kernel-design-agents with `--recurse-submodules`, create a skills directory, and symlink `skills/ncu-report-skill` and `skills/KernelWiki` into it, or clone the independently licensed ncu skill directly. Note that the clone URL names a different repository than the one hosting the readme.
What licence applies to NVlabs/kda?
The readme states that first-party documentation, prompts, skills-style content and assets are under CC-BY-4.0 while first-party source code is under Apache 2.0, and both statements link to the same LICENSE file. The third-party submodules are explicitly outside that first-party licence, and the project metadata records no licence name.
Which GPUs does the KDA community wishlist support?
NVIDIA B200 and B300 only, as stated in the wishlist section. Requests are submitted as pull requests to the `wishlist` branch rather than issues, with a reproducible definition, representative workloads and a best-known baseline implementation, and merging records the request while progress stays on the original pull request.
Where are the KDA submodule licences recorded?
In THIRD_PARTY_NOTICES.md, with verbatim upstream licence files under `third_party_licenses/`. The submodule table records KernelWiki as MIT for original material with embedded artifacts retaining their upstream terms and restricted CuTe DSL artifacts omitted, and the ncu report skill as MIT.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-kda)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-kda)Was this useful?