ai-system-design-guide is twenty numbered chapters and a link table, with no release to pin
AI system design guide for engineers building production AI systems and evals.
At a glance
- What is it?
- An MIT licensed, Markdown-only reference on building production AI systems, aimed squarely at interview preparation and organised as twenty numbered directories from interview prep through to multimodal generation. The content is broad and the navigation is careful, but three structural facts are worth knowing before you rely on it. There are no GitHub releases, so a guide that describes itself as continuously updated cannot be pinned. Several chapter filenames carry a year. And two of the root files are near-duplicate evals guides that differ by one product each.
- Who is it for?
- Treat this as a map rather than a manual. Its own navigation is the strongest part, twenty chapters with explicit learning paths for retrieval, agents, evaluation, cost and governance, and a chapter that openly discusses how fast framework tutorials go stale.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
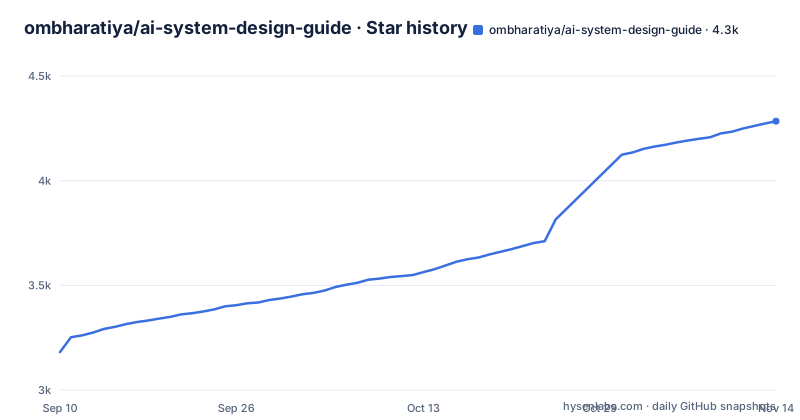
- ombharatiya/ai-system-design-guide4,284 ★ · +1,103
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| ombharatiya/ai-system-design-guide | 3.2k | 4.3k |
1,103 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Twenty numbered chapters, and the README is almost entirely a link table
The repository is twenty numbered directories and eight Markdown files, with no code in it at all.
The directories run from `00-interview-prep/` to `19-multimodal-generation/`: interview prep, foundations, model landscape, training and adaptation, inference optimization, prompting and context, retrieval systems, agentic systems, memory and state, frameworks and tools, document processing, infrastructure and mlops, security and access, reliability and safety, evaluation and observability, design patterns, case studies, tool use and computer agents, voice and audio agents, and multimodal generation.
The numbering starts at zero because interview preparation is treated as the front door, not as an appendix. Two orderings inside it are deliberate. Retrieval is chapter six and agents chapter seven, so retrieval-augmented generation is taught before agentic systems rather than after. And design patterns sits at fifteen, after security, reliability and evaluation, which is an unusual place for patterns to appear since they are usually taught before the operational concerns a pattern is meant to address.
At the root there are eight files: a glossary, a courses list, a research radar, a patterns document, a role transition guide, a contributing guide, and two evals guides discussed below. Six of those root files use hyphens in their names, while the two evals guides use low lines as separators, so the same level of the repository uses two naming conventions.
The README itself is close to a pure index. Its navigation table has around twenty-nine rows, each a stated goal paired with one to four chained file links, and the explanatory prose amounts to two sentences.
Two evals guides that differ by one product each
Two files at the repository root cover the same subject, and the navigation table offers no guidance on which to read or how they differ.
One is a comprehensive study guide whose nav row names Phoenix and Langfuse. The other is a complete guide whose nav row names LangWatch and Langfuse. Both are described in the table as an AI Evals Guide, and both filenames sit at the root rather than inside the evaluation chapter, with long descriptive names built from the same phrase.
So the overlap is one product and the difference is the other one. Langfuse appears in both. The first pairs it with Phoenix, the second with LangWatch.
Three things follow. A reader who wants an evaluation stack has two documents to choose between with no stated criterion for choosing. A reader who wants to compare the two non-shared products has no single document that does it. And a maintainer updating evaluation guidance has two places to update, one of which is not inside the numbered chapter that the table's own ordering would suggest belongs there.
The naming makes the collision worse rather than better, since two long lowercase filenames separated by low lines that differ by a few characters are easy to confuse in a directory listing and impossible to tell apart from a truncated view.
The evaluation chapter itself does exist as a numbered directory, so the subject is covered in the curriculum too. What is at the root are two product-shaped long reads that sit outside that structure.
Three commercial funnels sit above the first line of content
The opening block of the README is promotion, and it comes before any description of the guide's contents.
Three outbound links appear first. One goes to the project's own site, described in the surrounding text as offering instant search across the guide. One goes to a booking page for one-to-one mock interviews and mentorship, and the same service is offered on a second named platform. The third is the author's GitHub profile.
Alongside them the text asks you to star the repository to support the work, and a separate bolded paragraph asks you to follow the author on three social platforms in order to be notified when new chapters, model refreshes and interview prompts ship.
So the stated reasons to follow the project are new chapters, refreshed model information, and new interview prompts. That third item is worth pausing on, because it tells you the interview content is treated as a recurring product rather than a settled document.
None of this is hidden, which is to the author's credit. The guide is MIT licensed, contains no paywall, and links to the paid offering rather than disguising it as documentation. But it does tell you something about how the project is sustained, and therefore about why the pitch is continuous updating: someone is being paid to maintain it, and the funnel to that person is the first thing in the file.
The recorded homepage for the repository is the same site as the first link, so the project is not pretending to be anything other than a personal reference with a business attached.
Year-stamped filenames inside a guide that calls itself continuously updated
Several parts of this repository carry a year in the name, and that is a structural commitment the project cannot keep.
The navigation table has rows labelled for the current year in two places: one for picking a model and one for tracking frontier research. A third row points at a job market document whose filename carries the year as a suffix. A chapter on reinforcement learning with verifiable rewards describes in its own parenthetical how specific named model families are trained.
The mismatch is between a filename and a promise. A file named for one year is a claim about that year, and it cannot be correct next year without either renaming, which breaks every link pointing at it, or silently becoming wrong, which is worse for a document people cite.
The project is aware of the general problem. It argues that readers should rely on the official documentation for specific features, prices and account capabilities, and that the guide is for structure and workflow rather than volatile specifics. The navigation table reinforces that by pointing evaluation, cost control and governance readers at conceptual chapters rather than price lists.
So the year-stamped files are the exception to an otherwise sensible editorial policy, and they are the exception precisely because they are the parts a reader is most tempted to quote. If you are citing this material, the year-stamped chapters are the ones to re-check before you rely on them, and there is no release to tell you which revision you are looking at.
One chapter exists because framework tutorials go stale
There is a chapter in the frameworks directory whose stated subject is the staleness of other material, and that is unusual enough to be worth reading on its own.
The navigation row for it is framed as surviving framework version churn, and the parenthetical names the three things it covers: stale tutorials, version pinning, and what to actually learn. So the guide contains an explicit argument about how much of the surrounding ecosystem documentation should be trusted and when.
The same directory holds the content that argument is about. One page covers a specific orchestration framework, another covers one named coding agent product, and another is a landscape page for a different open coding project. Plus the meta-chapter itself. That is three vendor-shaped or framework-shaped documents sitting next to one document about why those documents expire, inside a project that also promises refreshed model information as a reason to follow it.
The autonomous coding agents row makes the shape visible in the table itself, chaining from a landscape page to one product's deep dive, and the tool-use row chains a landscape page to a specific project and then to a safety and governance page.
There is also a voice row that ends by pointing back into the interview question bank at an anchor for voice questions, which is the clearest example in the repository of one document deliberately cross-linked from another rather than duplicated.
Nav rows are uneven, so you cannot judge a chapter before opening it
The navigation table is careful in one way and inconsistent in another, and the inconsistency limits how useful it is for triage.
Some rows describe what you will get. The benchmarks row names saturation, contamination and harness variance. The governance row names the EU AI Act and the NIST risk management framework and adds what to implement. The voice agents row names the choice between a pipeline and speech-to-speech and a duplex front end, plus latency and cost per minute. The gateways row names fallback, rate limits and one specific routing product. The cost row names caching, batch, attribution and unit economics. The on-device row contrasts two serving tools and covers quantization and hardware. Durable execution names replay, exactly-once semantics and Temporal. The data engineering row names ingestion, deduplication, personally identifiable information and decontamination.
Other rows are bare. The production RAG row chains four files with no description at all. The advanced retrieval row chains three files with no description. Contextual retrieval, late interaction and multi-modal retrieval are bare links.
So the table tells you the shape of roughly half the chapters and nothing about the other half. If you are scanning for a topic you already understand, the described rows save you a click. If you are scanning for a topic you do not understand, an undescribed row might be a three-page primer or a fifty-page treatise, and you cannot tell which without opening it.
That is the cost of a table wide enough to be genuinely useful as a map. Twenty-nine rows is a lot of surface, and the descriptions were clearly added where someone thought a reader would be stuck.
Use the navigation and pin a revision
The README offers navigation into the guide's topics and learning paths. For a stable citation, record the repository commit and the specific file; the current branch may change after you read it. Verify time-sensitive product, pricing and capability claims against their primary sources.
Editorial conclusion
Treat this as a map rather than a manual. Its own navigation is the strongest part, twenty chapters with explicit learning paths for retrieval, agents, evaluation, cost and governance, and a chapter that openly discusses how fast framework tutorials go stale. That makes it a good way to find the area you are weak in, then a poor substitute for the primary documentation of whichever product you end up using. Four checks before you lean on it. Record a Git commit when citing the guide, since its contents change over time. Which evals guide to read, since two root documents cover the same ground and differ only in which tool they profile alongside a shared one. Whether the year-stamped chapters still describe the current landscape, since a filename carrying a year is a promise the project cannot keep across more than one. And whether the pitch about being interview-ready matches your goal, because that framing runs through the whole structure.
Frequently asked questions
How to prepare for an AI system design interview?
The guide routes this to its own interview chapter: a question bank it names as containing 147 questions, followed by a separate document of answer frameworks. Its positioning is explicitly interview-oriented, with case studies drawn from staff-level interviews, and it also contains a chapter on the current job market and an FAQ chapter covering seven topics.
What is the best book for learning about AI system design?
This repository is not a book. It is an MIT licensed set of twenty numbered Markdown directories plus eight files at the root, with no releases and no downloadable PDF, and it points readers to its own COURSES.md for recommended courses and learning paths rather than naming a single text as best.
What is the best AI tool for system design?
The repository does not rank tools. It maps a path through its own chapters and named products: an orchestration framework guide, a page on one specific coding agent, a landscape page for a different coding project, an AI gateways and model routing chapter naming LiteLLM, and an on-device chapter contrasting Ollama with vLLM. It also contains a chapter on navigating framework version churn that addresses how much of that material to trust.
How is the ai-system-design-guide organized?
Into twenty numbered directories running from `00-interview-prep/` through `19-multimodal-generation/`, so retrieval systems are chapter six and agentic systems chapter seven, with security and access at twelve, reliability and safety at thirteen, and evaluation and observability at fourteen. Eight further Markdown files sit at the root, including a glossary, a courses list, a research radar, a role transition guide, a patterns document and two separate evals guides.
Why are there two AI evals guides in ai-system-design-guide?
Two root-level documents cover evaluation, and the navigation table labels both as an AI Evals Guide. One names Phoenix and Langfuse, the other names LangWatch and Langfuse, so they share one product and differ on the other. The table does not say which to read first or how the two differ, and neither file sits inside the numbered evaluation chapter.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ombharatiya-ai-system-design-guide)Star history chart for your README
[](https://hysenlabs.com/projects/ombharatiya-ai-system-design-guide)Was this useful?